
MapReduce编程系列 — 1:计算单词
1、代码:
package com.mrdemo;

import java.io.IOException;

import java.util.StringTokenizer;

import org.apache.hadoop.conf.Configuration;

import org.apache.hadoop.fs.Path;

import org.apache.hadoop.io.IntWritable;

import org.apache.hadoop.io.Text;

import org.apache.hadoop.mapreduce.Job;

import org.apache.hadoop.mapreduce.Mapper;

import org.apache.hadoop.mapreduce.Reducer;

import org.apache.hadoop.mapreduce.lib.input.FileInputFormat;

import org.apache.hadoop.mapreduce.lib.output.FileOutputFormat;

import org.apache.hadoop.util.GenericOptionsParser;

public class WordCount {

  public static class TokenizerMapper

       extends Mapper<Object, Text, Text, IntWritable>{

    private final static IntWritable one = new IntWritable(1);

    private Text word = new Text();

    public void map(Object key, Text value, Context context

                    ) throws IOException, InterruptedException {

      StringTokenizer itr = new StringTokenizer(value.toString());

      while (itr.hasMoreTokens()) {

        word.set(itr.nextToken());

        context.write(word, one);

      }

    }

  }

  public static class IntSumReducer

       extends Reducer<Text,IntWritable,Text,IntWritable> {

    private IntWritable result = new IntWritable();

    public void reduce(Text key, Iterable<IntWritable> values,

                       Context context

                       ) throws IOException, InterruptedException {

      int sum = 0;

      for (IntWritable val : values) {

        sum += val.get();

      }

      result.set(sum);

      context.write(key, result);

    }

  }

  public static void main(String[] args) throws Exception {

    Configuration conf = new Configuration();

    String[] otherArgs = new GenericOptionsParser(conf, args).getRemainingArgs();

    if (otherArgs.length != 2) {

      System.err.println("Usage: wordcount <in> <out>");

      System.exit(2);

    }

    //conf.set("fs.defaultFS", "hdfs://192.168.6.77:9000");

    Job job = new Job(conf, "word count");

    job.setJarByClass(WordCount.class);

    job.setMapperClass(TokenizerMapper.class);

    job.setCombinerClass(IntSumReducer.class);

    job.setReducerClass(IntSumReducer.class);

    job.setOutputKeyClass(Text.class);

    job.setOutputValueClass(IntWritable.class);

    FileInputFormat.addInputPath(job, new Path(otherArgs[0]));

    FileOutputFormat.setOutputPath(job, new Path(otherArgs[1]));

    System.exit(job.waitForCompletion(true) ? 0 : 1);

  }

}
2、准备测试数据。
hello hadoop
jobtracker
maptracker
reducetracker
task
namenode
datanode
block
beautiful world
hadoop:
HDFS
MapReduce
3、命令
hdfs://localhost:9000/user/yyq/output01
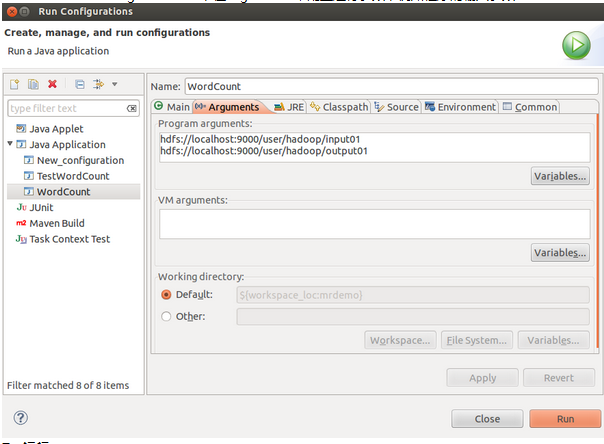
4、配置运行参数
Run As → Run Configurations… ,在Arguments中配置运行参数,例如程序的输入参数:
MapReduce编程系列 — 1:计算单词的更多相关文章
- MapReduce编程系列 — 2:计算平均分
1.项目名称: 2.程序代码: package com.averagescorecount; import java.io.IOException; import java.util.Iterator ...
- 【原创】MapReduce编程系列之二元排序
普通排序实现 普通排序的实现利用了按姓名的排序,调用了默认的对key的HashPartition函数来实现数据的分组.partition操作之后写入磁盘时会对数据进行排序操作(对一个分区内的数据作排序 ...
- MapReduce编程系列 — 6:多表关联
1.项目名称: 2.程序代码: 版本一(详细版): package com.mtjoin; import java.io.IOException; import java.util.Iterator; ...
- MapReduce编程系列 — 5:单表关联
1.项目名称: 2.项目数据: chile parentTom LucyTom JackJone LucyJone JackLucy MaryLucy Ben ...
- MapReduce编程系列 — 4:排序
1.项目名称: 2.程序代码: package com.sort; import java.io.IOException; import org.apache.hadoop.conf.Configur ...
- MapReduce编程系列 — 3:数据去重
1.项目名称: 2.程序代码: package com.dedup; import java.io.IOException; import org.apache.hadoop.conf.Configu ...
- 【原创】MapReduce编程系列之表连接
问题描述 需要连接的表如下:其中左边是child,右边是parent,我们要做的是找出grandchild和grandparent的对应关系,为此需要进行表的连接. Tom Lucy Tom Jim ...
- MapReduce 编程 系列九 Reducer数目
本篇介绍怎样控制reduce的数目.前面观察结果文件,都会发现通常是以part-r-00000 形式出现多个文件,事实上这个reducer的数目有关系.reducer数目多,结果文件数目就多. 在初始 ...
- MapReduce 编程 系列七 MapReduce程序日志查看
首先,假设须要打印日志,不须要用log4j这些东西,直接用System.out.println就可以,这些输出到stdout的日志信息能够在jobtracker网站终于找到. 其次,假设在main函数 ...
随机推荐
- JVM系列三:JVM参数设置、分析(转载)
不管是YGC还是Full GC,GC过程中都会对导致程序运行中中断,正确的选择不同的GC策略,调整JVM.GC的参数,可以极大的减少由于GC工作,而导致的程序运行中断方面的问题,进而适当的提高Java ...
- 【转】DataGridView显示行号
ref:http://blog.csdn.net/xieyufei/article/details/9769631 方法一: 网上最常见的做法是用DataGridView的RowPostPaint事件 ...
- ajaxFileUpload - Post file and data together
jQuery.extend({ createUploadIframe: function(id, uri) { //create frame var frameId = 'jUploadFrame' ...
- wamp Server2.5 配置 自定义目录
煎熬了两天终于找到了方法!!! 前提先改成中文 右键"W"图表-> Language -> chinese; 成功改为中文. 自定义目录步骤: 一.添加一个Alias ...
- DOM基础总结
一.简介 1.什么是DOM 文档对象模型(Document Object Model,DOM)是一种用于HTML和XML文档的编程接口.它给文档提供了一种结构化的表示方法,可以改变文档的内容和呈现方式 ...
- python 对象持久化 pickle模块
用到python 序列化 比如我们可以把一些配置的信息放到数组,字典或者做为类的属性,然后对数据进行 序列化,再把序列化好的数据放到文件里或者直接放到数据库里,这样可以方便下次要用数据的时候 对数据进 ...
- Django开发网站(二)
第一课:视图显示 1 建立一个项目:django-admin startproject blog, 进入blog: cd blog 显示:blog(__init__.py settings.py ...
- 【原创】一起学C++ 之指针、数组、指针算术 ---------C++ primer plus(第6版)
C++ Primer Plus 第6版 指针和数组基本等价的原因在于指针算术! 一.指针 ⑴整数变量+1后,其值将增加1: ⑵指针变量+1后,增加的量等于它指向的类型的字节数: ⑶C++将数组名解析为 ...
- DOM初涉
document documentURI, URL 返回当前网页的URL(String) activeElement 返回当前得到焦点的标签,input, textarea等比较常见,否则返回body ...
- 【 socke】C# socket端口复用-多主机头绑定
什么是端口复用: 因为在winsock的实现中,对于服务器的绑定是可以多重绑定的,在确定多重绑定使用谁的时候,根据一条原则是谁的指定最明确则将包递交给谁,而且没有权限之分.这种多重绑定便称之为端口复用 ...