
词性标注 parts of speech tagging
sklearn实战-乳腺癌细胞数据挖掘(博客主亲自录制视频教程)
https://study.163.com/course/introduction.htm?courseId=1005269003&utm_campaign=commission&utm_source=cp-400000000398149&utm_medium=share
In corpus linguistics, part-of-speech tagging (POS tagging or POST), also called grammatical tagging or word-category disambiguation, is the process of marking up a word in a text (corpus) as corresponding to a particular part of speech, based on both its definition and its context—i.e., its relationship with adjacent and related words in a phrase, sentence, or paragraph. A simplified form of this is commonly taught to school-age children, in the identification of words as nouns, verbs, adjectives, adverbs, etc.
Once performed by hand, POS tagging is now done in the context of computational linguistics, using algorithms which associate discrete terms, as well as hidden parts of speech, in accordance with a set of descriptive tags. POS-tagging algorithms fall into two distinctive groups: rule-based and stochastic. E. Brill's tagger, one of the first and most widely used English POS-taggers, employs rule-based algorithms.
Contents
Principle
Part-of-speech tagging is harder than just having a list of words and their parts of speech, because some words can represent more than one part of speech at different times, and because some parts of speech are complex or unspoken. This is not rare—in natural languages (as opposed to many artificial languages), a large percentage of word-forms are ambiguous. For example, even "dogs", which is usually thought of as just a plural noun, can also be a verb:
- The sailor dogs the hatch.
Correct grammatical tagging will reflect that "dogs" is here used as a verb, not as the more common plural noun. Grammatical context is one way to determine this; semantic analysis can also be used to infer that "sailor" and "hatch" implicate "dogs" as 1) in the nautical context and 2) an action applied to the object "hatch" (in this context, "dogs" is a nautical term meaning "fastens (a watertight door) securely").
Schools commonly teach that there are 9 parts of speech in English: noun, verb, article, adjective, preposition, pronoun, adverb, conjunction, and interjection. However, there are clearly many more categories and sub-categories. For nouns, the plural, possessive, and singular forms can be distinguished. In many languages words are also marked for their "case" (role as subject, object, etc.), grammatical gender, and so on; while verbs are marked for tense, aspect, and other things. Linguists distinguish parts of speech to various fine degrees, reflecting a chosen "tagging system".
In part-of-speech tagging by computer, it is typical to distinguish from 50 to 150 separate parts of speech for English. For example, NN for singular common nouns, NNS for plural common nouns, NP for singular proper nouns (see the POS tags used in the Brown Corpus). Work on stochastic methods for tagging Koine Greek (DeRose 1990) has used over 1,000 parts of speech, and found that about as many words were ambiguous there as in English. A morphosyntactic descriptor in the case of morphologically rich languages is commonly expressed using very short mnemonics, such as 'Ncmsan for Category=Noun, Type = common, Gender = masculine, Number = singular, Case = accusative, Animate = no.
History
The Brown Corpus
Research on part-of-speech tagging has been closely tied to corpus linguistics. The first major corpus of English for computer analysis was the Brown Corpus developed at Brown University by Henry Kučera and W. Nelson Francis, in the mid-1960s. It consists of about 1,000,000 words of running English prose text, made up of 500 samples from randomly chosen publications. Each sample is 2,000 or more words (ending at the first sentence-end after 2,000 words, so that the corpus contains only complete sentences).
The Brown Corpus was painstakingly "tagged" with part-of-speech markers over many years. A first approximation was done with a program by Greene and Rubin, which consisted of a huge handmade list of what categories could co-occur at all. For example, article then noun can occur, but article verb (arguably) cannot. The program got about 70% correct. Its results were repeatedly reviewed and corrected by hand, and later users sent in errata, so that by the late 70s the tagging was nearly perfect (allowing for some cases on which even human speakers might not agree).
This corpus has been used for innumerable studies of word-frequency and of part-of-speech, and inspired the development of similar "tagged" corpora in many other languages. Statistics derived by analyzing it formed the basis for most later part-of-speech tagging systems, such as CLAWS (linguistics) and VOLSUNGA. However, by this time (2005) it has been superseded by larger corpora such as the 100 million word British National Corpus.
For some time, part-of-speech tagging was considered an inseparable part of natural language processing, because there are certain cases where the correct part of speech cannot be decided without understanding the semantics or even the pragmatics of the context. This is extremely expensive, especially because analyzing the higher levels is much harder when multiple part-of-speech possibilities must be considered for each word.
Use of Hidden Markov Models
In the mid 1980s, researchers in Europe began to use hidden Markov models (HMMs) to disambiguate parts of speech, when working to tag the Lancaster-Oslo-Bergen Corpus of British English. HMMs involve counting cases (such as from the Brown Corpus), and making a table of the probabilities of certain sequences. For example, once you've seen an article such as 'the', perhaps the next word is a noun 40% of the time, an adjective 40%, and a number 20%. Knowing this, a program can decide that "can" in "the can" is far more likely to be a noun than a verb or a modal. The same method can of course be used to benefit from knowledge about following words.
More advanced ("higher order") HMMs learn the probabilities not only of pairs, but triples or even larger sequences. So, for example, if you've just seen a noun followed by a verb, the next item may be very likely a preposition, article, or noun, but much less likely another verb.
When several ambiguous words occur together, the possibilities multiply. However, it is easy to enumerate every combination and to assign a relative probability to each one, by multiplying together the probabilities of each choice in turn. The combination with highest probability is then chosen. The European group developed CLAWS, a tagging program that did exactly this, and achieved accuracy in the 93-95% range.
It is worth remembering, as Eugene Charniak points out in Statistical techniques for natural language parsing (1997) [2], that merely assigning the most common tag to each known word and the tag "proper noun" to all unknowns will approach 90% accuracy because many words are unambiguous.
CLAWS pioneered the field of HMM-based part of speech tagging, but was quite expensive since it enumerated all possibilities. It sometimes had to resort to backup methods when there were simply too many options (the Brown Corpus contains a case with 17 ambiguous words in a row, and there are words such as "still" that can represent as many as 7 distinct parts of speech (DeRose 1990, p. 82)).
HMMs underlie the functioning of stochastic taggers and are used in various algorithms one of the most widely used being the bi-directional inference algorithm.[1]
Dynamic programming methods
In 1987, Steven DeRose[2] and Ken Church[3] independently developed dynamic programming algorithms to solve the same problem in vastly less time. Their methods were similar to the Viterbi algorithm known for some time in other fields. DeRose used a table of pairs, while Church used a table of triples and a method of estimating the values for triples that were rare or nonexistent in the Brown Corpus (actual measurement of triple probabilities would require a much larger corpus). Both methods achieved accuracy over 95%. DeRose's 1990 dissertation at Brown University included analyses of the specific error types, probabilities, and other related data, and replicated his work for Greek, where it proved similarly effective.
These findings were surprisingly disruptive to the field of natural language processing. The accuracy reported was higher than the typical accuracy of very sophisticated algorithms that integrated part of speech choice with many higher levels of linguistic analysis: syntax, morphology, semantics, and so on. CLAWS, DeRose's and Church's methods did fail for some of the known cases where semantics is required, but those proved negligibly rare. This convinced many in the field that part-of-speech tagging could usefully be separated out from the other levels of processing; this in turn simplified the theory and practice of computerized language analysis, and encouraged researchers to find ways to separate out other pieces as well. Markov Models are now the standard method for part-of-speech assignment.
Unsupervised taggers
The methods already discussed involve working from a pre-existing corpus to learn tag probabilities. It is, however, also possible to bootstrap using "unsupervised" tagging. Unsupervised tagging techniques use an untagged corpus for their training data and produce the tagset by induction. That is, they observe patterns in word use, and derive part-of-speech categories themselves. For example, statistics readily reveal that "the", "a", and "an" occur in similar contexts, while "eat" occurs in very different ones. With sufficient iteration, similarity classes of words emerge that are remarkably similar to those human linguists would expect; and the differences themselves sometimes suggest valuable new insights.
These two categories can be further subdivided into rule-based, stochastic, and neural approaches.
Other taggers and methods
Some current major algorithms for part-of-speech tagging include the Viterbi algorithm, Brill Tagger, Constraint Grammar, and the Baum-Welch algorithm (also known as the forward-backward algorithm). Hidden Markov model and visible Markov model taggers can both be implemented using the Viterbi algorithm. The rule-based Brill tagger is unusual in that it learns a set of rule patterns, and then applies those patterns rather than optimizing a statistical quantity. Unlike the Brill tagger where the rules are ordered sequentially, the POS and morphological tagging toolkit RDRPOSTagger stores rules in the form of a Ripple Down Rules tree.
Many machine learning methods have also been applied to the problem of POS tagging. Methods such as SVM, Maximum entropy classifier, Perceptron, and Nearest-neighbor have all been tried, and most can achieve accuracy above 95%.
A direct comparison of several methods is reported (with references) at [3]. This comparison uses the Penn tag set on some of the Penn Treebank data, so the results are directly comparable.
However, many significant taggers are not included (perhaps because of the labor involved in reconfiguring them for this particular dataset). Thus, it should not be assumed that the results reported there are the best that can be achieved with a given approach; nor even the best that have been achieved with a given approach.
A more recent development is using the structure regularization method for part-of-speech tagging, achieving 97.36% on the standard benchmark dataset.[4]
Issues
While there is broad agreement about basic categories, a number of edge cases make it difficult to settle on a single "correct" set of tags, even in a single language such as English. For example, it is hard to say whether "fire" is an adjective or a noun in
the big green fire truck
A second important example is the use/mention distinction, as in the following example, where "blue" could be replaced by a word from any POS (the Brown Corpus tag set appends the suffix "-NC" in such cases):
the word "blue" has 4 letters.
Words in a language other than that of the "main" text are commonly tagged as "foreign", usually in addition to a tag for the role the foreign word is actually playing in context.
There are also many cases where POS categories and "words" do not map one to one, for example:
 David's

 gonna

 don't

 vice versa

 first-cut

 cannot

 pre- and post-secondary

 look (a word) up
In the last example, "look" and "up" arguably function as a single verbal unit, despite the possibility of other words coming between them. Some tag sets (such as Penn) break hyphenated words, contractions, and possessives into separate tokens, thus avoiding some but far from all such problems.
It is unclear whether it is best to treat words such as "be", "have", and "do" as categories in their own right (as in the Brown Corpus), or as simply verbs (as in the LOB Corpus and the Penn Treebank). "be" has more forms than other English verbs, and occurs in quite different grammatical contexts, complicating the issue.
The most popular "tag set" for POS tagging for American English is probably the Penn tag set, developed in the Penn Treebank project. It is largely similar to the earlier Brown Corpus and LOB Corpus tag sets, though much smaller. In Europe, tag sets from the Eagles Guidelines see wide use, and include versions for multiple languages.
POS tagging work has been done in a variety of languages, and the set of POS tags used varies greatly with language. Tags usually are designed to include overt morphological distinctions, although this leads to inconsistencies such as case-marking for pronouns but not nouns in English, and much larger cross-language differences. The tag sets for heavily inflected languages such as Greek and Latin can be very large; tagging words in agglutinative languages such as Inuit may be virtually impossible. At the other extreme, Petrov, D. Das, and R. McDonald ("A Universal Part-of-Speech Tagset" http://arxiv.org/abs/1104.2086) have proposed a "universal" tag set, with 12 categories (for example, no subtypes of nouns, verbs, punctuation, etc.; no distinction of "to" as an infinitive marker vs. preposition, etc.). Whether a very small set of very broad tags or a much larger set of more precise ones is preferable, depends on the purpose at hand. Automatic tagging is easier on smaller tag-sets.
A different issue is that some cases are in fact ambiguous. Beatrice Santorini gives examples in "Part-of-speech Tagging Guidelines for the Penn Treebank Project," (3rd rev, June 1990 [4]), including the following (p. 32) case in which entertaining can be either an adjective or a verb, and there is no syntactic way to decide:
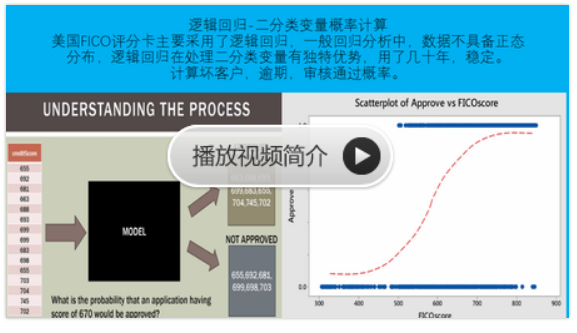
python风控评分卡建模和风控常识(博客主亲自录制视频教程)
词性标注 parts of speech tagging的更多相关文章
- 自然语言15.1_Part of Speech Tagging 词性标注
QQ:231469242 欢迎喜欢nltk朋友交流 https://en.wikipedia.org/wiki/Part-of-speech_tagging In corpus linguistics ...
- 自然语言15_Part of Speech Tagging with NLTK
https://www.pythonprogramming.net/part-of-speech-tagging-nltk-tutorial/?completed=/stemming-nltk-tut ...
- Part of Speech Tagging
Natural Language Processing with Python Charpter 6.1 suffix_fdist处代码稍微改动. import nltk from nltk.corp ...
- Java自然语言处理NLP工具包
1. Java自然语言处理 LingPipe LingPipe是一个自然语言处理的Java开源工具包.LingPipe目前已有很丰富的功能,包括主题分类(Top Classification).命名实 ...
- NLP 工具类库
NLPIR http://www.nlpir.org/ HanLP https://github.com/hankcs Apache OpenNLP https://opennlp.apache. ...
- python环境jieba分词的安装
我的python环境是Anaconda3安装的,由于项目需要用到分词,使用jieba分词库,在此总结一下安装方法. 安装说明======= 代码对 Python 2/3 均兼容 * 全自动安装:`ea ...
- jieba完整文档
jieba “结巴”中文分词:做最好的 Python 中文分词组件 "Jieba" (Chinese for "to stutter") Chinese tex ...
- 论文翻译——Deep contextualized word representations
Abstract We introduce a new type of deep contextualized word representation that models both (1) com ...
- 常用python机器学习库总结
开始学习Python,之后渐渐成为我学习工作中的第一辅助脚本语言,虽然开发语言是Java,但平时的很多文本数据处理任务都交给了Python.这些年来,接触和使用了很多Python工具包,特别是在文本处 ...
随机推荐
- 如何用linux命令查看nginx是否在正常运行
有时想知道nigix是否在正常运行,需要用linux命令查看nginx运行情况. 执行命令: ps -A | grep nginx 如果返回结果的话,说明有nginx在运行,服务已经启动. 如果 ...
- 【转】深入浅出Java三大框架SSH与MVC的设计模式
原文链接:http://www.cnblogs.com/itao/archive/2011/08/22/2148844.html 在许许多多的初学者和程序员,都在趋之若鹜地学习Web开发的宝典级框架: ...
- EditText 几种显示方式,固定行数,自适应行数
1.显示7行,超过7行自动向下补充行数 <EditText android:id="@+id/edt_content" android:layout_width=" ...
- 强连通 HDU 1269
n点m边 求是否能从任意a->b b->a 强连通分量等于1 #include<stdio.h> #include<algorithm> #include<s ...
- 51nod 1076强连通
Tarjan算法来解这题.无向图可以转化为有向图来解决. #include<map> #include<queue> #include<stack> #includ ...
- jquery检测浏览器版本
//检测当前浏览器 function browserType() { var brow = $.browser; //console.log(brow); var bInfo = "&quo ...
- 给<tr>标签添加边框
今天做网站时发现给<tr>添加border无效.起初还以为tr不支持这个属性,百度,原来只要给<table>添加一句代码就可以了,代码如下: table{border-coll ...
- XML和JSON的对比
简介: 客户端和服务器之间进行数据交互时,服务器往往会返回给客户端一定格式的数据.一般而言,服务器返回给客户端的数据为JSON或者XML文档格式的数据(文件下载除外).下面就针对于这两种数据格式分别介 ...
- java高新技术-代理
程序中代理的概念与作用 要为已存在的多个具有相同接口的目标类的各个方法增加一些系统功能,例如,异常处理.日志.计算方法的运行时间.事务管理.等等. 代理架构图: 如果采用工厂模式和配置文件的方式进行管 ...
- Android成长日记-Noification实现状态栏通知
Notification可以作为状态栏的通知,实现这个效果需要使用NotificationManager实现控制类,才能实现对这个效果的显示 下面是实现状态栏显示效果的通知: 1. 首先在Layout ...