
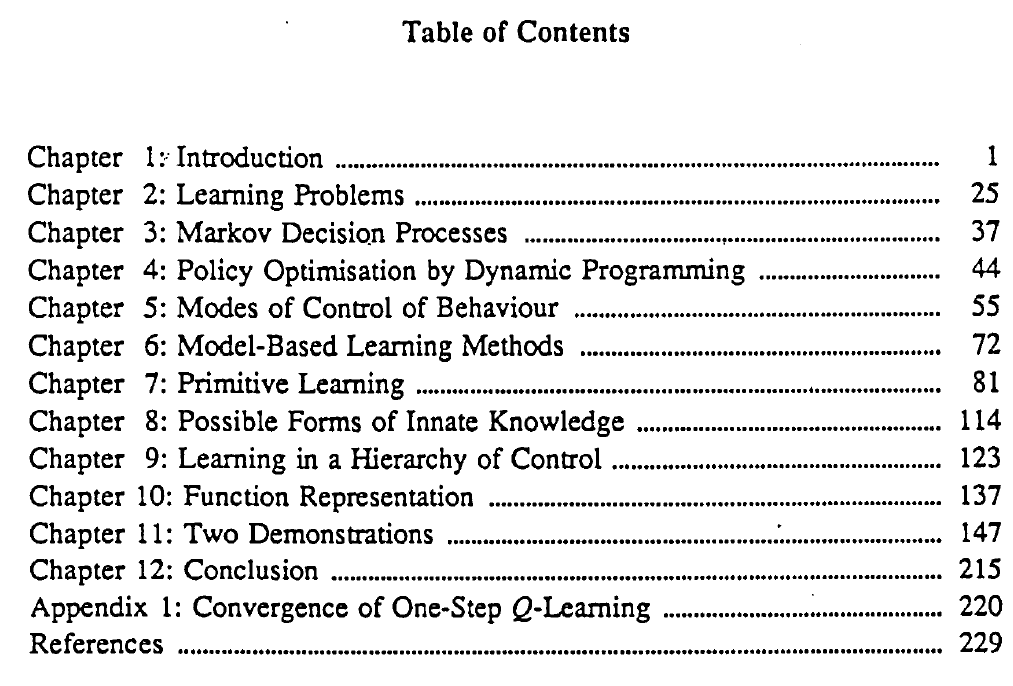
Learning from delayed reward (Q-Learning的提出) (Watkins博士毕业论文)(建立了现在的reinforcement Learning模型)
最近在在学习强化学习方面的东西, 对于现有的很多文章中关于强化学习的知识很是不理解,很多都是一个公式套一个公式,也没有什么太多的解释,感觉像是在看天书一般,经过了较长时间的挣扎最后决定从一些基础的东西开始入手,于是便有了这篇论文的发现。
Learning from Delayed Reward
该论文的页面为: http://www.cs.rhul.ac.uk/~chrisw/thesis.html
下载地址为: http://www.cs.rhul.ac.uk/~chrisw/new_thesis.pdf
论文页面对这篇文章的描述:
The thesis introduces the notion of reinforcement learning as learning to control a Markov Decision Process by incremental dynamic programming,
and describes a range of algorithms for doing this, including Q-learning, for which a sketch of a proof of convergence is given.
这篇文章虽然在现有的很多文献中并不是很被提及,但是它却具有很大的意义。这篇文章(准确的说是作者在1987年发表的一篇会议论文,集成在了这篇学位论文中了)建立了现在意义上的强化学习模型,它第一次将trial-and-error 和 dynammic programming 和 temporal diffecrence 结合在了一起,并提出了Q-Learning算法。在某种意义上它可谓是“万恶之源”。
=====================================================

============================================================
文章目录:
Learning from delayed reward (Q-Learning的提出) (Watkins博士毕业论文)(建立了现在的reinforcement Learning模型)的更多相关文章
- [DQN] What is Deep Reinforcement Learning
已经成为DL中专门的一派,高大上的样子 Intro: MIT 6.S191 Lecture 6: Deep Reinforcement Learning Course: CS 294: Deep Re ...
- 论文笔记之:Asynchronous Methods for Deep Reinforcement Learning
Asynchronous Methods for Deep Reinforcement Learning ICML 2016 深度强化学习最近被人发现貌似不太稳定,有人提出很多改善的方法,这些方法有很 ...
- Awesome Reinforcement Learning
Awesome Reinforcement Learning A curated list of resources dedicated to reinforcement learning. We h ...
- (转) Deep Reinforcement Learning: Pong from Pixels
Andrej Karpathy blog About Hacker's guide to Neural Networks Deep Reinforcement Learning: Pong from ...
- 论文笔记系列-Neural Architecture Search With Reinforcement Learning
摘要 神经网络在多个领域都取得了不错的成绩,但是神经网络的合理设计却是比较困难的.在本篇论文中,作者使用 递归网络去省城神经网络的模型描述,并且使用 增强学习训练RNN,以使得生成得到的模型在验证集上 ...
- (zhuan) Deep Reinforcement Learning Papers
Deep Reinforcement Learning Papers A list of recent papers regarding deep reinforcement learning. Th ...
- 【资料总结】| Deep Reinforcement Learning 深度强化学习
在机器学习中,我们经常会分类为有监督学习和无监督学习,但是尝尝会忽略一个重要的分支,强化学习.有监督学习和无监督学习非常好去区分,学习的目标,有无标签等都是区分标准.如果说监督学习的目标是预测,那么强 ...
- (zhuan) Paper Collection of Multi-Agent Reinforcement Learning (MARL)
this blog from: https://github.com/LantaoYu/MARL-Papers Paper Collection of Multi-Agent Reinforcemen ...
- Understanding dopamine and reinforcement learning: The dopamine reward prediction error hypothesis
郑重声明:原文参见标题,如有侵权,请联系作者,将会撤销发布! Abstract 在中脑多巴胺能神经元的研究中取得了许多最新进展.要了解这些进步以及它们之间的相互关系,需要对作为解释框架并指导正在进行的 ...
随机推荐
- C++创建虚拟机调用JAVA类
ZC: 简要摘抄: “ 1. Object类出创建JVM. 使用Java类之前必须要创建JVM环境.JDK由java.exe来完成.本文有Object类的静态方法BeginJVM来创建,用E ...
- 对当前JAVA流行框架的一些小感悟
这几年,蹦出了不少各种JAVA框架,像是spring boot.spring cloud 和spring mvc或者是mybatis等等. 不断有人感慨,技术更新的太快,自己学都学不过来了. 但是,这 ...
- 2018年全国多校算法寒假训练营练习比赛(第一场)E 恋与程序员
https://www.nowcoder.com/acm/contest/67/E 思路: dfs 代码: #include<bits/stdc++.h> using namespace ...
- Linux下安装Phantomjs
1. 安装linux系统的软件包 先来看一下官方网站的提示: Note: For this static build, the binary is self-contained. There is n ...
- Elections CodeForces - 1020C (贪心)
大意: 有n个选民, m个党派, 第i个选民初始投$p_i$一票, 可以花费$c_i$改变投票, 求最少花费使得第一个党派的票数严格最大 假设最终第一个党派得票数$x$, 枚举$x$, 则对于所有票数 ...
- Pollywog CodeForces - 917C (状压)
链接 大意: 一共n个格子, 初始$x$只蝌蚪在前$x$个格子, 每次最左侧的蝌蚪向前跳, 跳跃距离在范围[1,k], 并且每只蝌蚪跳跃都有一定花费, 有$q$个格子上有石头, 若有蝌蚪跳到某块石头上 ...
- Matlab scatter 如何显示不同颜色点状
有时候需要在matlab scatter绘图中显示不同颜色区分,如下图是人体血压高压.低压与年龄关系的散点图. 红色点表示高压 绿色点表示低压 用 matlab 如何实现呢? 1.创建一维矩阵x,y1 ...
- python-day49--前端 css-层叠样式表
1.css功能: 对html标签的渲染和布局 2.CSS 要掌握的两方面: 1.查找标签 选择器 2.操作标签 (对属性进行操作) 3.CSS 语法 CSS 规则由两个主要的部分构成:选择器,以及一 ...
- zzuli1985(dp/水dfs郑轻比赛)
再一次感受到dp的威力 1985: 即将到来的新生赛 Time Limit: 1 Sec Memory Limit: 128 MBSubmit: 112 Solved: 28 SubmitStat ...
- POJ-1753 Flip Game (BFS+状态压缩)
Description Flip game is played on a rectangular 4x4 field with two-sided pieces placed on each of i ...