
【速读】——Shangxuan Tian——【ICCV2017】WeText_Scene Text Detection under Weak Supervision
Shangxuan Tian——【ICCV2017】WeText_Scene Text Detection under Weak Supervision
目录
- 作者和相关链接
- 文章亮点
- 方法介绍
- 方法细节
- 实验结果
- 总结与收获
作者和相关链接
- 作者

文章亮点
- 用半监督和无监督来学习字符分类器,解决字符标注数据量少的问题
- 用regression的思路来学习字符分类器,而且是把proposal + text/non-text classification整合在一个网络中学习(这一点没有第一点亮)
方法介绍
- 检测流程
用SSD检测字符(文章的亮点在于如何训练这个SSD)
- 用TextFlow的图模型把字符连成单词输出
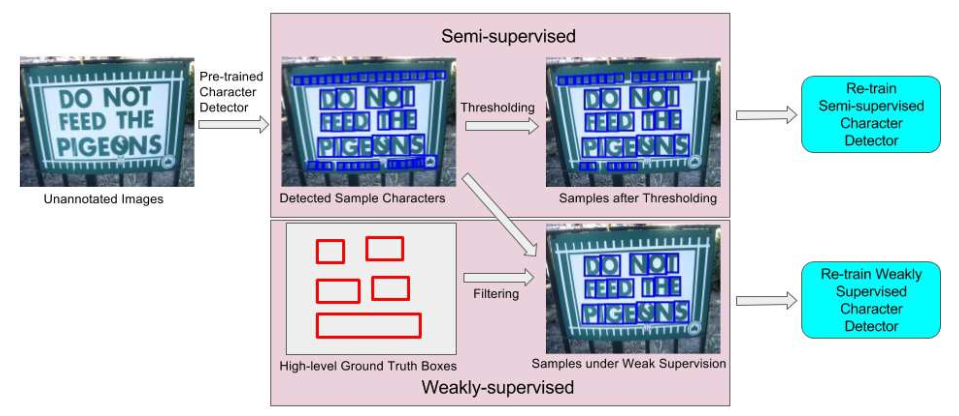
Figure 2: The framework of the proposed WeText system: A “light” supervised model is pre-trained using a small amount of annotated character image set. The light model is then applied to an unannotated dataset to search for more character samples which are combined with the small annotated dataset to train a semi-supervised model. Under certain weak annotations, better character samples can be searched to train a semi-supervised model
- 训练SSD的半监督方法
用一个小数据集(记为D)采用监督的方式训练一个light的base model(记为M)
用M跑一遍没有标注的大数据集(记为R),将其中分数大于阈值(0.5)的样本作为正样本(记为数据集P)
用数据集D+数据集P训练新的model(记为M’)
- 训练SSD的弱监督方法
用一个小数据集(记为D)采用监督的方式训练一个light的base model(记为M)
用M跑一遍有单词标注信息的大数据集(记为R’),将其中分数大于阈值(0.2)且与单词标注GT有重叠(水平和竖直IOU阈值0.8)的样本作为正样本(记为数据集P’)
用数据集D+数据集P’训练新的model(记为M’’)
方法细节
- 几种SSD模型效果对比
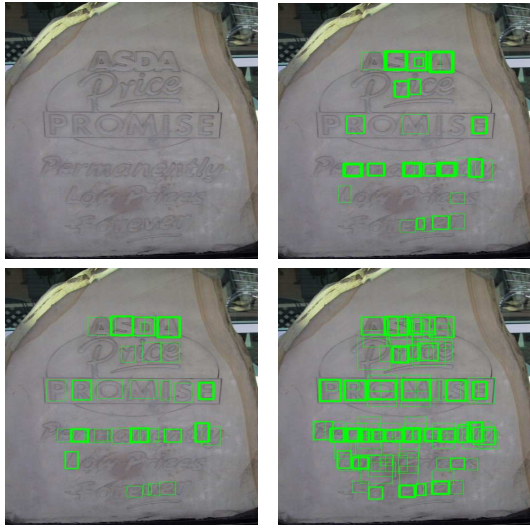
Figure 4: Comparison of different character detectors. Images in the top row from left to right are the input image and output of the baseline detector. Images in the bottom row from left to right are outputs of “COCO-Text Semi” and “COCO-Text Weakly” detectors, respectively. The thickness of the box boundary lines indicates the detection confidence
- Training
- Base model:ICDAR2013的字符集
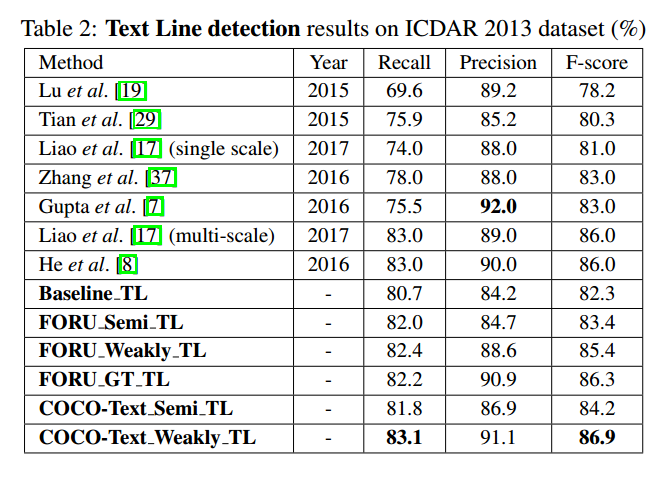
- FORU: FORU_Semi为半监督,FORU_Weakly为弱监督,FORU_GT为完全监督(FORU本身有字符集标注信息,COCO-Text上没有,故没有COCO-Text_GT)。FORU_GT的目的在于验证用半监督和弱监督的方法也可以达到几乎和完全监督的效果是一样的(FORU_GT算是算法的精度上限),证明其半监督和弱监督的有效性;
- COCO_Text: 由于COCO-Text的样本集比FORU大,所以实验证明了无监督数据越多,效果越好;
实验结果
- 速度说明
- Nvidia Titan X GPU
- ICDAR2013:190ms-SSD模型,130ms-text line model,总的320ms/每张图
- ICDAR13
- SVT

总结与收获
- 这篇文章最大亮点无疑是用弱监督来扩增训练数据的思想,非常有参考价值,所以虽然点少但是也中ICCV。但是文中没有太多训练细节,比如在新的数据库上是重新train还是在原base model上fine-tune的,以及SSD的anchor设置细节之类的。
- 不看亮点,单看检测方法,其缺点在于:第一,速度比较慢;第二,只能处理水平的,无法处理多方向的;第三,由于采用了character-based的pipeline,导致必须加上text flow里的图模型来合并文本线。这种思路不但需要两个分离的模型,速度降低,也会因为分步累计误差,且无法端到端训练。且第二点也是因为采用这种pipeline导致的,实际上要将character合并成多方向的text line也是可以的,但是不能用text flow里的,而是需要设计新的算法来替换(这个也蛮有难度的)。
【速读】——Shangxuan Tian——【ICCV2017】WeText_Scene Text Detection under Weak Supervision的更多相关文章
- 【论文速读】Fangfang Wang_CVPR2018_Geometry-Aware Scene Text Detection With Instance Transformation Network
Han Hu--[ICCV2017]WordSup_Exploiting Word Annotations for Character based Text Detection 作者和代码 caffe ...
- 【论文速读】Chuhui Xue_ECCV2018_Accurate Scene Text Detection through Border Semantics Awareness and Bootstrapping
Chuhui Xue_ECCV2018_Accurate Scene Text Detection through Border Semantics Awareness and Bootstrappi ...
- 【论文速读】Yuliang Liu_2017_Detecting Curve Text in the Wild_New Dataset and New Solution
Yuliang Liu_2017_Detecting Curve Text in the Wild_New Dataset and New Solution 作者和代码 caffe版代码 关键词 文字 ...
- 【论文速读】Pan He_ICCV2017_Single Shot Text Detector With Regional Attention
Pan He_ICCV2017_Single Shot Text Detector With Regional Attention 作者和代码 caffe代码 关键词 文字检测.多方向.SSD.$$x ...
- 论文速读(Chuhui Xue——【arxiv2019】MSR_Multi-Scale Shape Regression for Scene Text Detection)
Chuhui Xue--[arxiv2019]MSR_Multi-Scale Shape Regression for Scene Text Detection 论文 Chuhui Xue--[arx ...
- 【论文速读】XiangBai_CVPR2018_Rotation-Sensitive Regression for Oriented Scene Text Detection
XiangBai_CVPR2018_Rotation-Sensitive Regression for Oriented Scene Text Detection 作者和代码 caffe代码 关键词 ...
- 论文速读(Yongchao Xu——【2018】TextField_Learning A Deep Direction Field for Irregular Scene Text)
Yongchao Xu--[2018]TextField_Learning A Deep Direction Field for Irregular Scene Text Detection 论文 Y ...
- 【论文速读】Shitala Prasad_ECCV2018】Using Object Information for Spotting Text
Shitala Prasad_ECCV2018]Using Object Information for Spotting Text 作者和代码 关键词 文字检测.水平文本.FasterRCNN.xy ...
- 【论文速读】Sheng Zhang_AAAI2018_Feature Enhancement Network_A Refined Scene Text Detector
Sheng Zhang_AAAI2018_Feature Enhancement Network_A Refined Scene Text Detector 作者 关键词 文字检测.水平文字.Fast ...
随机推荐
- Numpy初步
1,获取矩阵行列数 Import numpyasnp #创建二维的naaray对象 a=np.array([[1,2,3,4,5],[6,7,8,9,10]]) print(a.shape) #返 ...
- helm-chart5,模板和访问文件
提供的一些声明和使用命名模板段的操作: define在模板中声明一个新的命名模板 template导入一个命名模板 block 声明了一种特殊的可填写模板区域 首先,模板名称是全局的.如果声明两个具有 ...
- centos7中安装pg数据库
# centos中安装的命令 # yum install postgresql-server.x86_64 # 安装之前可以通过以下命令价差是否已经安装过 rpm -qa | grep postgre ...
- SVN 提示clean up 进入死循环
SVN在使用update命令时,提示使用“clean up ”命令,在使用clean up命令时报错“Previous operation has not finished; run 'cleanup ...
- EMI优化
一般印刷电路板之间的高速信号线路无法通过FCC和VDE辐射测试. 优化方案有以下3种: 1.高频滤波 通常做法在每个逻辑驱动器上串联一个小阻抗,并经过一个旁路电容接地. 旁路电容接地需足够干净,如机箱 ...
- Linux各目录及每个目录的详细介绍(转载)
[常见目录说明] 目录 /bin 存放二进制可执行文件(ls,cat,mkdir等),常用命令一般都在这里. /etc 存放系统管理和配置文件 /home 存放所有用户文件的根目录,是用户主目录的基点 ...
- Jquery常用的方法总结
1.关于页面元素的引用通过jquery的$()引用元素包括通过id.class.元素名以及元素的层级关系及dom或者xpath条件等方法,且返回的对象为jquery对象(集合对象),不能直接调用dom ...
- 秒杀linux下系统调用fork()面试题(转)
https://blog.csdn.net/chdhust/article/details/10579001 https://www.cnblogs.com/clover-toeic/p/375443 ...
- DjangoRestFramework 学习之restful规范 APIview 解析器组件 Postman等
DjangoRestFramework学习一之restful规范.APIview.解析器组件.Postman等 本节目录 一 预备知识 二 restful规范 三 DRF的APIView和解析器组件 ...
- Robot Framework 1
about Robot, learnt from the following document, perfect document !!!! http://www.virtuousprogrammer ...