
pandas.DataFrame.where和mask 解读
1.前言背景
没怎么用过df.where 都是直接使用loc、apply等方法去解决。


可能是某些功能还没有超出loc和apply的适用范围。
2.进入df.where和df.mask
DataFrame.where(self, cond, other=nan, inplace=False, axis=None, level=None, errors='raise', try_cast=False)
note:Replace values in DataFrame with other where the cond is False.
我们还是要看一下官网对里面每一个参数的解释:
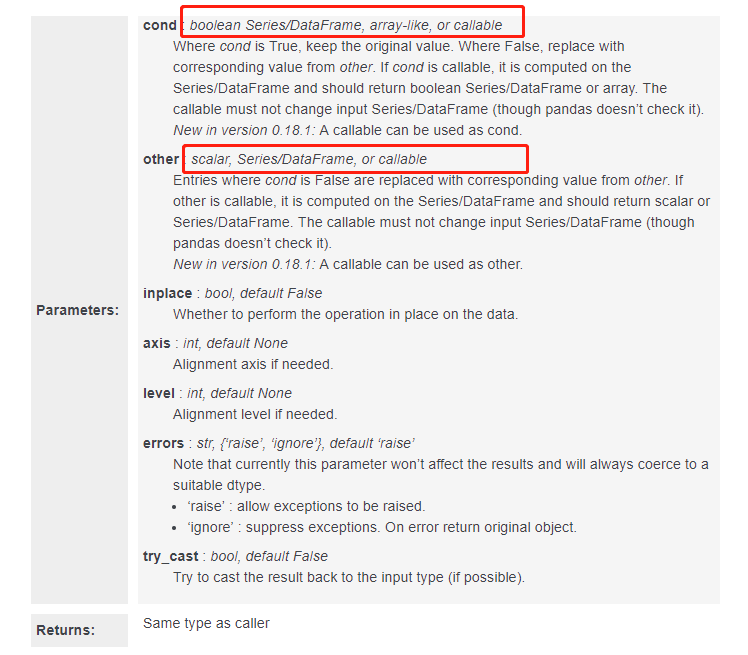
红色是特别注意的,往往无论是博客还是案例一般给不会穷举所有可能,只有把api的每一种可能理解了,才能无招胜有招。
大体意思:就是对一个DataFrame进行条件判断当他的条件不符合就选择other参数里面的数值。
其实它拥有一个相反的函数where<==>mask:where条件不符合进行替换,mask是条件符合进行替换。
DataFrame.mask(self, cond, other=nan, inplace=False, axis=None, level=None, errors='raise', try_cast=False)
note:Replace values in DataFrame with other where the cond is True.
我们还是要看一下官网对里面每一个参数的解释:
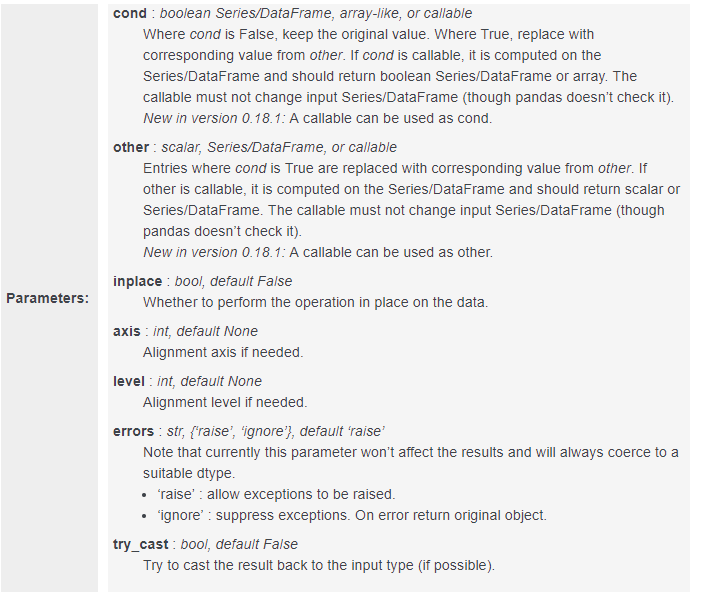
也可以看到两者参数并无差异。
3.与np.where的异同?

np.where(condition, [x, y]),这里三个参数,其中必写参数是condition(判断条件),后边的x和y是可选参数.那么这三个参数都有怎样的要求呢?
condition:array_like,bool ,当为True时,产生x,否则产生y
简单说,对第一个参数的要求是这样的,首先是数据类型的要求,类似于数组或者布尔值,当判断条件为真时返回x中的值,否则返回y中的值
x,y:array_like,可选,要从中选择的值。 x,y和condition需要可广播到某种形状
x和y是可选参数,并且对这两个参数的数据类型要求只有类似数组这一条,当条件判断为true或者false时从这两个类似数组的容器中取数.
4.实际案例
4.1mask和where 的区别,np.where(cond,df1,df2)
s = pd.Series(range(5))
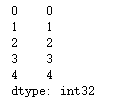
s.mask(s > 0)

s.where(s > 0)

ss = pd.Series(range(10,20,2))

import numpy as np

np.where(s>2,s,ss)

4.2探究cond : boolean Series/DataFrame, array-like, or callable和other : scalar, Series/DataFrame, or callable
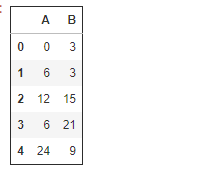
下面我在cond使用callable类型,在other参数中使用callable参数
df = pd.DataFrame(np.arange(10).reshape(-1, 2), columns=['A', 'B'])

df
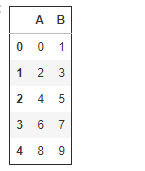
def cond1(x):

     return x%3==0

def mult3(x):

    return x*3

df.where(cond1, mult3)
pandas.DataFrame.where和mask 解读的更多相关文章
- pandas.DataFrame学习系列1——定义及属性
定义: DataFrame是二维的.大小可变的.成分混合的.具有标签化坐标轴(行和列)的表数据结构.基于行和列标签进行计算.可以被看作是为序列对象(Series)提供的类似字典的一个容器,是panda ...
- pandas.DataFrame的pivot()和unstack()实现行转列
示例: 有如下表需要进行行转列: 代码如下: # -*- coding:utf-8 -*- import pandas as pd import MySQLdb from warnings impor ...
- pandas DataFrame apply()函数(1)
之前已经写过pandas DataFrame applymap()函数 还有pandas数组(pandas Series)-(5)apply方法自定义函数 pandas DataFrame 的 app ...
- pandas DataFrame apply()函数(2)
上一篇pandas DataFrame apply()函数(1)说了如何通过apply函数对DataFrame进行转换,得到一个新的DataFrame. 这篇介绍DataFrame apply()函数 ...
- 把pandas dataframe转为list方法
把pandas dataframe转为list方法 先用numpy的 array() 转为ndarray类型,再用tolist()函数转为list
- pandas DataFrame.shift()函数
pandas DataFrame.shift()函数可以把数据移动指定的位数 period参数指定移动的步幅,可以为正为负.axis指定移动的轴,1为行,0为列. eg: 有这样一个DataFrame ...
- pandas DataFrame applymap()函数
pandas DataFrame的 applymap() 函数可以对DataFrame里的每个值进行处理,然后返回一个新的DataFrame: import pandas as pd df = pd. ...
- pandas DataFrame(3)-轴
和numpy数组(5)-二维数组的轴一样,pandas DataFrame也有轴的概念,决定了方法是对行应用还是对列应用: 以下面这个数据为例说明: 这个数据是5个车站10天内的客流数据: rider ...
- pandas DataFrame(4)-向量化运算
pandas DataFrame进行向量化运算时,是根据行和列的索引值进行计算的,而不是行和列的位置: 1. 行和列索引一致: import pandas as pd df1 = pd.DataFra ...
随机推荐
- mysql的binlog安全删除的一种方法
指定过期天数(expire_logs_days) ---适用于单机版mysql! 该参数为全局可动态调整参数,默认值为0,即关闭,取值范围0-99. 1.3.1 参数的查看: mysql> ...
- 新拉的项目在idea中启动时报如下错误:org.apache.catalina.core.ContainerBase.addChildInternal ContainerBase.addChild: start:
今天真的是很苦恼,之前启动项目没有任何问题,今天突然启动时给我报了如下一个错误. 详细报错信息: org.apache.catalina.core.ContainerBase.addChildInte ...
- 有关带scala版本的eclipse4.7的下载
有关带scala版本的eclipse4.7的下载, 你可以直接去: http://scala-ide.org/download/sdk.html 下载下来后是:scala-SDK-4.7.0-vf ...
- MS SQL 2012表分区
最近开发一个手机用户统计平台,因为涉及到数据庞大,不得不以一周为单位对统计报表进行分区,所以记录一下,方便以后查看 第一步创建文件分组 对于文件分组共创建了14个,从 xy_group_2014102 ...
- php curl post请求
/** * CreateBy Song * @param String $url url地址 * @param Array $post url参数 * @return Array */ functio ...
- 怎样使用yum安装nginx
yum install -y nginx 以上.
- 怎样设置HTTP请求头Header
使用: xhr.setRequestHeader(); xhr.setRequestHeader('Content-Type', 'application/json'); xhr.setRequest ...
- Python实现字符的冒泡排序——说实话,两个数兑换的方法震惊了我,一天比一天感受到了Python的强大
import random M= lettList=[] for i in range(M): lettList.append(chr(random.randrange(,))) for lett i ...
- tinymce富文本是在modal框中弹出显示的问题
记录一下,在用tinymce富文本的时候,由于是用在modal 上的,始终无法获取焦点,后来才发现问题出在tinymce在modal前创建了,所以导致这个问题,解决方案就是用 v-if="v ...
- OPENGL 显示BMP图片+旋转
VS2010/Windows 7/ 1. 需包含头文件 stdio.h, glaux.h, glut.h.需要对应的lib,并添加包含路径 2. 窗口显示用glut库的函数 3. bmp图片从本地读取 ...