
Python对elasticsearch的CRUD
一.官网提供的Elasticsearch的Python接口包
1.github地址:https://github.com/elastic/elasticsearch-dsl-py
2.安装:pip install elasticsearch-dsl
3.有很多api,使用可参考github中的文档
二.定义写入es的Pipeline:
1.生成索引,type及映射:
有可能会报IllegalOperation异常,访问本地9200端口查看es版本,然后将python中的elasticsearch和elasticsearch-dsl改成相近版本即可
# _*_ encoding:utf-8 _*_

__author__ = 'LYQ'

__date__ = '2018/10/29 11:02'

#新版本把DocType改为Docment

from datetime import datetime

from elasticsearch_dsl import DocType,Date, Nested, Boolean, \

    analyzer, Completion, Keyword, Text, Integer

from elasticsearch_dsl.connections import connections

# es连接到本地,可以连接到多台服务器

connections.create_connection(hosts=["localhost"])

class ArticleType(DocType):

    "定义es映射"

    # 以ik解析

    title = Text(analyzer="ik_max_word")

    create_date = Date()

    # 不分析

    url = Keyword()

    url_object_id = Keyword()

    front_image_url = Keyword()

    front_image_path = Keyword()

    praise_nums = Integer()

    fav_nums = Integer()

    comment_nums = Integer()

    tags = Text(analyzer="ik_max_word")

    content = Text(analyzer="ik_max_word")

    class Meta:

        #定义索引和type

        index = "jobbole"

        doc_type = "artitle"

if __name__ == "__main__":

#调用init()方法便能生成相应所应和映射

    ArticleType.init()
2.创建相应item:
#导入定义的es映射

from models.es import ArticleType

from w3lib.html import remove_tags

class ElasticsearchPipeline(object):

    """

    数据写入elasticsearch,定义pipeline,记得配置进setting

    """

class ElasticsearchPipeline(object):

    """

    数据写入elasticsearch

    """

class ElasticsearchPipeline(object):

    """

    数据写入elasticsearch

    """

    def process_item(self, item, spider):

        #将定义的elasticsearch映射实列化

        articletype=ArticleType()

        articletype.title= item["title"]

        articletype.create_date = item["create_date"]

        articletype.url = item["url"]

        articletype.front_image_url = item["front_image_url"]

        if "front_image_path" in item:

            articletype.front_image_path = item["front_image_path"]

        articletype.praise_nums = item["praise_nums"]

        articletype.fav_nums = item["fav_nums"]

        articletype.comment_nums = item["comment_nums"]

        articletype.tags = item["tags"]

        articletype.content = remove_tags(item["content"])

        articletype.meta.id = item["url_object_id"]

        articletype.save()

        return item
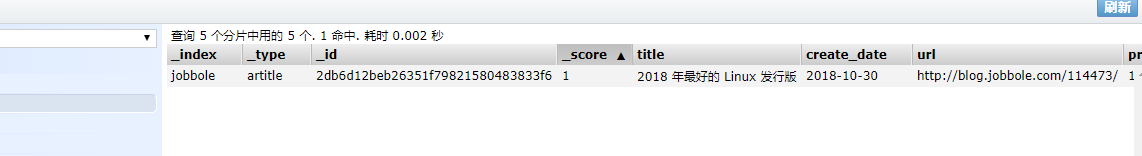
查看9100端口,数据插入成功
class JobboleArticleSpider(scrapy.Item):

    ......

    def save_to_es(self):

          "在item中分别定义存入es,方便不同的字段的保存"

        articletype = ArticleType()

        articletype.title = self["title"]

        articletype.create_date = self["create_date"]

        articletype.url = self["url"]

        articletype.front_image_url = self["front_image_url"]

        if "front_image_path" in self:

            articletype.front_image_path = self["front_image_path"]

        articletype.praise_nums = self["praise_nums"]

        articletype.fav_nums = self["fav_nums"]

        articletype.comment_nums = self["comment_nums"]

        articletype.tags = self["tags"]

        articletype.content = remove_tags(self["content"])

        articletype.meta.id = self["url_object_id"]

        articletype.save()
class ElasticsearchPipeline(object):

    """

    数据写入elasticsearch

    """

    def process_item(self, item, spider):

        # 将定义的elasticsearch映射实列化

       #调用item中的方法

        item.save_to_es()

        return item
三.搜索建议:
实质调用anylyer接口如下:
GET _analyze

{

  "analyzer": "ik_max_word",

  "text"    : "Python网络基础学习"

}
es文件中:
from elasticsearch_dsl.analysis import CustomAnalyzer as _CustomAnalyzer

esc=connections.create_connection(ArticleType._doc_type.using)

class Customanalyzer(_CustomAnalyzer):

    """自定义analyser"""

    def get_analysis_definition(self):

        # 重写该函数返回空字典

        return {}

ik_analyser = Customanalyzer("ik_max_word", filter=["lowercase"])

class ArticleType(DocType):

    "定义es映射"

    suggest = Completion(analyzer=ik_analyser)

   ......

生成该字段的信息
2.item文件:
......

from models.es import esc

def get_suggest(index, info_tuple):

    """根据字符串和权重生成搜索建议数组"""

    used_words = set()

    suggests = []

    for text, weight in info_tuple:

        if text:

            # 调用es得analyer接口分析字符串

            # 返回解析后得分词数据

            words = esc.indices.analyze(index=index, analyer="ik_max_word", params={"filter": ["lowercase"]}, body=text)

            # 生成式过滤掉长度为1的

            anylyzed_words = set([r["token"] for r in words if len(r) > 1])

            # 去重

            new_words = anylyzed_words - used_words

        else:

            new_words = set()

        if new_words:

            suggests.append({"input": list(new_words), "weight": weight})
  return suggests

class JobboleArticleSpider(scrapy.Item):

   ......

    def save_to_es(self):

        articletype = ArticleType()

        .......# 生成搜索建议字段,以及字符串和权重

        articletype.suggest = get_suggest(ArticleType._doc_type.index,((articletype.title,1),(articletype.tags,7)) )

        articletype.save()
Python对elasticsearch的CRUD的更多相关文章
- python实现elasticsearch操作-CRUD API
python操作elasticsearch常用API 目录 目录 python操作elasticsearch常用API1.基础2.常见增删改操作创建更新删除3.查询操作查询拓展类实现es的CRUD操作 ...
- ElasticSearch第二步-CRUD之Sense
ElasticSearch系列学习 ElasticSearch第一步-环境配置 ElasticSearch第二步-CRUD之Sense ElasticSearch第三步-中文分词 ElasticSea ...
- Python 操作 ElasticSearch
Python 操作 ElasticSearch 学习了:https://www.cnblogs.com/shaosks/p/7592229.html 官网:https://elasticsearch- ...
- Python 和 Elasticsearch 构建简易搜索
Python 和 Elasticsearch 构建简易搜索 作者:白宁超 2019年5月24日17:22:41 导读:件开发最大的麻烦事之一就是环境配置,操作系统设置,各种库和组件的安装.只有它们都正 ...
- Python操作ElasticSearch
Python批量向ElasticSearch插入数据 Python 2的多进程不能序列化类方法, 所以改为函数的形式. 直接上代码: #!/usr/bin/python # -*- coding:ut ...
- 笔记13:Python 和 Elasticsearch 构建简易搜索
Python 和 Elasticsearch 构建简易搜索 1 ES基本介绍 概念介绍 Elasticsearch是一个基于Lucene库的搜索引擎.它提供了一个分布式.支持多租户的全文搜索引擎,它可 ...
- Python中elasticsearch插入和更新数据的实现方法
Python中elasticsearch插入和更新数据的实现方法 这篇文章主要介绍了Python中elasticsearch插入和更新数据的实现方法,需要的朋友可以参考下 首先,我的索引结构是酱紫的. ...
- python操作Elasticsearch (一、例子)
E lasticsearch是一款分布式搜索引擎,支持在大数据环境中进行实时数据分析.它基于Apache Lucene文本搜索引擎,内部功能通过ReST API暴露给外部.除了通过HTTP直接访问El ...
- Elasticsearch的CRUD:REST与Java API
CRUD(Create, Retrieve, Update, Delete)是数据库系统的四种基本操作,分别表示创建.查询.更改.删除,俗称"增删改查".Elasticsearch ...
随机推荐
- day04 if判断、while条件循环、for迭代器循环部分使用举例
一:if判断 1.成绩>=90,那么:优秀 如果成绩>=80且<90,那么:良好 如果成绩>=70且<80,那么:普通 其 ...
- BuildTools Overview
SCons Pros: Based on a full-fledged programming language, Python. This means you can make the build ...
- 2018-2019-2 20175310 实验二《Java面向对象程序设计》实验报告
2018-2019-2 20175310 实验二<Java面向对象程序设计>实验报告 一.实验步骤及内容 (一).面向对象程序设计-1 参考 http://www.cnblogs.com/ ...
- 【LOJ 2144】「SHOI2017」摧毁「树状图」
LOJ 2144 84pts 首先\(op2\)很简单.直接并查集一搞就好了(话说我现在什么东西都要写个并查集有点...) 然后\(op0\)我不会,就直接\(O(n^2)\)枚举一下\(P\)这个人 ...
- 动手做webserver的核心之http解析
简介 webserver往小里说核心功能就是socket管理.url处理.http协议处理.业务dll管理等:下面简介绍一下http协议:超文本传输协议(HTTP)是一种通信协议,当时就是为web传输 ...
- UI 前端参考
:http://amazeui.org/ :http://www.dcloud.io/index.html :https://weui.io/ :http://m.sui.taobao.org/get ...
- Angular刷新浏览器 404 问题
最近在用angular写一个后台的项目,遇到一个小问题. 进入某个路由页面之后,手动触发浏览器的刷新,然后就404了... 翻看Angular的文档,发现Google早已经给我们想到了这个问题的处理方 ...
- BOM基础 计时器 定时器 DOM 基础
-------------------------------------------滴水穿石,我心永恒. day48 CSSJS 1 ECMA script 2 BOM browser object ...
- 关于getHibernateTemplate().get()方法
返回的对象值唯一,方法带有两个参数 第一个是意图查询实体的Class 如User.Class ;第二个参数是该实体在数据库中对应的主键值,而且参数的类型要和映射文件相对应. 如 Role role ...
- UnderWater+SDN论文之五
Underwater Sensor Networks with Mobile Agents: Experience from the Field Source: LNICST 2013 论文是来自两个 ...