
Jump Flood Algorithms for Centroidal Voronoi Tessellation
Brief
Implemented both CPU and GPU version, you could consider this as the basic playground to implement the more advanced feature such as support arbitrary shape in 2D space, or by radix-sort to restore the analytic shape of each Voronoi region etc. Another interesting application of JFA is the problem of 2D/3D level set reinitialization.
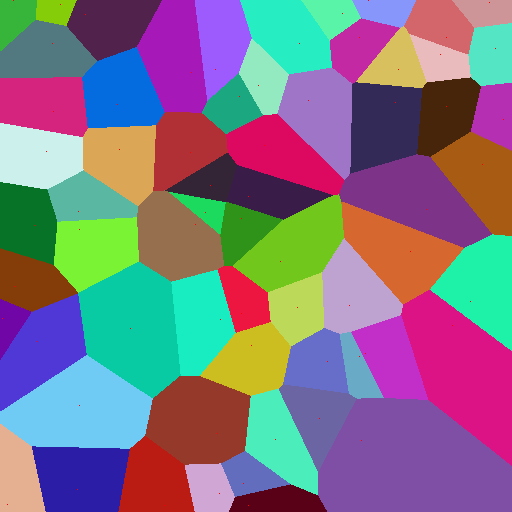
n = 16
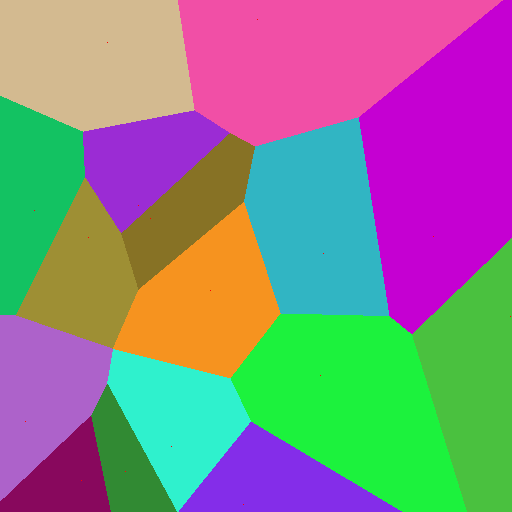
n = 64
CPU
/**

 * Copyright (c) 2014, Bo Zhou<Bo.Schwarzstein@gmail.com> and J CUBE Inc. Tokyo, Japan

 * All rights reserved.

 * Redistribution and use in source and binary forms, with or without

 * modification, are permitted provided that the following conditions are met:

 * 1. Redistributions of source code must retain the above copyright

 *    notice, this list of conditions and the following disclaimer.

 * 2. Redistributions in binary form must reproduce the above copyright

 *    notice, this list of conditions and the following disclaimer in the

 *    documentation and/or other materials provided with the distribution.

 * 3. All advertising materials mentioning features or use of this software

 *    must display the following acknowledgement:

 *    This product includes software developed by the <organization>.

 * 4. Neither the name of the <organization> nor the

 *    names of its contributors may be used to endorse or promote products

 *    derived from this software without specific prior written permission.

 *

 * THIS SOFTWARE IS PROVIDED BY COPYRIGHT HOLDER AND ANY

 * EXPRESS OR IMPLIED WARRANTIES, INCLUDING, BUT NOT LIMITED TO, THE IMPLIED

 * WARRANTIES OF MERCHANTABILITY AND FITNESS FOR A PARTICULAR PURPOSE ARE

 * DISCLAIMED. IN NO EVENT SHALL COPYRIGHT HOLDER BE LIABLE FOR ANY

 * DIRECT, INDIRECT, INCIDENTAL, SPECIAL, EXEMPLARY, OR CONSEQUENTIAL DAMAGES

 * (INCLUDING, BUT NOT LIMITED TO, PROCUREMENT OF SUBSTITUTE GOODS OR SERVICES;

 * LOSS OF USE, DATA, OR PROFITS; OR BUSINESS INTERRUPTION) HOWEVER CAUSED AND

 * ON ANY THEORY OF LIABILITY, WHETHER IN CONTRACT, STRICT LIABILITY, OR TORT

 * (INCLUDING NEGLIGENCE OR OTHERWISE) ARISING IN ANY WAY OUT OF THE USE OF THIS

 * SOFTWARE, EVEN IF ADVISED OF THE POSSIBILITY OF SUCH DAMAGE.

 */

#include <cmath>

#include <cstdlib>

#include <ctime>

#include <ImathColor.h>

#include <ImathVec.h>

#include <iostream>

#include <iterator>

#include <vector>

int main( int Argc , char ** Argv )

{

    -- Argc , ++ Argv ;

    if ( Argc !=  )

    {

        return EXIT_FAILURE ;

    }

    //

    int NumSites = atoi( Argv[] ) ;

    int Size     = atoi( Argv[] ) ;

    // 1) Generate the 2D sites and the fill color.

    //

    std::vector< Imath::V2f > SiteVec ;

    std::vector< int > SeedVecA( Size * Size , -  ) ;

    std::vector< Imath::C3c > RandomColorVec ;

    if ( NumSites >  )

    {

        srand( time(NULL) ) ;

        for ( int i =  ; i < NumSites ; ++ i )

        {

            float X = static_cast< float >( rand() ) / RAND_MAX * Size ;

            float Y = static_cast< float >( rand() ) / RAND_MAX * Size ;

            Imath::V2i Cell( static_cast< int >( floorf( X ) ) ,

                             static_cast< int >( floorf( Y ) ) ) ;

            SiteVec.push_back( Imath::V2f( Cell.x + 0.5f , Cell.y + 0.5f ) ) ;

            SeedVecA[Cell.x + Cell.y * Size] = i ;

            Imath::C3c C( static_cast< unsigned char >( static_cast< float >( rand() ) / RAND_MAX * 255.0f ) ,

                          static_cast< unsigned char >( static_cast< float >( rand() ) / RAND_MAX * 255.0f ) ,

                          static_cast< unsigned char >( static_cast< float >( rand() ) / RAND_MAX * 255.0f ) ) ;

            RandomColorVec.push_back( C ) ;

        }

    }

    else

    {

        NumSites =  ;

        SiteVec.push_back( Imath::V2f( 0.5f , 0.5f ) ) ;

        SeedVecA[] =  ;

        RandomColorVec.push_back( Imath::C3c(  ,  ,  ) ) ;

    }

    std::vector< int > SeedVecB( SeedVecA ) ;

    //

    const int SizeLowTwo = static_cast< int >( ceilf( logf( static_cast< float >( Size ) ) ) ) ;

    //

    static const Imath::V2i OffsetArray[] = { Imath::V2i( -  , -  ) ,

                                               Imath::V2i(    , -  ) ,

                                               Imath::V2i(    , -  ) ,

                                               Imath::V2i( -  ,    ) ,

                                               Imath::V2i(    ,    ) ,

                                               Imath::V2i( -  ,    ) ,

                                               Imath::V2i(    ,    ) ,

                                               Imath::V2i(    ,    ) } ;

    int * Ping = & SeedVecA[] ;

    int * Pong = & SeedVecB[] ;

    for ( int k = Size /  ; k >  ; k = k >>  )

    {

        fprintf( stdout , "k = %d\n" , k ) ;

        for ( int y =  ; y < Size ; ++ y )

        {

            for ( int x =  ; x < Size ; ++ x )

            {

                const int CellIdx = x + y * Size ;

                const int Seed = Ping[CellIdx] ;

                if ( Seed > -  )

                {

                    Imath::V2i Cell( x , y ) ;

                    for ( int i =  ; i <  ; ++ i )

                    {

                        const Imath::V2i & FillCell = Cell + k * OffsetArray[i] ;

                        if ( FillCell.x >=  && FillCell.x < Size && FillCell.y >=  && FillCell.y < Size )

                        {

                            const int FillCellIdx = FillCell.x + FillCell.y * Size ;

                            const int FillSeed = Pong[FillCellIdx] ;

                            if ( FillSeed <  )

                            {

                                Pong[FillCellIdx] = Seed ;

                            }

                            else

                            {

                                const Imath::V2f & FillP = Imath::V2f( FillCell.x + 0.5f , FillCell.y + 0.5f ) ;

                                if ( ( FillP - SiteVec[Seed] ).length() < ( FillP - SiteVec[FillSeed] ).length() )

                                {

                                    Pong[FillCellIdx] = Seed ;

                                }

                            }

                        }

                    }

                }

            }

        }

        std::copy( Pong , Pong + SeedVecA.size() , Ping ) ;

        std::swap( Ping , Pong ) ;

    }

    //

    FILE * Output = fopen( Argv[] , "wb" ) ;

    fprintf( Output , "P6\n%d %d\n255\n" , Size , Size ) ;

    std::vector< Imath::C3c > Pixels( Size * Size , Imath::C3c(  ) ) ;

    for ( int y =  ; y < Size ; ++ y )

    {

        for ( int x =  ; x < Size ; ++ x )

        {

            const int Seed = Pong[x + y * Size] ;

            if ( Seed != -  )

            {

                Pixels[x + y * Size] = RandomColorVec[Seed] ;

            }

        }

    }

    for( std::vector< Imath::V2f >::const_iterator itr = SiteVec.begin() ; itr != SiteVec.end() ; ++ itr )

    {

        const int x = static_cast< int >( floorf( itr->x ) ) ;

        const int y = static_cast< int >( floorf( itr->y ) ) ;

        Pixels[x + y * Size] = Imath::C3c(  ,  ,  ) ;

    }

    fwrite( & Pixels[].x ,  , Pixels.size() , Output ) ;

    fclose( Output ) ;

    return EXIT_SUCCESS ;

}
JFA CPU
GPU
/**

 * Copyright (c) 2014, Bo Zhou<Bo.Schwarzstein@gmail.com> and J CUBE Inc. Tokyo, Japan

 * All rights reserved.

 * Redistribution and use in source and binary forms, with or without

 * modification, are permitted provided that the following conditions are met:

 * 1. Redistributions of source code must retain the above copyright

 *    notice, this list of conditions and the following disclaimer.

 * 2. Redistributions in binary form must reproduce the above copyright

 *    notice, this list of conditions and the following disclaimer in the

 *    documentation and/or other materials provided with the distribution.

 * 3. All advertising materials mentioning features or use of this software

 *    must display the following acknowledgement:

 *    This product includes software developed by the <organization>.

 * 4. Neither the name of the <organization> nor the

 *    names of its contributors may be used to endorse or promote products

 *    derived from this software without specific prior written permission.

 *

 * THIS SOFTWARE IS PROVIDED BY COPYRIGHT HOLDER AND ANY

 * EXPRESS OR IMPLIED WARRANTIES, INCLUDING, BUT NOT LIMITED TO, THE IMPLIED

 * WARRANTIES OF MERCHANTABILITY AND FITNESS FOR A PARTICULAR PURPOSE ARE

 * DISCLAIMED. IN NO EVENT SHALL COPYRIGHT HOLDER BE LIABLE FOR ANY

 * DIRECT, INDIRECT, INCIDENTAL, SPECIAL, EXEMPLARY, OR CONSEQUENTIAL DAMAGES

 * (INCLUDING, BUT NOT LIMITED TO, PROCUREMENT OF SUBSTITUTE GOODS OR SERVICES;

 * LOSS OF USE, DATA, OR PROFITS; OR BUSINESS INTERRUPTION) HOWEVER CAUSED AND

 * ON ANY THEORY OF LIABILITY, WHETHER IN CONTRACT, STRICT LIABILITY, OR TORT

 * (INCLUDING NEGLIGENCE OR OTHERWISE) ARISING IN ANY WAY OUT OF THE USE OF THIS

 * SOFTWARE, EVEN IF ADVISED OF THE POSSIBILITY OF SUCH DAMAGE.

 */

#include <cmath>

#include <cstdio>

#include <cstdlib>

#include <ctime>

#include <cuda_runtime.h>

#include <cuda_runtime_api.h>

#include <iostream>

#include <iterator>

#include <vector>

__global__ void Kernel( int SizeX , int SizeY , const float2 * SiteArray , const int * Ping , int * Pong , int k , int * Mutex )

{

    //

    const int CellX = threadIdx.x + blockIdx.x * blockDim.x ;

    const int CellY = threadIdx.y + blockIdx.y * blockDim.y ;

    const int CellIdx = CellX + CellY * SizeX ;

    const int Seed = Ping[CellIdx] ;

    if ( Seed <  )

    {

        return ;

    }

    //

    const int2 OffsetArray[] = { { -  , -  } ,

                                  {    , -  } ,

                                  {    , -  } ,

                                  { -  ,    } ,

                                  {    ,    } ,

                                  { -  ,    } ,

                                  {    ,    } ,

                                  {    ,    } } ;

    for ( int i =  ; i <  ; ++ i )

    {

        const int FillCellX = CellX + k * OffsetArray[i].x ;

        const int FillCellY = CellY + k * OffsetArray[i].y ;

        if ( FillCellX >=  && FillCellX < SizeX && FillCellY >=  && FillCellY < SizeY )

        {

            //

            const int FillCellIdx = FillCellX + FillCellY * SizeX ;

            // Lock

            //

            while ( atomicCAS( Mutex , -  , FillCellIdx ) == FillCellIdx )

            {

            }

            const int FillSeed = Pong[FillCellIdx] ;

            if ( FillSeed <  )

            {

                Pong[FillCellIdx] = Seed ;

            }

            else

            {

                float2 P = make_float2( FillCellX + 0.5f , FillCellY + 0.5f ) ;

                float2 A = SiteArray[Seed] ;

                float2 PA = make_float2( A.x - P.x , A.y - P.y ) ;

                float PALength = PA.x * PA.x + PA.y * PA.y ;

                const float2 B = SiteArray[FillSeed] ;

                float2 PB = make_float2( B.x - P.x , B.y - P.y ) ;

                float PBLength = PB.x * PB.x + PB.y * PB.y ;

                if ( PALength < PBLength )

                {

                    Pong[FillCellIdx] = Seed ;

                }

            }

            // Release

            //

            atomicExch( Mutex , -  ) ;

        }

    }

}

int main( int Argc , char * Argv[] )

{

    -- Argc , ++ Argv ;

    if ( Argc !=  )

    {

        return EXIT_FAILURE ;

    }

    //

    int NumSites = atoi( Argv[] ) ;

    int Size     = atoi( Argv[] ) ;

    //

    int NumCudaDevice =  ;

    cudaGetDeviceCount( & NumCudaDevice ) ;

    if ( ! NumCudaDevice )

    {

        return EXIT_FAILURE ;

    }

    //

    //

    std::vector< float2 > SiteVec ;

    std::vector< int >    SeedVec( Size * Size , -  ) ;

    std::vector< uchar3 > RandomColorVec ;

    for ( int i =  ; i < NumSites ; ++ i )

    {

        float X = static_cast< float >( rand() ) / RAND_MAX * Size ;

        float Y = static_cast< float >( rand() ) / RAND_MAX * Size ;

        int CellX = static_cast< int >( floorf( X ) ) ;

        int CellY = static_cast< int >( floorf( Y ) ) ;

        SiteVec.push_back( make_float2( CellX + 0.5f , CellY + 0.5f ) ) ;

        SeedVec[CellX + CellY * Size] = i ;

        RandomColorVec.push_back( make_uchar3( static_cast< unsigned char >( static_cast< float >( rand() ) / RAND_MAX * 255.0f ) ,

                                               static_cast< unsigned char >( static_cast< float >( rand() ) / RAND_MAX * 255.0f ) ,

                                               static_cast< unsigned char >( static_cast< float >( rand() ) / RAND_MAX * 255.0f ) ) ) ;

    }

    //

    size_t SiteSize = NumSites * sizeof( float2 ) ;

    float2 * SiteArray = NULL ;

    cudaMalloc( & SiteArray , SiteSize ) ;

    cudaMemcpy( SiteArray , & SiteVec[] , SiteSize , cudaMemcpyHostToDevice ) ;

    //

    size_t BufferSize = Size * Size * sizeof( int ) ;

    int * Ping = NULL , * Pong = NULL ;

    cudaMalloc( & Ping , BufferSize ) , cudaMemcpy( Ping , & SeedVec[] , BufferSize , cudaMemcpyHostToDevice ) ;

    cudaMalloc( & Pong , BufferSize ) , cudaMemcpy( Pong , Ping , BufferSize , cudaMemcpyDeviceToDevice ) ;

    //

    int * Mutex = NULL ;

    cudaMalloc( & Mutex , sizeof( int ) ) , cudaMemset( Mutex , -  , sizeof( int ) ) ;

    //

    //

    cudaDeviceProp CudaDeviceProperty ;

    cudaGetDeviceProperties( & CudaDeviceProperty ,  ) ;

    dim3 BlockDim( CudaDeviceProperty.warpSize , CudaDeviceProperty.warpSize ) ;

    dim3 GridDim( ( Size + BlockDim.x -  ) / BlockDim.x ,

                  ( Size + BlockDim.y -  ) / BlockDim.y ) ;

    for ( int k = Size /  ; k >  ; k = k >>  )

    {

        Kernel<<< GridDim , BlockDim >>>( Size , Size , SiteArray , Ping , Pong , k , Mutex ) ;

        cudaDeviceSynchronize() ;

        cudaMemcpy( Ping , Pong , BufferSize , cudaMemcpyDeviceToDevice ) ;

        std::swap( Ping , Pong ) ;

    }

    cudaMemcpy( & SeedVec[] , Pong , BufferSize , cudaMemcpyDeviceToHost ) ;

    //

    cudaFree( SiteArray ) ;

    cudaFree( Ping ) ;

    cudaFree( Pong ) ;

    cudaFree( Mutex ) ;

    //

    //

    FILE * Output = fopen( Argv[] , "wb" ) ;

    fprintf( Output , "P6\n%d %d\n255\n" , Size , Size ) ;

    std::vector< uchar3 > Pixels( Size * Size ) ;

    for ( int y =  ; y < Size ; ++ y )

    {

        for ( int x =  ; x < Size ; ++ x )

        {

            const int Seed = SeedVec[x + y * Size] ;

            if ( Seed != -  )

            {

                Pixels[x + y * Size] = RandomColorVec[Seed] ;

            }

        }

    }

    for( std::vector< float2 >::const_iterator itr = SiteVec.begin() ; itr != SiteVec.end() ; ++ itr )

    {

        const int x = static_cast< int >( floorf( itr->x ) ) ;

        const int y = static_cast< int >( floorf( itr->y ) ) ;

        Pixels[x + y * Size] = make_uchar3(  ,  ,  ) ;

    }

    fwrite( & Pixels[].x ,  , Pixels.size() , Output ) ;

    fclose( Output ) ;

    return EXIT_SUCCESS ;

}
JFA CUDA
Jump Flood Algorithms for Centroidal Voronoi Tessellation的更多相关文章
- Visulalization Voronoi in OpenSceneGraph
Visulalization Voronoi in OpenSceneGraph eryar@163.com Abstract. In mathematics a Voronoi diagram is ...
- Computer Graphics Research Software
Computer Graphics Research Software Helping you avoid re-inventing the wheel since 2009! Last update ...
- Delaunay Triangulation in OpenCascade
Delaunay Triangulation in OpenCascade eryar@163.com 摘要:本文简要介绍了Delaunay三角剖分的基础理论,并使用OpenCascade的三角剖分算 ...
- [转载]John Burkardt搜集的FORTRAN源代码
Over the years, I have collected, modified, adapted, adopted or created a number of software package ...
- LeetCode Questions List (LeetCode 问题列表)- Java Solutions
因为在开始写这个博客之前,已经刷了100题了,所以现在还是有很多题目没有加进来,为了方便查找哪些没加进来,先列一个表可以比较清楚的查看,也方便给大家查找.如果有哪些题目的链接有错误,请大家留言和谅解, ...
- D3、EChart、HighChart绘图demol
1.echarts: <!DOCTYPE html> <html> <head> <meta charset="utf-8" ...
- 软件项目技术点(1)——d3.interpolateZoom-在两个点之间平滑地缩放平移
AxeSlide软件项目梳理 canvas绘图系列知识点整理 软件参考d3的知识点 我们在软件中主要用到d3.js的核心函数d3.interpolateZoom - 在两个点之间平滑地缩放平移.请 ...
- 【机器学习具体解释】KNN分类的概念、误差率及其问题
转载请注明出处:http://blog.csdn.net/luoshixian099/article/details/50923056 勿在浮沙筑高台 KNN概念 KNN(K-Nearest Neig ...
- D3js-API介绍【英】
Everything in D3 is scoped under the d3 namespace. D3 uses semantic versioning. You can find the cur ...
随机推荐
- yolo_v3训练自己的模型(人脸及deep-sort)
做deep-sort多目标跟踪需要结合yolo_v3进行检测行人 由于我的项目中需要对人脸进行检测,所以需要训练针对人脸的模型 训练样本是来自WIDER-FACE人脸库.(有3w+的图片和标注框) d ...
- Spring面试底层原理的那些问题,你是不是真的懂Spring?
1.什么是 Spring 框架?Spring 框架有哪些主要模块?Spring 框架是一个为 Java 应用程序的开发提供了综合.广泛的基础性支持的 Java 平台.Spring帮助开发者解决了开发中 ...
- [译]ASP.NET Core Web API 中使用Oracle数据库和Dapper看这篇就够了
[译]ASP.NET Core Web API 中使用Oracle数据库和Dapper看这篇就够了 本文首发自:博客园 文章地址: https://www.cnblogs.com/yilezhu/p/ ...
- 自动化运维Ansible安装篇
Ansible自动化工具之--部署篇 ansible是新出现的自动化运维工具,基于Python开发,集合了众多运维工具(puppet.cfengine.chef.func.fabric)的优点,实现了 ...
- HP-Socket v3.2.2
==========================================================================================v3.2.2 upg ...
- Linux软件包管理之RPM命令
目录 1.Linux软件包分类 一.源码包 二.二进制包 2.rpm 包命名规则 3.rpm包安装 4.rpm包升级 5.rpm包卸载 6.查询rpm包是否安装 7.查询软件包的详细信息 8.查询软件 ...
- MySQL索引建立和使用的基本原则
合理设计和使用索引 在关键字段的索引上,建与不建索引,查询速度相差近100倍. 差的索引和没有索引效果一样. 索引并非越多越好,因为维护索引需要成本. 每个表的索引应在5个以下,应合理利用 ...
- 【ASP.NET MVC系列】浅谈ASP.NET MVC 路由
ASP.NET MVC系列文章 [01]浅谈Google Chrome浏览器(理论篇) [02]浅谈Google Chrome浏览器(操作篇)(上) [03]浅谈Google Chrome浏览器(操作 ...
- 第6章 LVM详解
6.1 LVM相关概念和机制 LVM(Logical Volume Manager)可以让分区变得弹性,可以随时随地的扩大和缩小分区大小,前提是该分区是LVM格式的. lvm需要使用的软件包为lvm2 ...
- iptables实战案例详解-技术流ken
简介 关于iptables的介绍网上有很多的资料,大家可以自己找一些关于iptables的工作原理,以及四表五链的简介,对于学习iptables将会事半功倍.本博文将会例举几个工作中常用的iptabl ...