
scrapy实战--爬取最新美剧
现在写一个利用scrapy爬虫框架爬取最新美剧的项目。
准备工作:
目标地址:http://www.meijutt.com/new100.html
爬取项目:美剧名称、状态、电视台、更新时间
1、创建工程目录
mkdir scrapyProject

cd scrapyProject
2、创建工程项目
scrapy startproject meiju100

cd meiju100

scrapy genspider meiju meijutt.com
3、查看目录结构
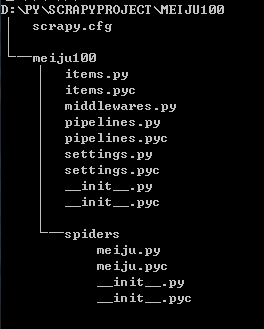
4、设置爬取项目(items.py)
#

# See documentation in:

# http://doc.scrapy.org/en/latest/topics/items.html

import scrapy

class Meiju100Item(scrapy.Item):

    # define the fields for your item here like:

    # name = scrapy.Field()

    storyName = scrapy.Field()

    storyState = scrapy.Field()

    tvStation = scrapy.Field()

    updateTime = scrapy.Field()
5、编写爬取脚本(meiju.py)
# -*- coding: utf-8 -*-

import scrapy

from meiju100.items import Meiju100Item

class MeijuSpider(scrapy.Spider):

    name = "meiju"

    allowed_domains = ["meijutt.com"]

    start_urls = ['http://www.meijutt.com/new100.html']

    def parse(self, response):

        items = []

        subSelector = response.xpath('//ul[@class="top-list  fn-clear"]/li')

        for sub in subSelector:

            item = Meiju100Item()

            item['storyName'] = sub.xpath('./h5/a/text()').extract()

            item['storyState'] = sub.xpath('./span[1]/font/text()').extract()

            if item['storyState']:

                pass

            else:

                item['storyState'] = sub.xpath('./span[1]/text()').extract()

            item['tvStation'] = sub.xpath('./span[2]/text()').extract()

            if item['tvStation']:

                pass

            else:

                item['tvStation'] = [u'未知']

            item['updateTime'] = sub.xpath('./div[2]/text()').extract()

            if item['updateTime']:

                pass

            else:

                item['updateTime'] = sub.xpath('./div[2]/font/text()').extract()

            items.append(item)

        return items
6、对爬取结果的处理
# -*- coding: utf-8 -*-

# Define your item pipelines here

#

# Don't forget to add your pipeline to the ITEM_PIPELINES setting

# See: http://doc.scrapy.org/en/latest/topics/item-pipeline.html

import time

import sys

reload(sys)

sys.setdefaultencoding('utf8')

class Meiju100Pipeline(object):

    def process_item(self, item, spider):

        today = time.strftime('%Y%m%d',time.localtime())

        fileName = today + 'movie.txt'

        with open(fileName,'a') as fp:

            fp.write(item['storyName'][0].encode("utf8") + '\t' + item['storyState'][0].encode("utf8") + '\t' + item['tvStation'][0] + '\t' + item['updateTime'][0] + '\n')

        return item
7、设置settings.py
……

ITEM_PIPELINES = {'meiju100.pipelines.Meiju100Pipeline':1}
8、启动爬虫
scrapy crawl meiju
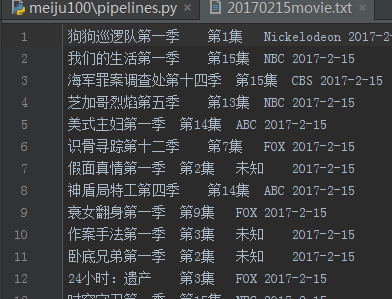
9、结果
10、代码下载
http://files.cnblogs.com/files/kongzhagen/meiju100.zip
scrapy实战--爬取最新美剧的更多相关文章
- 简单的scrapy实战:爬取腾讯招聘北京地区的相关招聘信息
简单的scrapy实战:爬取腾讯招聘北京地区的相关招聘信息 简单的scrapy实战:爬取腾讯招聘北京地区的相关招聘信息 系统环境:Fedora22(昨天已安装scrapy环境) 爬取的开始URL:ht ...
- 教程+资源,python scrapy实战爬取知乎最性感妹子的爆照合集(12G)!
一.出发点: 之前在知乎看到一位大牛(二胖)写的一篇文章:python爬取知乎最受欢迎的妹子(大概题目是这个,具体记不清了),但是这位二胖哥没有给出源码,而我也没用过python,正好顺便学一学,所以 ...
- 爬虫07 /scrapy图片爬取、中间件、selenium在scrapy中的应用、CrawlSpider、分布式、增量式
爬虫07 /scrapy图片爬取.中间件.selenium在scrapy中的应用.CrawlSpider.分布式.增量式 目录 爬虫07 /scrapy图片爬取.中间件.selenium在scrapy ...
- java爬虫系列第二讲-爬取最新动作电影《海王》迅雷下载地址
1. 目标 使用webmagic爬取动作电影列表信息 爬取电影<海王>详细信息[电影名称.电影迅雷下载地址列表] 2. 爬取最新动作片列表 获取电影列表页面数据来源地址 访问http:// ...
- 第三百三十节,web爬虫讲解2—urllib库爬虫—实战爬取搜狗微信公众号—抓包软件安装Fiddler4讲解
第三百三十节,web爬虫讲解2—urllib库爬虫—实战爬取搜狗微信公众号—抓包软件安装Fiddler4讲解 封装模块 #!/usr/bin/env python # -*- coding: utf- ...
- 使用scrapy框架爬取自己的博文(2)
之前写了一篇用scrapy框架爬取自己博文的博客,后来发现对于中文的处理一直有问题- - 显示的时候 [u'python\u4e0b\u722c\u67d0\u4e2a\u7f51\u9875\u76 ...
- 如何提高scrapy的爬取效率
提高scrapy的爬取效率 增加并发: 默认scrapy开启的并发线程为32个,可以适当进行增加.在settings配置文件中修改CONCURRENT_REQUESTS = 100值为100,并发设置 ...
- 九 web爬虫讲解2—urllib库爬虫—实战爬取搜狗微信公众号—抓包软件安装Fiddler4讲解
封装模块 #!/usr/bin/env python # -*- coding: utf-8 -*- import urllib from urllib import request import j ...
- scrapy框架爬取笔趣阁完整版
继续上一篇,这一次的爬取了小说内容 pipelines.py import csv class ScrapytestPipeline(object): # 爬虫文件中提取数据的方法每yield一次it ...
随机推荐
- sql 保留两位小数
select convert(decimal(18,2),1800.2669)
- Low Power之CPF/UPF
1 CPF The Common Power Format is a standard promoted by the Low Power Coalition at Si2. CPF is also ...
- Ubuntu18.0.4查看显示器型号
在官网https://launchpad.net/ubuntu/+source/xresprobe下载二进制包,apt-get目前无法安装xresprobe 输入命令sudo ddcprobe 得到如 ...
- C#语法之委托和事件
从大学就开始做C#这块,也做C#几年了,最近又从ios转回.Net,继续做C#,之前也没有写博客的习惯,写博客也是从我做ios的时候开始的,现在既然又做回了.net,那就写点关于.Net的博客,可能在 ...
- centos6.5下yum安装mysql5.5
第一步就是看linu是否安装了mysql,经过rpm -qa|grep mysql查看到centos下安装了mysql5.1,那就开始卸载咯 2 接下来就是卸载mysql5.1了,命令:rpm -e ...
- SQL Server - 文件组,文件,备份,分区
FileGroup:文件组,为逻辑划分:Files:文件,为实际文件,需要指定文件属于哪个文件组. 使用多个文件的有点:可以将磁盘I/O压力分散,提供按文件和文件组(按文件和文件组进行备份需要设置数据 ...
- “Device eth0 does not seem to be present”解决办法
在KVM中克隆出新的CentOS虚拟机时,出现如下问题:# service network restartShutting down loopback insterface: [ OK ]Bringi ...
- 高并发第十单:J.U.C AQS(AbstractQueuedSynchronizer) 组件:CountDownLatch. CyclicBarrier .Semaphore
这里有一篇介绍AQS的文章 非常好: Java并发之AQS详解 AQS全名:AbstractQueuedSynchronizer,是并发容器J.U.C(java.lang.concurrent)下lo ...
- 高并发第八弹:J.U.C起航(java.util.concurrent)
java.util.concurrent是JDK自带的一个并发的包主要分为以下5部分: 并发工具类(tools) 显示锁(locks) 原子变量类(aotmic) 并发集合(collections) ...
- 深入理解MyBatis的原理:整个体系
前言:工作中虽然用到了 MyBatis,可完全不知道为什么,再不学习就晚了,这里将记录我的学习笔记,整个 MyBatis 的体系. 一.简介 1.传统的JDBC JDBC 是一种典型的桥接模式. 使用 ...