
Scrapy-redis分布式爬虫爬取豆瓣电影详情页
平时爬虫一般都使用Scrapy框架,通常都是在一台机器上跑,爬取速度也不能达到预期效果,数据量小,而且很容易就会被封禁IP或者账号,这时候可以使用代理IP或者登录方式爬,然而代理IP很多时候都很鸡肋,除非使用付费版IP,但是和真实IP差别很大。这时候便有了Scrapy-redis分布式爬虫框架,它基于Scrapy改造,把Scrapy的调度器(scheduler)换成了Scrapy-redis的调度器,可以轻松达到目的,利用多台服务器来爬取数据,而且还可以自动去重,效率高。爬取的数据默认保存在redis缓存中,速度很快。
Scrapy工作原理:

Scrapy-redis工作原理:
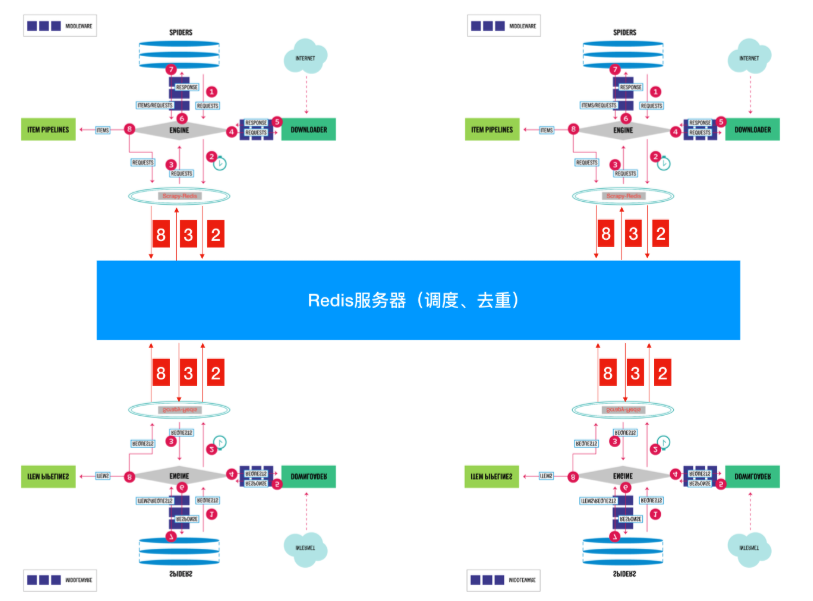
中间的就是调度器
豆瓣电影简易分布式爬虫
我这里直接使用start_urls的方式,数据存入到Mysql中
class DoubanSpider(RedisSpider):

    name = 'douban'

    redis_key = 'douban:start_urls'

    allowed_domains = ['douban.com']

    def start_requests(self):

        urls = get_urls()

        for url in urls:

            yield scrapy.Request(url=url, callback=self.parse)

    def parse(self, response):

        # item_loader = MovieItemLoader(item=MovieItem, response=response)

        #

        # item_loader.add_xpath('title', '')

        item = MovieItem()

        print(response.url)

        item['movieId'] = int(response.url.split('subject/')[1].replace('/', ''))

        item['title'] = response.xpath('//h1/span/text()').extract()[0]

        item['year'] = response.xpath('//h1/span/text()').extract()[1].split('(')[1].split(')')[0] or '2019'

        item['url'] = response.url

        item['cover'] = response.xpath('//a[@class="nbgnbg"]/img/@src').extract()[0]

        try:

            item['director'] = response.xpath('//a[@rel="v:directedBy"]/text()').extract()[0] or '无'

        except Exception:

            item['director'] = '暂无'

        item['major'] = '/'.join(response.xpath('//a[@rel="v:starring"]/text()').extract())

        item['category'] = ','.join(response.xpath('//span[@property="v:genre"]/text()').extract())

        item['time'] = ','.join(response.xpath('//span[@property="v:initialReleaseDate"]/text()').extract())

        try:

            item['duration'] = response.xpath('//span[@property="v:runtime"]/text()').extract()[0]

        except Exception:

            item['duration'] = '暂无'

        item['score'] = response.xpath('//strong[@property="v:average"]/text()').extract()[0]

        item['comment_nums'] = response.xpath('//span[@property="v:votes"]/text()').extract()[0] or 0

        item['desc'] = response.xpath('//span[@property="v:summary"]/text()').extract()[0].strip()

        actor_list = response.xpath('//ul[@class="celebrities-list from-subject __oneline"]/li/a/@title').extract()

        actor_img_list = response.xpath('//ul[@class="celebrities-list from-subject __oneline"]/li/a/div/@style').extract()

        actor_img_list = [i.split('url(')[1].replace(')', '') for i in actor_img_list]

        item['actor_name_list'] = '----'.join(actor_list)

        item['actor_img_list'] = '----'.join(actor_img_list)

        yield item
settings.py文件
BOT_NAME = 'MovieSpider'

SPIDER_MODULES = ['MovieSpider.spiders']

NEWSPIDER_MODULE = 'MovieSpider.spiders'

# REDIS_HOST = '127.0.0.1'

# REDIS_PORT = 6379

REDIS_URL = 'redis://username:password@xxx.xxx.xxx.xxx:6379'

# Obey robots.txt rules

ROBOTSTXT_OBEY = False

SCHEDULER = "scrapy_redis.scheduler.Scheduler"

# Ensure all spiders share same duplicates filter through redis.

DUPEFILTER_CLASS = "scrapy_redis.dupefilter.RFPDupeFilter"

ITEM_PIPELINES = {

    'scrapy_redis.pipelines.RedisPipeline': 300,

    'MovieSpider.pipelines.MysqlPipeline': 200,

}
这里只是为了多台服务器一起爬取,没有手动在redis中推入起始的URL
此时将爬虫项目上传到其他服务器上,一起开始
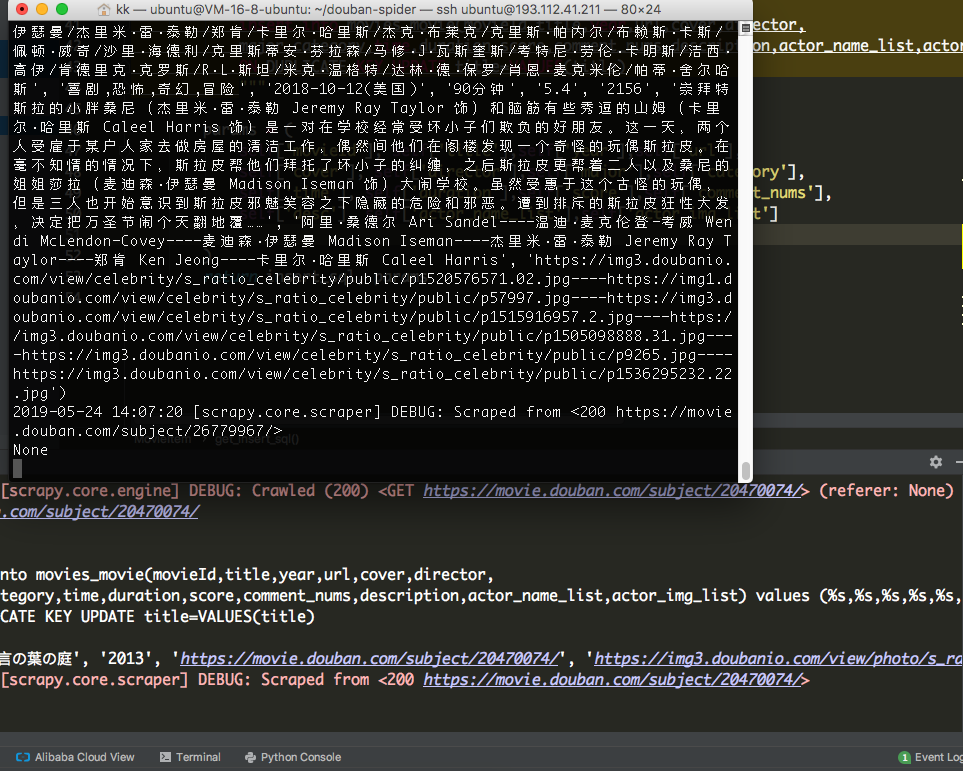
效果如下:
Scrapy-redis分布式爬虫爬取豆瓣电影详情页的更多相关文章
- Scrapy中用xpath/css爬取豆瓣电影Top250:解决403HTTP status code is not handled or not allowed
好吧,我又开始折腾豆瓣电影top250了,只是想试试各种方法,看看哪一种的方法效率是最好的,一直进行到这一步才知道 scrapy的强大,尤其是和selector结合之后,速度飞起.... 下面我就采用 ...
- python 爬虫&爬取豆瓣电影top250
爬取豆瓣电影top250from urllib.request import * #导入所有的request,urllib相当于一个文件夹,用到它里面的方法requestfrom lxml impor ...
- Python爬虫爬取豆瓣电影之数据提取值xpath和lxml模块
工具:Python 3.6.5.PyCharm开发工具.Windows 10 操作系统.谷歌浏览器 目的:爬取豆瓣电影排行榜中电影的title.链接地址.图片.评价人数.评分等 网址:https:// ...
- python爬取豆瓣电影第一页数据and使用with open() as读写文件
# _*_ coding : utf-8 _*_ # @Time : 2021/11/2 9:58 # @Author : 秋泊酱 # @File : 获取豆瓣电影第一页 # @Project : 爬 ...
- python3 爬虫---爬取豆瓣电影TOP250
第一次爬取的网站就是豆瓣电影 Top 250,网址是:https://movie.douban.com/top250?start=0&filter= 分析网址'?'符号后的参数,第一个参数's ...
- Python爬虫爬取豆瓣电影名称和链接,分别存入txt,excel和数据库
前提条件是python操作excel和数据库的环境配置是完整的,这个需要在python中安装导入相关依赖包: 实现的具体代码如下: #!/usr/bin/python# -*- coding: utf ...
- python爬虫-爬取豆瓣电影数据
#!/usr/bin/python# coding=utf-8# 作者 :Y0010026# 创建时间 :2018/12/16 16:27# 文件 :spider_05.py# IDE :PyChar ...
- Python爬虫-爬取豆瓣电影Top250
#!usr/bin/env python3 # -*- coding:utf-8-*- import requests from bs4 import BeautifulSoup import re ...
- scrapy爬虫框架教程(二)-- 爬取豆瓣电影TOP250
scrapy爬虫框架教程(二)-- 爬取豆瓣电影TOP250 前言 经过上一篇教程我们已经大致了解了Scrapy的基本情况,并写了一个简单的小demo.这次我会以爬取豆瓣电影TOP250为例进一步为大 ...
随机推荐
- (转)不看绝对后悔的Linux三剑客之sed实战精讲
不看绝对后悔的Linux三剑客之sed实战精讲 原文:http://blog.51cto.com/hujiangtao/1923718 二.Linux三剑客之sed命令精讲 1,前言 我们都知道,在L ...
- 分布式锁-session-事务相关
1. 分布式锁--zookeeper 1). client调用create()方法创建"/root/lock_"节点,注意节点类型是EPHEMERAL_SEQUENTIAL. 2) ...
- Windows安全认证是如何进行的?[Kerberos篇]
最近一段时间都在折腾安全(Security)方面的东西,比如Windows认证.非对称加密.数字证书.数字签名.TLS/SSL.WS-Security等.如果时间允许,我很乐意写一系列的文章与广大网友 ...
- oracle存储过程jdbc调用
package com.jckb.procedure; import java.sql.CallableStatement; import java.sql.Connection; import ja ...
- Arduino连接pH计
关于arduino连接ph,核心的东西就是对ph传感器返回的信号值进行一系列的操作,注意因为返回的信号很弱,而且外部环境对其影响也很大,所以需要在电路设计上加入一些功能,比如信号放大.滤波等,电路设计 ...
- ActionListener 监听事件源产生的事件
用户在窗体上对组件进行一定动作,比如鼠标点击,会产生一些相应的事件,如ActionEvents,ChangeEvents,ItemEvents等,来响应用户的鼠标点击行为.通过实现ActionList ...
- ELF interpreter /libexec/ld-elf32.so.1 not found
ELF interpreter /libexec/ld-elf32.so.1 not found错误, 其实就是在64位平台上运行32位软件的不兼容造成的.找个64的包安装就上ok了.
- 上传高德地图-express框架
1.首先要注册高德地图,完后成为开发者 2.控制台里获取自己的key值 3.在要显示地图的页面添加如下的代码 <script type="text/javascript" s ...
- HDU 1028 Ignatius and the Princess III伊格和公主III(AC代码)母函数
题意: 输入一个数n,求组合成此数字可以有多少种方法,每一方法是不记录排列顺序的.用来组成的数字可以有1.2.3....n.比如n个1组成了n,一个n也组成n.这就算两种.1=1,2=1+1=2,3= ...
- git简易使用指南
git简易使用指南 Git是一个分布式版本控制/软件配置管理软件,原是Linux内核开发者林纳斯·托瓦兹(Linus Torvalds)为更好地管理Linux内核开发而设计.应注意的是,这与GNU I ...