
Lucene学习笔记1(V7.1)
Lucene是一个搜索类库,solr、nutch和elasticsearch都是基于Lucene。个人感觉学习高级搜索引擎应用程序之前 有必要了解Lucene。
开发环境:idea maven springboot
开始贴代码:
maven配置
 <parent>

        <groupId>org.springframework.boot</groupId>

        <artifactId>spring-boot-starter-parent</artifactId>

        <version>1.4..RELEASE</version>

    </parent>

    <properties>

        <java.version>1.8</java.version>

    </properties>

    <dependencies>

        <dependency>

            <groupId>org.springframework.boot</groupId>

            <artifactId>spring-boot-starter</artifactId>

        </dependency>

        <dependency>

            <groupId>org.springframework.boot</groupId>

            <artifactId>spring-boot-starter-thymeleaf</artifactId>

        </dependency>

        <!-- hot swapping, disable cache for template, enable live reload -->

        <dependency>

            <groupId>org.springframework.boot</groupId>

            <artifactId>spring-boot-devtools</artifactId>

            <optional>true</optional>

        </dependency>

            <!--Lucene-->

            <dependency>

                <groupId>org.apache.lucene</groupId>

                <artifactId>lucene-core</artifactId>

                <version>7.1.</version>

            </dependency>

            <!--中文分词器,一般分词器适用于英文分词(common)-->

            <dependency>

                <groupId>org.apache.lucene</groupId>

                <artifactId>lucene-analyzers-smartcn</artifactId>

                <version>7.1.</version>

            </dependency>

            <dependency>

                <groupId>org.apache.lucene</groupId>

                <artifactId>lucene-queryparser</artifactId>

                <version>7.1.</version>

            </dependency>

            <!--检索关键字高亮显示-->

            <dependency>

                <groupId>org.apache.lucene</groupId>

                <artifactId>lucene-highlighter</artifactId>

                <version>7.1.</version>

            </dependency>

            <!--Lucene-->

            <dependency>

                <groupId>junit</groupId>

                <artifactId>junit</artifactId>

                <version>4.12</version>

            </dependency>

    </dependencies>

    <build>

        <plugins>

            <!-- Package as an executable jar/war -->

            <plugin>

                <groupId>org.springframework.boot</groupId>

                <artifactId>spring-boot-maven-plugin</artifactId>

            </plugin>

        </plugins>

    </build>
辅助类
public class LuceneConstants {

    public static final String CONTENTS="contents";

    public static final String FILE_NAME="filename";

    public static final String FILE_PATH="filepath";

    public static final int MAX_SEARCH = ;

    public  static final String IndexDir ="E:\\Lucene\\Index";

    public  static final String DataDir ="E:\\Lucene\\Data";

    public  static final String ArticleDir ="E:\\Lucene\\Files\\article.txt";

}
调用Lucene
public class Indexer {

    public void addEntity() throws IOException {

        Article article = new Article();

        //article.setId(1);

        //article.setTitle("Lucene全文检索");

        //article.setContent("Lucene是apache软件基金会4 jakarta项目组的一个子项目,是一个开放源代码的全文检索引擎工具包,但它不是一个完整的全文检索引擎,而是一个全文检索引擎的架构,提供了完整的查询引擎和索引引擎,部分文本分析引擎(英文与德文两种西方语言)。");

        article.setId();

        article.setTitle("Solr搜索引擎");

        article.setContent("Solr是基于Lucene框架的搜索莹莹程序,是一个开放源代码的全文检索引擎。");

        final Path path = Paths.get(LuceneConstants.IndexDir);

        Directory directory = FSDirectory.open(path);//索引存放目录 存在磁盘

        //Directory RAMDirectory= new RAMDirectory();// 存在内存

        Analyzer analyzer = new StandardAnalyzer();

        IndexWriterConfig indexWriterConfig = new IndexWriterConfig(analyzer);

        //indexWriterConfig.setOpenMode(IndexWriterConfig.OpenMode.CREATE);

        indexWriterConfig.setOpenMode(IndexWriterConfig.OpenMode.APPEND);

        IndexWriter indexWriter = new IndexWriter(directory, indexWriterConfig);//更新或创建索引

        Document document = new Document();

        document.add(new TextField("id", article.getId().toString(), Field.Store.YES));

        document.add(new TextField("title", article.getTitle(), Field.Store.YES));

        document.add(new TextField("content", article.getContent(), Field.Store.YES));

        indexWriter.addDocument(document);

        indexWriter.close();

    }

    public void addFile() throws IOException {

        final Path path = Paths.get(LuceneConstants.IndexDir);

        Directory directory = FSDirectory.open(path);

        Analyzer analyzer=new StandardAnalyzer();

        IndexWriterConfig indexWriterConfig=new IndexWriterConfig(analyzer);

        indexWriterConfig.setOpenMode(IndexWriterConfig.OpenMode.CREATE);

        IndexWriter indexWriter=new IndexWriter(directory,indexWriterConfig);

        InputStreamReader isr = new InputStreamReader(new FileInputStream(LuceneConstants.ArticleDir), "GBK");//.txt文档,不设置格式会乱码

        BufferedReader bufferedReader=new BufferedReader(isr);

        String content="";

        while ((content=bufferedReader.readLine())!=null){

            Document document=new Document();

            document.add(new TextField("content",content,Field.Store.YES) );

            indexWriter.addDocument(document);

        }

        bufferedReader.close();

        indexWriter.close();

    }

    public List<String> SearchFiles() throws IOException, ParseException {

        String queryString = "Solr";

        final Path path = Paths.get(LuceneConstants.IndexDir);

        Directory directory = FSDirectory.open(path);//索引存储位置

        Analyzer analyzer = new StandardAnalyzer();//分析器

        //单条件

        //关键词解析

        //QueryParser queryParser=new QueryParser("content",analyzer);

        //Query query=queryParser.parse(queryString);

        //多条件

        Query mQuery = MultiFieldQueryParser.parse(new String[]{"Solr"},new String[]{"content"},new StandardAnalyzer());

        IndexReader indexReader = DirectoryReader.open(directory);//索引阅读器

        IndexSearcher indexSearcher = new IndexSearcher(indexReader);//查询

        //TopDocs topDocs=indexSearcher.search(query,3);

        TopDocs topDocs=indexSearcher.search(mQuery,);

        long count = topDocs.totalHits;

        ScoreDoc[] scoreDocs = topDocs.scoreDocs;

        List<String> list=new ArrayList<String>();

        list.add(String.valueOf(count));

        Integer cnt=;

        for (ScoreDoc scoreDoc : scoreDocs) {

            Document document = indexSearcher.doc(scoreDoc.doc);

            //list.add(cnt.toString()+"-"+"相关度:"+scoreDoc.score+"-----time:"+document.get("time"));

            //list.add("|||");

            //list.add(cnt.toString()+"-"+document.get("content"));

            list.add(document.get("content"));

            cnt++;

        }

        return  list;

    }

}
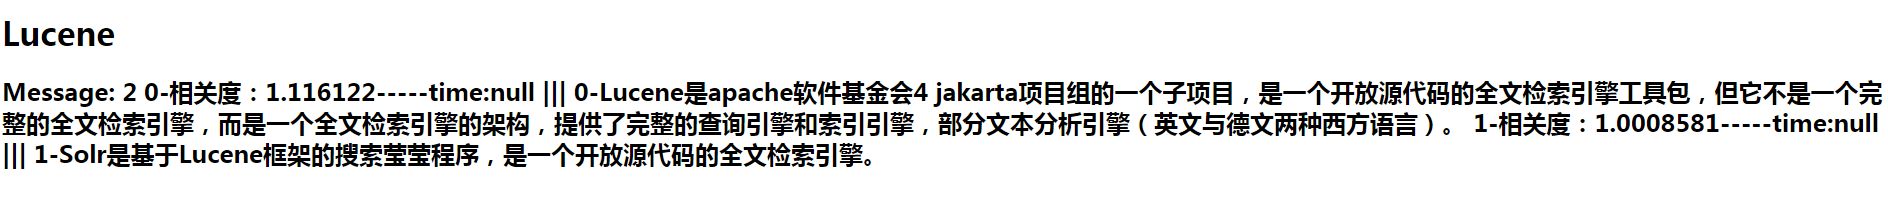
查看运行效果
@Controller

public class LuceneController {

    @RequestMapping("/add")

    public String welcomepage(Map<String, Object> model) {

        try {

            Indexer indexer = new Indexer();

            indexer.addEntity();

            model.put("message", "Success");

        } catch (IOException ex) {

            model.put("message", "Failure");

        }

        return "welcome";

    }

    @RequestMapping("/file")

    public String fileindex(Map<String, Object> model) {

        try {

            Indexer indexer = new Indexer();

            indexer.addFile();

            model.put("message", "SuccessF");

        } catch (IOException ex) {

            model.put("message", "FailureF");

        }

        return "welcome";

    }

    @RequestMapping("/search")

    public String searchindex(Map<String, Object> model) {

        try {

            Indexer indexer = new Indexer();

            List<String> rlts = indexer.SearchFiles();

            String message = "";

            for (String str : rlts) {

                message += str + " ";

            }

            model.put("message", message);

        } catch (Exception ex) {

            model.put("message", "FailureF");

        }

        return "welcome";

    }

}
Lucene学习笔记1(V7.1)的更多相关文章
- Lucene学习笔记(更新)
1.Lucene学习笔记 http://www.cnblogs.com/hanganglin/articles/3453415.html
- Lucene学习笔记2-Lucene的CRUD(V7.1)
在进行CRUD的时候请注意IndexWriterConfig的设置. public class IndexCRUD { "}; private String citys[]={"j ...
- Apache Lucene学习笔记
Hadoop概述 Apache lucene: 全球第一个开源的全文检索引擎工具包 完整的查询引擎和搜索引擎 部分文本分析引擎 开发人员在此基础建立完整的全文检索引擎 以下为转载:http://www ...
- Lucene学习笔记
师兄推荐我学习Lucene这门技术,用了两天时间,大概整理了一下相关知识点. 一.什么是Lucene Lucene即全文检索.全文检索是计算机程序通过扫描文章中的每一个词,对每一个词建立一个索引,指明 ...
- Lucene学习笔记: 四,Lucene索引过程分析
对于Lucene的索引过程,除了将词(Term)写入倒排表并最终写入Lucene的索引文件外,还包括分词(Analyzer)和合并段(merge segments)的过程,本次不包括这两部分,将在以后 ...
- Solr学习笔记1(V7.2)
下载压缩包http://archive.apache.org/dist/lucene/,解压后放到某一盘符下面 Windows下启动命令 :\solr-7.2.0>bin\solr.cmd st ...
- Lucene学习笔记:基础
Lucence是Apache的一个全文检索引擎工具包.可以将采集的数据存储到索引库中,然后在根据查询条件从索引库中取出结果.索引库可以存在内存中或者存在硬盘上. 本文主要是参考了这篇博客进行学习的,原 ...
- Lucene学习笔记: 五,Lucene搜索过程解析
一.Lucene搜索过程总论 搜索的过程总的来说就是将词典及倒排表信息从索引中读出来,根据用户输入的查询语句合并倒排表,得到结果文档集并对文档进行打分的过程. 其可用如下图示: 总共包括以下几个过程: ...
- lucene学习笔记:三,Lucene的索引文件格式
Lucene的索引里面存了些什么,如何存放的,也即Lucene的索引文件格式,是读懂Lucene源代码的一把钥匙. 当我们真正进入到Lucene源代码之中的时候,我们会发现: Lucene的索引过程, ...
随机推荐
- js 停止事件冒泡 阻止浏览器的默认行为(阻止a标签跳转 )
在前端开发工作中,由于浏览器兼容性等问题,我们会经常用到"停止事件冒泡"和"阻止浏览器默认行为". 1..停止事件冒泡 JavaScript代码 //如果提供了 ...
- 手动编译protobuf3的C++源码
Windows下编译 官方文档 第三方文档 准备工具 Visual Studio 2013 CMake https://cmake.org/ Git https://git-scm.com/ 需要注意 ...
- Python文件读写 - 文件r+ a+ open读写实际表现[示例]
先说结论: 文件r+ open: 1. write()不能实现插入写,它总是覆盖写或附加写: 2. 如果文件一打开即write(),则从开头覆盖写; 3. 如果文件一打开,用f.seek()指定文件指 ...
- JavaScript的DOM编程--05--获取文本节点
获取文本节点: 1). 步骤: 元素节点 --> 获取元素节点的子节点 2). 若元素节点只有文本节点一个子节点, 例如 <li id="bj" name=" ...
- Elasticsearch强制重置未分配的分片(unassigned)
强制重置未分片的分片,这个问题源自于Elasticsearch维护中,Node意外退出的场景. 意外退出后Elasticsearch由于网络原因或者jvm性能压力,未能短时间内分配分片. 看一下分片的 ...
- 6.前端基于react,后端基于.net core2.0的开发之路(6) 服务端渲染(SSR)
0.源码地址 https://gitee.com/teambp/ScaffoldClient 这个地址下载对应源码. 1.服务端渲染是啥? 就是在服务器进行页面渲染(废话),当页面展示后,显示的就是 ...
- Ubuntu 16.04 LTS运行robo3t报错
系统环境:Ubuntu 16.04 LTS. 安装robomongo Robo 3T,运行时报以下错误: jaxu@jaxu-ubuntu:/usr/local/share/robo3t--linux ...
- C#高级编程学习一-----------------第五章泛型
三层架构之泛型应用 概述 1.命名约定 泛型类型以T开头或就是T. 2.泛型类 2.1.创建泛型类
- MyEclipse2015上传项目到GitHub(很详细)
MyEclipse 2015 默认已经安装了git插件,在MyEclipse中上传项目到github的步骤如下: 1.github官网(https://github.com)申请开通账号(略) 1.1 ...
- JavaScript(六)函数
函数的声明方式 function name () {} 函数声明 var name = function(){} 函数表达式 所有函数都有返回值 未return 的函数 返回值 是 unde ...