
MapReduce实战(七)GroupingComparator
需求:
Order_0000001,Pdt_01,222.8
Order_0000001,Pdt_05,25.8
Order_0000002,Pdt_05,325.8
Order_0000002,Pdt_03,522.8
Order_0000002,Pdt_04,122.4
Order_0000003,Pdt_01,222.8
按照订单的编号分组,计算出每组的商品价格最大值。
分析:
我们可以把订单编号当做key,然后按照在reduce端去找出每组的最大值。在这里,我想介绍另外一种方法,顺便介绍GroupingComparator。
我们可以自定义一个类型,然后通过GroupingComparator来让其被看成一组(到达reduce端),如果我们对类型进行从大到小的排序,根据MapReduce的规则,同一组的内容到达reduce端,是取第一个内容的key作为reduce的key的,我们不妨利用这个规则,写一个OrderBean的类型,只要让其orderid相同,就被分到同一组,这样一来,到达reduce时,相同id的所有bean已经被看成一组,且金额最大的那个一排在第一位,就是我们想要的结果。
代码:
OrderBean.java:
package com.darrenchan.mr.groupingcomparator;

import java.io.DataInput;

import java.io.DataOutput;

import java.io.IOException;

import org.apache.hadoop.io.DoubleWritable;

import org.apache.hadoop.io.Text;

import org.apache.hadoop.io.WritableComparable;

public class OrderBean implements WritableComparable<OrderBean>{

    private Text itemid;

    private DoubleWritable amount;

    public OrderBean() {

    }

    public OrderBean(Text itemid, DoubleWritable amount) {

        set(itemid, amount);

    }

    public void set(Text itemid, DoubleWritable amount) {

        this.itemid = itemid;

        this.amount = amount;

    }

    public Text getItemid() {

        return itemid;

    }

    public DoubleWritable getAmount() {

        return amount;

    }

    @Override

    public int compareTo(OrderBean o) {

//        int cmp = this.itemid.compareTo(o.getItemid());

//        if (cmp == 0) {

        int    cmp = -this.amount.compareTo(o.getAmount());

//        }

        return cmp;

    }

    @Override

    public void write(DataOutput out) throws IOException {

        out.writeUTF(itemid.toString());

        out.writeDouble(amount.get());

    }

    @Override

    public void readFields(DataInput in) throws IOException {

        String readUTF = in.readUTF();

        double readDouble = in.readDouble();

        this.itemid = new Text(readUTF);

        this.amount= new DoubleWritable(readDouble);

    }

    @Override

    public String toString() {

        return itemid.toString() + "\t" + amount.get();

    }

}
ItemidGroupingComparator.java:
package com.darrenchan.mr.groupingcomparator;

import org.apache.hadoop.io.WritableComparable;

import org.apache.hadoop.io.WritableComparator;

/**

 * 利用reduce端的GroupingComparator来实现将一组bean看成相同的key

 *

 */

public class ItemidGroupingComparator extends WritableComparator {

    //传入作为key的bean的class类型,以及制定需要让框架做反射获取实例对象

    protected ItemidGroupingComparator() {

        super(OrderBean.class, true);

    }

    @Override

    public int compare(WritableComparable a, WritableComparable b) {

        OrderBean abean = (OrderBean) a;

        OrderBean bbean = (OrderBean) b;

        //比较两个bean时,指定只比较bean中的orderid

        return abean.getItemid().compareTo(bbean.getItemid());

    }

}
ItemIdPartitioner.java:
package com.darrenchan.mr.groupingcomparator;

import org.apache.hadoop.io.NullWritable;

import org.apache.hadoop.mapreduce.Partitioner;

public class ItemIdPartitioner extends Partitioner<OrderBean, NullWritable>{

    @Override

    public int getPartition(OrderBean bean, NullWritable value, int numReduceTasks) {

        //相同id的订单bean,会发往相同的partition

        //而且,产生的分区数,是会跟用户设置的reduce task数保持一致

        return (bean.getItemid().hashCode() & Integer.MAX_VALUE) % numReduceTasks;

    }

}
SecondarySort.java:
package com.darrenchan.mr.groupingcomparator;

import java.io.IOException;

import org.apache.commons.lang.StringUtils;

import org.apache.hadoop.conf.Configuration;

import org.apache.hadoop.fs.Path;

import org.apache.hadoop.io.DoubleWritable;

import org.apache.hadoop.io.LongWritable;

import org.apache.hadoop.io.NullWritable;

import org.apache.hadoop.io.Text;

import org.apache.hadoop.mapreduce.Job;

import org.apache.hadoop.mapreduce.Mapper;

import org.apache.hadoop.mapreduce.Reducer;

import org.apache.hadoop.mapreduce.lib.input.FileInputFormat;

import org.apache.hadoop.mapreduce.lib.output.FileOutputFormat;

import com.sun.xml.bind.v2.schemagen.xmlschema.List;

/**

 *

 */

public class SecondarySort {

    static class SecondarySortMapper extends Mapper<LongWritable, Text, OrderBean, NullWritable>{

        OrderBean bean = new OrderBean();

        @Override

        protected void map(LongWritable key, Text value, Context context) throws IOException, InterruptedException {

            String line = value.toString();

            String[] fields = StringUtils.split(line, ",");

            bean.set(new Text(fields[0]), new DoubleWritable(Double.parseDouble(fields[2])));

            context.write(bean, NullWritable.get());

        }

    }

    static class SecondarySortReducer extends Reducer<OrderBean, NullWritable, OrderBean, NullWritable>{

        //到达reduce时,相同id的所有bean已经被看成一组,且金额最大的那个一排在第一位

        @Override

        protected void reduce(OrderBean key, Iterable<NullWritable> values, Context context) throws IOException, InterruptedException {

            context.write(key, NullWritable.get());

        }

    }

    public static void main(String[] args) throws Exception {

        Configuration conf = new Configuration();

        Job job = Job.getInstance(conf);

        job.setJarByClass(SecondarySort.class);

        job.setMapperClass(SecondarySortMapper.class);

        job.setReducerClass(SecondarySortReducer.class);

        job.setOutputKeyClass(OrderBean.class);

        job.setOutputValueClass(NullWritable.class);

        FileInputFormat.setInputPaths(job, new Path("/grouping/srcdata"));

        FileOutputFormat.setOutputPath(job, new Path("/grouping/output"));

        //在此设置自定义的Groupingcomparator类

        job.setGroupingComparatorClass(ItemidGroupingComparator.class);

        //在此设置自定义的partitioner类

        job.setPartitionerClass(ItemIdPartitioner.class);

        job.setNumReduceTasks(3);

        job.waitForCompletion(true);

    }

}
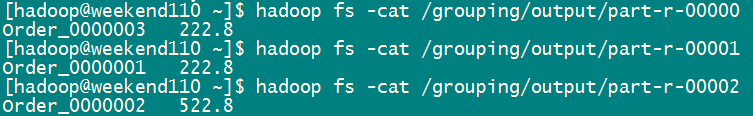
运行结果:
MapReduce实战(七)GroupingComparator的更多相关文章
- Python爬虫实战七之计算大学本学期绩点
大家好,本次为大家带来的项目是计算大学本学期绩点.首先说明的是,博主来自山东大学,有属于个人的学生成绩管理系统,需要学号密码才可以登录,不过可能广大读者没有这个学号密码,不能实际进行操作,所以最主要的 ...
- SpringSecurity权限管理系统实战—七、处理一些问题
目录 SpringSecurity权限管理系统实战-一.项目简介和开发环境准备 SpringSecurity权限管理系统实战-二.日志.接口文档等实现 SpringSecurity权限管理系统实战-三 ...
- 《OD大数据实战》MapReduce实战
一.github使用手册 1. 我也用github(2)——关联本地工程到github 2. Git错误non-fast-forward后的冲突解决 3. Git中从远程的分支获取最新的版本到本地 4 ...
- MapReduce实战:统计不同工作年限的薪资水平
1.薪资数据集 我们要写一个薪资统计程序,统计数据来自于互联网招聘hadoop岗位的招聘网站,这些数据是按照记录方式存储的,因此非常适合使用 MapReduce 程序来统计. 2.数据格式 我们使用的 ...
- mapreduce实战:统计美国各个气象站30年来的平均气温项目分析
气象数据集 我们要写一个气象数据挖掘的程序.气象数据是通过分布在美国各地区的很多气象传感器每隔一小时进行收集,这些数据是半结构化数据且是按照记录方式存储的,因此非常适合使用 MapReduce 程序来 ...
- C# Redis实战(七)
七.修改数据 在上一篇 C# Redis实战(六)中介绍了如何查询Redis中数据,本篇将介绍如何修改Redis中相关数据.大家都知道Redis是key-value型存储系统,所以应该可以修改key, ...
- MapReduce实战--倒排索引
本文地址:http://www.cnblogs.com/archimedes/p/mapreduce-inverted-index.html,转载请注明源地址. 1.倒排索引简介 倒排索引(Inver ...
- MapReduce实战(三)分区的实现
需求: 在实战(一)的基础 上,实现自定义分组机制.例如根据手机号的不同,分成不同的省份,然后在不同的reduce上面跑,最后生成的结果分别存在不同的文件中. 对流量原始日志进行流量统计,将不同省份的 ...
- MapReduce实战:邮箱统计及多输出格式实现
紧接着上一篇博文我们学习了MapReduce得到输出格式之后,在这篇博文里,我们将通过一个实战小项目来熟悉一下MultipleOutputs(多输出)格式的用法. 项目需求: 假如这里有一份邮箱数据文 ...
随机推荐
- 报错:configure: error: no acceptable C compiler found in $PATH
运行以下命令报错: ./configure 错误: checking whether to enable maintainer-specific portions of Makefiles... ye ...
- [ES6] 08. Destructuring Assignment -- 1
Here is the way you get value from an object: var obj = { color: "blue" } console.log(obj. ...
- 【转】java中抽象类与接口的区别
转自:http://blog.chinaunix.net/uid-20586655-id-215667.html 含有abstract修饰符的class 即为抽象类,abstract类不能创建实例对象 ...
- windows下ACE安装使用教程(转)
ACE简介:ACE是一个跨平台的用于并发通信的C++框架.它提供了丰富的C++封装器和框架组件.使用ACE,开发者可以开发出高性能,实时的通信服务和应用.ACE利用进程间通信,事件分离,动态链接和并发 ...
- Linux内核project导论——网络:路由:路由原理
总览 路由表 IP层通过路由将数据包送达该送达的目的地址,这就要求在整个网络中建立正确的路由表.路由表的内容是记录要到达哪里下一跳须要发到哪里(能够是port能够是ip),如此整个网络在单个节点仅仅知 ...
- 后台dubug有值且sql也打印出来执行了但是前台就是查不到数据
记录在sturts2里面 摔得最深的一次 public String queryJoinAccount(){ //用来存储分页的数据 pageMap=new HashMap<String, Ob ...
- Strace--系统调用分析问题集锦
---------------------------------------------------------------------------------------------------- ...
- pandas drop_duplicates
函数 : DataFrame.drop_duplicates(subset=None, keep='first', inplace=False) 参数:这个drop_duplicate方法是对Data ...
- Navicat for MySQL再谈之无奈之下还是去安装Navicat Premium
不多说,直接上干货! 首先,Navicat for MySQL没有查看数据库属性. 其次,没有这个功能多和强大,在走过一段弯路之后,果断放弃Navicat for MySQL,而使用Navicat P ...
- mysql去除严格模式/插入数据库遇到重复保证唯一
1.找到mysql目录下的数据库的my.ini文件.找到sql-mode=STRICT_TRANS_TABLES,NO_AUTO_CREATE_USER,NO_ENGINE_SUBSTITUTION ...