
Not All Samples Are Created Equal: Deep Learning with Importance Sampling
@article{katharopoulos2018not,
title={Not All Samples Are Created Equal: Deep Learning with Importance Sampling},
author={Katharopoulos, Angelos and Fleuret, F},
journal={arXiv: Learning},
year={2018}}
概
本文提出一种删选合适样本的方法, 这种方法基于收敛速度的一个上界, 而并非完全基于gradient norm的方法, 使得计算比较简单, 容易实现.
主要内容
设\((x_i,y_i)\)为输入输出对, \(\Psi(\cdot;\theta)\)代表网络, \(\mathcal{L}(\cdot, \cdot)\)为损失函数, 目标为
\theta^* = \arg \min_{\theta} \frac{1}{N} \sum_{i=1}^N\mathcal{L}(\Psi(x_i;\theta),y_i),
\]
其中\(N\)是总的样本个数.
假设在第\(t\)个epoch的时候, 样本(被选中)的概率分布为\(p_1^t,\ldots,p_N^t\), 以及梯度权重为\(w_1^t, \ldots, w_N^t\), 那么\(P(I_t=i)=p_i^t\)且
\theta_{t+1}=\theta_t-\eta w_{I_t}\nabla_{\theta_t} \mathcal{L}(\Psi(x_{I_t};\theta_t),y_{I_t}),
\]
在一般SGD训练中\(p_i=1/N,w_i=1\).
定义\(S\)为SGD的收敛速度为:
S :=-\mathbb{E}_{P_t}[\|\theta_{t+1}-\theta^*\|_2^2-\|\theta_t-\theta^*\|_2^2],
\]
如果我们令\(w_i=\frac{1}{Np_i}\) 则
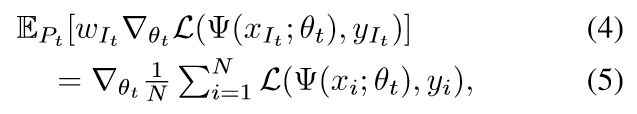
定义\(G_i=w_i\nabla_{\theta_t} \mathcal{L}(\Psi(x_{i};\theta_t),y_{i})\)

我们自然希望\(S\)能够越大越好, 此时即负项越小越好.
定义\(\hat{G}_i \ge \|\nabla_{\theta_t} \mathcal{L}(\Psi(x_{i};\theta_t),y_{i})\|_2\), 既然
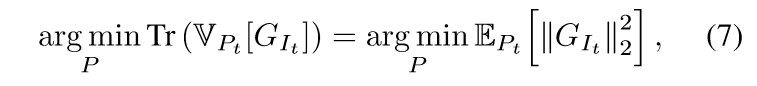
(7)式我有点困惑,我觉得(7)式右端和最小化(6)式的负项(\(\mathrm{Tr}(\mathbb{V}_{P_t}[G_{I_t}])+\|\mathbb{E}_{P_t}[G_{I_t}]\|_2^2\))是等价的.
于是有
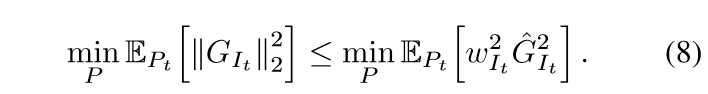
最小化右端(通过拉格朗日乘子法)可得\(p_i \propto \hat{G}_i\), 所以现在我们只要找到一个\(\hat{G}_i\)即可.
这个部分需要引入神经网络的反向梯度的公式, 之前有讲过,只是论文的符号不同, 这里不多赘诉了.

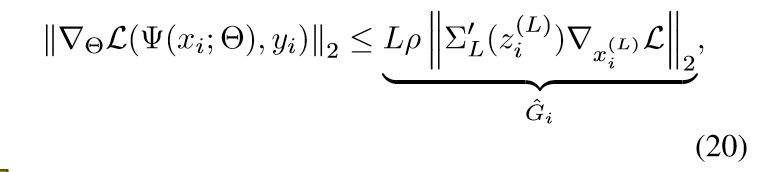
注意\(\rho\)的计算是比较复杂的, 但是\(p_i \propto \hat{G}_i\), 所以我们只需要计算\(\|\cdot\|\)部分, 设此分布为\(g\).
另外, 在最开始的时候, 神经网络没有得到很好的训练, 权重大小相差无几, 这个时候是近似正态分布的, 所以作者考虑设计一个指标,来判断是否需要根据样本分布\(g\)来挑选样本. 作者首先衡量

显然当这部分足够大的时候我们可以采用分布\(g\)而非正态分布\(u\), 但是这个指标不易判断, 作者进步除以\(\mathrm{Tr}(\mathbb{V}_u[G_i])\).

显然\(\tau\)越大越好, 我们自然可以人为设置一个\(\tau_{th}\). 算法如下

最后, 个人认为这个算法能减少计算量主要是因为样本少了, 少在一开始用正态分布抽取了一部分, 所以...
"代码"
主要是\(\hat{G}_i\)部分的计算, 因为涉及到中间变量的导数, 所以需要用到retain_grad().
"""

这里只是一个例子

"""

import torch

import torch.nn as nn

class Net(nn.Module):

    def __init__(self):

        super(Net, self).__init__()

        self.dense = nn.Sequential(

            nn.Linear(10, 256),

            nn.ReLU(),

            nn.Linear(256, 10),

        )

        self.final = nn.ReLU()

    def forward(self, x):

        z = self.dense(x)

        z.retain_grad()

        out = self.final(z)

        return out, z

if __name__ == "__main__":

    net = Net()

    criterion = nn.MSELoss()

    x = torch.rand((2, 10))

    y = torch.rand((2, 10))

    out, z = net(x)

    loss = criterion(out, y)

    loss.backward()

    print(z.grad) #这便是我们所需要的
Not All Samples Are Created Equal: Deep Learning with Importance Sampling的更多相关文章
- Accelerating Deep Learning by Focusing on the Biggest Losers
目录 概 相关工作 主要内容 代码 Accelerating Deep Learning by Focusing on the Biggest Losers 概 思想很简单, 在训练网络的时候, 每个 ...
- (转) The major advancements in Deep Learning in 2016
The major advancements in Deep Learning in 2016 Pablo Tue, Dec 6, 2016 in MACHINE LEARNING DEEP LEAR ...
- Deep Learning in R
Introduction Deep learning is a recent trend in machine learning that models highly non-linear repre ...
- Summary on deep learning framework --- PyTorch
Summary on deep learning framework --- PyTorch Updated on 2018-07-22 21:25:42 import osos.environ[ ...
- [C3] Andrew Ng - Neural Networks and Deep Learning
About this Course If you want to break into cutting-edge AI, this course will help you do so. Deep l ...
- Deep Learning 5_深度学习UFLDL教程:PCA and Whitening_Exercise(斯坦福大学深度学习教程)
前言 本文是基于Exercise:PCA and Whitening的练习. 理论知识见:UFLDL教程. 实验内容:从10张512*512自然图像中随机选取10000个12*12的图像块(patch ...
- (转)WHY DEEP LEARNING IS SUDDENLY CHANGING YOUR LIFE
Main Menu Fortune.com E-mail Tweet Facebook Linkedin Share icons By Roger Parloff Illustration ...
- (转)Deep Learning Research Review Week 1: Generative Adversarial Nets
Adit Deshpande CS Undergrad at UCLA ('19) Blog About Resume Deep Learning Research Review Week 1: Ge ...
- (转)The 9 Deep Learning Papers You Need To Know About (Understanding CNNs Part 3)
Adit Deshpande CS Undergrad at UCLA ('19) Blog About The 9 Deep Learning Papers You Need To Know Abo ...
随机推荐
- 23. 关于Ubuntu中Could not get lock /var/lib/dpkg/lock解决方案
原文:https://blog.csdn.net/u011596455/article/details/60322568 版权声明:本文为博主原创文章,转载请附上博文链接! 在Ubuntu中,有时候运 ...
- Hive(二)【数据类型、类型转换】
目录 一.基本数据类型 案例实操 二.集合数据类型 案例实操 Map类型 三.类型转换 1.隐式类型转换 2.显示(强制)类型转换 一.基本数据类型 HIVE MySQL JAVA 长度 例子 TIN ...
- AI作曲的一个点子
通常的AI作曲都是通过拆分音乐为几个声道, 然后再把各个声道拆成音符去分析. 我忽然之间有个想法,是否可以继续拆分下去. 音符就是一些有规则的高低电平,这样把音符拆成电平. 一定会带来巨大的运算,但如 ...
- Shell学习(一)——Shell简介
参考博客: [1]Shell简介
- gen already exists but is not a source folder. Convert to a source folder or rename it 的解决办法
1. Right click on the project and go to "Properties" //鼠标右键点击项目,然后选中Properties 2. Select ...
- Springboot Oauth2 集成Swagger2权限验证实战
Swagger是什么?能干什么?在这就不展开讲解了.本文主要讲解如何集成OAuth2的Password模式权限验证,验证接口是否具有权限. 引入依赖 <dependency> <gr ...
- 【Linux】【Services】【SaaS】Docker+kubernetes(12. 部署prometheus/grafana/Influxdb实现监控)
1.简介 1.1. 官方网站: promethos:https://prometheus.io/ grafana:https://grafana.com/ 1.2. 架构图 2. 环境 2.1. 机器 ...
- 什么是javaScript闭包
闭包是与函数有着紧密的关系,它是函数的代码在运行过程中的一个动态环境,是一个运行期的概念. 所谓闭包,是指词法表示包括不必计算的变量的函数.也就是说,该函数能够使用函数外定义的变量. 在程序语言中,所 ...
- log4j漏洞的产生原因和解决方案,小白都能看懂!!!!
核弹级bug Log4j,相信很多人都有所耳闻了,这两天很多读者都在问我关于这个bug的原理等一些问题,今天咱们就专门写一篇文章,一起聊一聊这个核弹级别的bug的产生原理以及怎么防止 产生原因 其实这 ...
- C++STL标准库学习笔记(二)二分查找
二.STL中的二分查找算法 1.binary_search 2.lower_bound 3.upper_bound 记得#include<algorithm>! 前言: 在这个笔记中,我把 ...