
python框架Scrapy中crawlSpider的使用
一、创建Scrapy工程
 #scrapy startproject 工程名

 scrapy startproject demo3
二、进入工程目录,根据爬虫模板生成爬虫文件
 #scrapy genspider -l # 查看可用模板

 #scrapy genspider -t 模板名 爬虫文件名 允许的域名

 scrapy genspider -t crawl test sohu.com
三、设置IP池或用户代理(middlewares.py文件)
 # -*- coding: utf-8 -*-

 # 导入随机模块

 import random

 # 导入有关IP池有关的模块

 from scrapy.downloadermiddlewares.httpproxy import HttpProxyMiddleware

 # 导入有关用户代理有关的模块

 from scrapy.downloadermiddlewares.useragent import UserAgentMiddleware

 # IP池

 class HTTPPROXY(HttpProxyMiddleware):

     # 初始化 注意一定是 ip=''

     def __init__(self, ip=''):

         self.ip = ip

     def process_request(self, request, spider):

         item = random.choice(IPPOOL)

         try:

             print("当前的IP是:"+item["ipaddr"])

             request.meta["proxy"] = "http://"+item["ipaddr"]

         except Exception as e:

             print(e)

             pass

 # 设置IP池

 IPPOOL = [

     {"ipaddr": "182.117.102.10:8118"},

     {"ipaddr": "121.31.102.215:8123"},

     {"ipaddr": "1222.94.128.49:8118"}

 ]

 # 用户代理

 class USERAGENT(UserAgentMiddleware):

     #初始化 注意一定是 user_agent=''

     def __init__(self, user_agent=''):

         self.user_agent = user_agent

     def process_request(self, request, spider):

         item = random.choice(UPPOOL)

         try:

             print("当前的User-Agent是:"+item)

             request.headers.setdefault('User-Agent', item)

         except Exception as e:

             print(e)

             pass

 # 设置用户代理池

 UPPOOL = [

     "Mozilla/5.0 (Windows NT 10.0; WOW64; rv:52.0) Gecko/20100101 Firefox/52.0", "Mozilla/5.0 (Windows NT 10.0; Win64; x64) AppleWebKit/537.36 (KHTML, like Gecko) Chrome/59.0.3071.115 Safari/537.36", "Mozilla/5.0 (Windows NT 10.0; Win64; x64) AppleWebKit/537.36 (KHTML, like Gecko) Chrome/51.0.2704.79 Safari/537.36 Edge/14.14393"

 ]
四、settngs.py配置
 #========================================

 # 设置IP池和用户代理

 # 禁止本地Cookie

 COOKIES_ENABLED = False

 # 下载中间件配置指向(注意这里的工程名字是"demo3",指向DOWNLOADER_MIDDLEWARES = {

     # 'scrapy.downloadermiddlewares.httpproxy.HttpProxyMiddleware':123,

     # 'demo3.middlewares.HTTPPROXY' : 125,

     'scrapy.downloadermiddlewares.useragent.UserAgentMiddleware': 2,

     'demo3.middlewares.USERAGENT': 1

 }

 # 管道指向配置(注意这里的工程名字是"demo3",指向ITEM_PIPELINES = {

     'demo3.pipelines.Demo3Pipeline': 300,

 }

 #============================================
五、定义爬取关注的数据(items.py文件)
 # -*- coding: utf-8 -*-

 import scrapy

 # Define here the models for your scraped items

 #

 # See documentation in:

 # http://doc.scrapy.org/en/latest/topics/items.html

 class Demo3Item(scrapy.Item):

     name = scrapy.Field()

     link = scrapy.Field()
六、爬虫文件编写(test.py)
 # -*- coding: utf-8 -*-

 import scrapy

 from scrapy.linkextractors import LinkExtractor

 from scrapy.spiders import CrawlSpider, Rule

 from demo3.items import Demo3Item

 class TestSpider(CrawlSpider):

     name = 'test'

     allowed_domains = ['sohu.com']

     start_urls = ['http://www.sohu.com/']

     rules = (

         Rule(LinkExtractor(allow=('http://news.sohu.com'), allow_domains=('sohu.com')), callback='parse_item', follow=False),

         #Rule(LinkExtractor(allow=('.*?/n.*?shtml'),allow_domains=('sohu.com')), callback='parse_item', follow=False),

     )

     def parse_item(self, response):

         i = Demo3Item()

         i['name'] = response.xpath('//div[@class="news"]/h1/a/text()').extract()

         i['link'] = response.xpath('//div[@class="news"]/h1/a/@href').extract()

         return i
七、管道文件编写(pipelines.py)
 # -*- coding: utf-8 -*-

 import codecs

 import json

 # Define your item pipelines here

 #

 # Don't forget to add your pipeline to the ITEM_PIPELINES setting

 # See: http://doc.scrapy.org/en/latest/topics/item-pipeline.html

 class Demo3Pipeline(object):

     def __init__(self):

         self.file = codecs.open("E:/workspace/PyCharm/codeSpace/books/python_web_crawler_book/chapter17/demo3/1.json", "wb", encoding='utf-8')

     def process_item(self, item, spider):

         for j in range(0, len(item["name"])):

             name = item["name"][j]

             link = item["link"][j]

             datas = {"name": name, "link": link}

             i = json.dumps(dict(datas), ensure_ascii=False)

             line = i + '\n'

             self.file.write(line)

         return item

     def close_spider(self, spider):

         self.file.close()
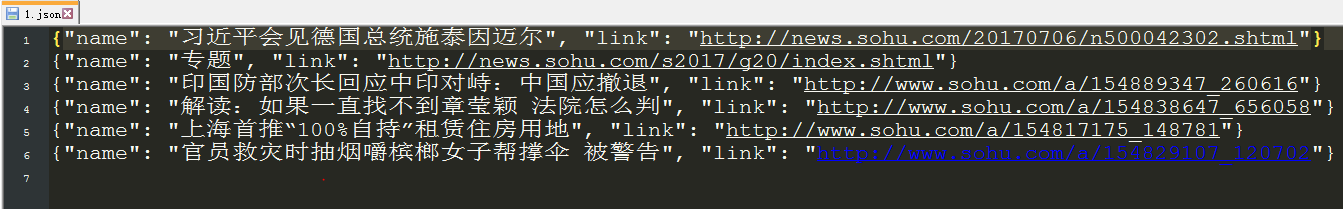
八、测试(scrapy crawl test )之后,生成了1.json文件
python框架Scrapy中crawlSpider的使用的更多相关文章
- python框架Scrapy中crawlSpider的使用——爬取内容写进MySQL
一.先在MySQL中创建test数据库,和相应的site数据表 二.创建Scrapy工程 #scrapy startproject 工程名 scrapy startproject demo4 三.进入 ...
- python框架Django中MTV框架之VIew(业务控制器)
MTV框架之VIew(业务控制器) 关注公众号"轻松学编程"了解更多. 1.什么是视图 视图层=路由表(urls.py)+视图函数(views.py) 其角色相当于MVC中的Con ...
- python框架Django中MTV框架之Template(模板/界面)
MTV框架之Template(模板/界面) 关注公众号"轻松学编程"了解更多. 1.模板目录位置 应用下 不需要注册 无法跨应用地进行复用 工程下 需要注册 settings.py ...
- python框架Django中MTV之Model(数据模型)
MTV框架之Model(数据模型) 关注公众号"轻松学编程"了解更多. 1.连接MySQL数据库 项目中的settings.py设置范例 # 配置数据库 DATABASES = { ...
- python框架Django中的MTV架构
MTV架构 关注公众号"轻松学编程"了解更多. 通过V对M和T进行连接,用户通过T(界面)对服务器进行访问(发送请求),T把请求传给V(调度),V调用M(数据模型)获取数据,把 ...
- scrapy 中crawlspider 爬虫
爬取目标网站: http://www.chinanews.com/rss/rss_2.html 获取url后进入另一个页面进行数据提取 检查网页: 爬虫该页数据的逻辑: Crawlspider爬虫类: ...
- python框架django中结合vue进行前后端分离
一:创建django项目 1.django-admin startproject mysite # 创建mysite项目 2.django-admin startapp app01# 创建app01应 ...
- python框架Scrapy报错TypeError: 'float' object is not iterable解决
原因是:Twisted版本高了. 解决办法: 只要把Twisted库降级到16.6.0即可: pip3 install Twisted== 注:Twisted16..0安装后,会自动卸载高版本的Twi ...
- 教你分分钟学会用python爬虫框架Scrapy爬取心目中的女神
本博文将带领你从入门到精通爬虫框架Scrapy,最终具备爬取任何网页的数据的能力.本文以校花网为例进行爬取,校花网:http://www.xiaohuar.com/,让你体验爬取校花的成就感. Scr ...
随机推荐
- jquery中ajax的相关事件汇总
Jquery ajax事件分类 (一) 局部事件 local events 局部事件:在单个Ajax请求对象中绑定的事件,每个 Ajax 请求对象能够依据须要绑定自己的局部事件 .局部事件仅仅会被那个 ...
- C语言控制台打印3D爱心图案
非常多程序猿都认为自己的编程工作十分的鼓噪乏味.一整天面对的都是一些写不完的代码和改不完的Bug.今天我们要给大家分享一些有趣的C语言代码,也许能够为你无聊的工作带来一丝乐趣. 这些代码能够完毕几个不 ...
- php 获取客户端的浏览器信息
就是访问的时候,通过服务端来判断用户是否为移动端,如果是的话就重定向(移动端的页面).事实上现在都是一套搞定的了. 但是还是记录一下吧.没准以后用的到 http://detectmobilebr ...
- 使用 P3P 规范让 IE 跨域接受第三方 cookie
前两天帮同事处理一个 js 跨域问题,使用 jsonp 跨域提交用户名密码请求,实现自动登录第三方网站,即 SSO(single-sign-on) 单点登录,一处登录处处登录.在 Chrome 下没问 ...
- [elk]logstash的grok匹配逻辑grok+date+mutate
重点参考: http://blog.csdn.net/qq1032355091/article/details/52953837 logstash的精髓: grok插件原理 date插件原理 kv插件 ...
- HDU 4969 Just a Joke(积分)
HDU 4969 Just a Joke pid=4969" target="_blank" style="">题目链接 推公式,r′=dr/d ...
- ZOJ 3703 Happy Programming Contest(0-1背包)
http://acm.zju.edu.cn/onlinejudge/showProblem.do?problemCode=3703 Happy Programming Contest Time Lim ...
- .net SQL分页
1.分页SQL declare @pagesize integer,@cpage integer; --变量定义 ; --页码大小 ; --当前页 ---@cpage 为 第一页的时候 --selec ...
- python-sqlite3之占位符
The sqlite3 module supports two kinds of placeholders: question marks (qmark style) and named placeh ...
- 李洪强iOS开发之iOS社区收集
李洪强iOS开发之iOS社区收集 项目 简述 github 全球最大的代码仓库,无论是iOS开发还是Android开发没有人不知道这个网站,它也是一个社区,你可以去follow(关注)某些人或公司. ...