
Map Reduce Application(Partitioninig/Binning)
Map Reduce Application(Partitioninig/Group data by a defined key)
Assuming we want to group data by the year(2008 to 2016) of their [last access date time]. For each year, we use a reducer to collect them and output the data in this group/partition(year of the last access datetime). So, we want the MR to partition our key by year. We will lean what's the default partitioner and see how to set custom partitioner.
The default partitioner:
 public int getPartition(K key, V value,

                           int numReduceTasks) {

     return (key.hashCode() & Integer.MAX_VALUE) % numReduceTasks;

  }
Custom Partitioner:
job.setPartitionerClass(CustomPartitioner.class)
With blew partitioner, the data of different year of [last access date time] will be assigned to different / unique partition. The num of reduce tasks is 9.
 public static class CustomPartitioner extends Partitioner<Text, Text>{

 @Override

 public int getPartition(Text key, Text value, int numReduceTasks){

      if(numReduceTasks == 0){

          return 0;

      }

      return key-2008

 }
Binning pattern
The text/comments/answer/question....contains the specific words will be written into the corresponding files from mapper.
See below picture to understand the binning pattern. It is easier than partitioning as it does not have partition/sorting/shuffling and reducer(job.setNumReduceTasks(0)). The outputs from mappers compose the final outputs.
MultipleOutputs.addNamedOutput(job,"namedoutput",TextOutputFormat.class, NullWritable.class, Text.class)
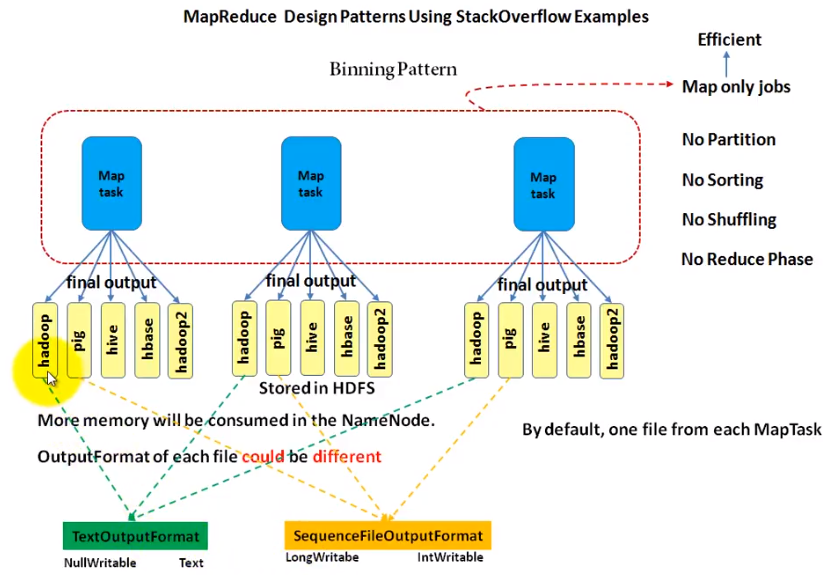
In the mapper setup function, create the MultipleOutputs intance by calling its constructor
MultipleOutputs(TaskInputOutputContext<?,?,KEYOUT,VALUEOUT> context)

Creates and initializes multiple outputs support, it should be instantiated in the Mapper/Reducer setup method.
 @Override

 protected void setup(Context context){

     maltipleOutputs = new MultipleOurputs(context);

 }
Write your logic in the mapper function and output the result. "$tag/$tag-tag" means folder $pag will be created and $tag-tag is the prefix of the files(to distinguish the different mappers with suffix).
See doc for MultipleOutputs:https://hadoop.apache.org/docs/r3.0.1/api/org/apache/hadoop/mapreduce/lib/output/MultipleOutputs.html
 if(tag.equalsIgnoreCase("pig"){

     multipleOutputs.write("namedoutput",key,value,"pig/pig-tag");

 }

 if(tag.equalsIgnoreCase("hive"){

     multipleOutputs.write("namedoutput",key,value,"hive/hive-tag");

 }

 .....
Map Reduce Application(Partitioninig/Binning)的更多相关文章
- Map Reduce Application(Join)
We are going to explain how join works in MR , we will focus on reduce side join and map side join. ...
- Map Reduce Application(Top 10 IDs base on their value)
Top 10 IDs base on their value First , we need to set the reduce to 1. For each map task, it is not ...
- mapreduce: 揭秘InputFormat--掌控Map Reduce任务执行的利器
随着越来越多的公司采用Hadoop,它所处理的问题类型也变得愈发多元化.随着Hadoop适用场景数量的不断膨胀,控制好怎样执行以及何处执行map任务显得至关重要.实现这种控制的方法之一就是自定义Inp ...
- MapReduce剖析笔记之三:Job的Map/Reduce Task初始化
上一节分析了Job由JobClient提交到JobTracker的流程,利用RPC机制,JobTracker接收到Job ID和Job所在HDFS的目录,够早了JobInProgress对象,丢入队列 ...
- python--函数式编程 (高阶函数(map , reduce ,filter,sorted),匿名函数(lambda))
1.1函数式编程 面向过程编程:我们通过把大段代码拆成函数,通过一层一层的函数,可以把复杂的任务分解成简单的任务,这种一步一步的分解可以称之为面向过程的程序设计.函数就是面向过程的程序设计的基本单元. ...
- 记一次MongoDB Map&Reduce入门操作
需求说明 用Map&Reduce计算几个班级中,每个班级10岁和20岁之间学生的数量: 需求分析 学生表的字段: db.students.insert({classid:1, age:14, ...
- filter,map,reduce,lambda(python3)
1.filter filter(function,sequence) 对sequence中的item依次执行function(item),将执行的结果为True(符合函数判断)的item组成一个lis ...
- map reduce
作者:Coldwings链接:https://www.zhihu.com/question/29936822/answer/48586327来源:知乎著作权归作者所有,转载请联系作者获得授权. 简单的 ...
- python基础——map/reduce
python基础——map/reduce Python内建了map()和reduce()函数. 如果你读过Google的那篇大名鼎鼎的论文“MapReduce: Simplified Data Pro ...
随机推荐
- 史上最简单的SpringCloud教程 | 第十篇: 高可用的服务注册中心(Finchley版本)
转载请标明出处: 原文首发于 https://www.fangzhipeng.com/springcloud/2018/08/30/sc-f10-eureka/ 本文出自方志朋的博客 文章 史上最简单 ...
- java web项目用cookie记住用户名、密码
1.jsp页面: <% String flag = (String)session.getAttribute("flag")==null?"":(Stri ...
- Use PerfHUD ES to Do Frame Capture Android Game
Author: http://www.cnblogs.com/open-coder/p/3898224.html Get Start This is short tutorial about how ...
- HTML基础之常用标签
Meta 标签介绍 Meta的属性有两种:name和http-equiv name属性用于描述网页,对应于content <meta name="Generator" con ...
- 新花生壳+tomcat 发布javaWeb项目【亲测有效】
一.新花生壳1.0 在花生壳官网(http://www.oray.com)上下载<新花生壳1.0>的安装软件,软件安装完成后,需要注册,注册成功后花生壳官网会给我们分配一个域名,样式大概为 ...
- Django中间件执行顺序
中间件 Django中的中间件是一个轻量级.底层的插件系统,可以介入Django的请求和响应处理过程,修改Django的输入或输出.中间件的设计为开发者提供了一种无侵入式的开发方式,增强了Django ...
- 09.安装Collabora Online服务
安装Collabora Online服务 参考博客:http://blog.sina.com.cn/s/blog_16b158be80102xp5u.html 一.安装docker服务 yum ins ...
- 登录验证码的生成Java代码
package example7; import java.awt.Color;import java.awt.Font;import java.awt.Graphics2D;import java. ...
- 2.1 摄像头V4L2驱动框架分析
学习目标:学习V4L2(V4L2:vidio for linux version 2)摄像头驱动框架,分析vivi.c(虚拟视频硬件相关)驱动源码程序,总结V4L2硬件相关的驱动的步骤: 一.V4L ...
- Python 爬虫 (二)
cookiejar模块: 管理储存cookie,将传出的http请求添加cookie cookie存储在内存中,CookieJar示例回收后cookie将自动消失 实例:用cookjar访问人人网主页 ...