
Spring AOP 实现读写分离
原文地址:Spring AOP 实现读写分离
博客地址:http://www.extlight.com
一、前言
上一篇《MySQL 实现主从复制》 文章中介绍了 MySQL 主从复制的搭建,为了在项目上契合数据库的主从架构,本篇将介绍在应用层实现对数据库的读写分离。
二、原理
配置主从数据源,当接收请求时,执行具体方法之前(拦截),判断请求具体操作(读或写),最终确定从哪个数据源获取连接访问数据库。
在 JavaWeb 开发中,有 3 种方式可以对请求进行拦截:
filter:拦截所有请求

intercetor:拦截 handler/Action

aop 切面:依赖切入点
不难看出,使用 AOP 切面进行拦截最合理和灵活,因此本文将介绍使用 AOP 实现读写分离功能。
三、编码
本文只张贴关键性代码,详细代码请下载文章末尾源码进行查看。
3.1 代码
1)DynamicDataSourceHolder 确保线程安全:
/**

 *

 * 使用ThreadLocal技术来记录当前线程中的数据源的key

 *

 */

public class DynamicDataSourceHolder {

    //写库对应的数据源key

    private static final String MASTER = "master";

    //读库对应的数据源key

    private static final String SLAVE = "slave";

    //使用ThreadLocal记录当前线程的数据源key

    private static final ThreadLocal<String> holder = new ThreadLocal<String>();

    /**

     * 设置数据源key

     * @param key

     */

    public static void putDataSourceKey(String key) {

        holder.set(key);

    }

    /**

     * 获取数据源key

     * @return

     */

    public static String getDataSourceKey() {

        return holder.get();

    }

    /**

     * 标记写库

     */

    public static void markMaster(){

        putDataSourceKey(MASTER);

    }

    /**

     * 标记读库

     */

    public static void markSlave(){

        putDataSourceKey(SLAVE);

    }

}
2)定义 AOP 切面判断当前线程的读写操作
/**

 * 定义数据源的AOP切面,通过该Service的方法名判断是应该走读库还是写库

 *

 */

public class DataSourceAspect {

    /**

     * 在进入Service方法之前执行

     *

     * @param point 切面对象

     */

    public void before(JoinPoint point) {

        // 获取到当前执行的方法名

        String methodName = point.getSignature().getName();

        if (isSlave(methodName)) {

            // 标记为读库

            DynamicDataSourceHolder.markSlave();

        } else {

            // 标记为写库

            DynamicDataSourceHolder.markMaster();

        }

    }

    /**

     * 判断是否为读库

     *

     * @param methodName

     * @return

     */

    private Boolean isSlave(String methodName) {

        // 方法名以query、find、get开头的方法名走从库

        return StringUtils.startsWithAny(methodName, "query", "find", "get");

    }

}
3)定义动态数据源,确定最终使用的数据源:
/**

 * 定义动态数据源,实现通过集成Spring提供的AbstractRoutingDataSource,只需要实现determineCurrentLookupKey方法即可

 *

 * 由于DynamicDataSource是单例的,线程不安全的,所以采用ThreadLocal保证线程安全,由DynamicDataSourceHolder完成。

 *

 */

public class DynamicDataSource extends AbstractRoutingDataSource{

    @Override

    protected Object determineCurrentLookupKey() {

        // 使用DynamicDataSourceHolder保证线程安全,并且得到当前线程中的数据源key

    	String dataSourceKey = DynamicDataSourceHolder.getDataSourceKey();

    	System.out.println("dataSourceKey ======> "+dataSourceKey);

        return dataSourceKey;

    }

}
3.2 配置文件
1)jdbc.properties
jdbc.driver=com.mysql.jdbc.Driver

jdbc.master.url=jdbc:mysql://192.168.2.21/mysql_test?characterEncoding=utf-8&allowMultiQueries=true&serverTimezone=UTC

jdbc.master.username=root

jdbc.master.password=tiger

jdbc.slave01.url=jdbc:mysql://192.168.2.22/mysql_test?characterEncoding=utf-8&allowMultiQueries=true&serverTimezone=UTC

jdbc.slave01.username=root

jdbc.slave01.password=tiger
2)applicationContext.xml
<?xml version="1.0" encoding="UTF-8"?>

<beans xmlns="http://www.springframework.org/schema/beans"

       xmlns:xsi="http://www.w3.org/2001/XMLSchema-instance"

       xmlns:context="http://www.springframework.org/schema/context"

       xmlns:tx="http://www.springframework.org/schema/tx"

       xmlns:aop="http://www.springframework.org/schema/aop"

       xsi:schemaLocation="http://www.springframework.org/schema/beans

					http://www.springframework.org/schema/beans/spring-beans-4.0.xsd

					http://www.springframework.org/schema/context

                    http://www.springframework.org/schema/context/spring-context-4.0.xsd

                    http://www.springframework.org/schema/tx

                    http://www.springframework.org/schema/tx/spring-tx-4.0.xsd

                    http://www.springframework.org/schema/aop

                    http://www.springframework.org/schema/aop/spring-aop-4.0.xsd">

    <context:component-scan base-package="com.light.*">

        <context:exclude-filter type="annotation" expression="org.springframework.stereotype.Controller"/>

    </context:component-scan>

    <context:property-placeholder location="classpath:*.properties"/>

    <!-- 数据源 -->

    <bean id="dataSource" class="com.light.dynamicdatasource.DynamicDataSource">

    	<property name="targetDataSources">

    		<map key-type="java.lang.String">

    			<entry key="master" value-ref="masterDataSource"></entry>

    			<entry key="slave" value-ref="slave01DataSource"></entry>

    		</map>

    	</property>

    	<!-- 默认数据源 -->

    	<property name="defaultTargetDataSource" ref="masterDataSource"/>

    </bean>

    <!-- 主库数据源 -->

    <bean id="masterDataSource" class="com.alibaba.druid.pool.DruidDataSource" destroy-method="close">

        <property name="url" value="${jdbc.master.url}"/>

        <property name="username" value="${jdbc.master.username}"/>

        <property name="password" value="${jdbc.master.password}"/>

        <property name="driverClassName" value="${jdbc.driver}"/>

        <property name="initialSize" value="5"/>

        <property name="minIdle" value="5"/>

        <property name="maxActive" value="50"/>

    </bean>

    <!-- 从库数据源 -->

    <bean id="slave01DataSource" class="com.alibaba.druid.pool.DruidDataSource" destroy-method="close">

        <property name="url" value="${jdbc.slave01.url}"/>

        <property name="username" value="${jdbc.slave01.username}"/>

        <property name="password" value="${jdbc.slave01.password}"/>

        <property name="driverClassName" value="${jdbc.driver}"/>

        <property name="initialSize" value="5"/>

        <property name="minIdle" value="5"/>

        <property name="maxActive" value="50"/>

    </bean>

    <bean id="sqlSessionFactory" class="org.mybatis.spring.SqlSessionFactoryBean">

        <property name="dataSource" ref="dataSource"></property>

        <!-- 引入 mybatis 配置文件 -->

        <property name="configLocation" value="classpath:mybatis/SqlMapConfig.xml"></property>

         <property name="typeAliasesPackage" value="com.light.domain"></property>

        <!-- sql配置文件 -->

         <property name="mapperLocations" value="classpath:mybatis/mapper/*.xml"></property>

    </bean>

    <!-- 扫描Mapper -->

    <bean class="org.mybatis.spring.mapper.MapperScannerConfigurer">

        <property name="basePackage" value="com.light.mapper"></property>

        <property name="sqlSessionFactoryBeanName" value="sqlSessionFactory"></property>

    </bean>

    <!-- 事务管理器 -->

    <bean id="transactionManager" class="org.springframework.jdbc.datasource.DataSourceTransactionManager">

        <property name="dataSource" ref="dataSource"/>

    </bean>

    <!-- 通知 -->

    <tx:advice id="txAdvice" transaction-manager="transactionManager">

        <tx:attributes>

            <!-- 传播行为 -->

            <tx:method name="save*" propagation="REQUIRED"/>

            <tx:method name="insert*" propagation="REQUIRED"/>

            <tx:method name="delete*" propagation="REQUIRED"/>

            <tx:method name="update*" propagation="REQUIRED"/>

            <tx:method name="find*" propagation="SUPPORTS" read-only="true"/>

            <tx:method name="get*" propagation="SUPPORTS" read-only="true"/>

            <tx:method name="query*" propagation="SUPPORTS" read-only="true"/>

        </tx:attributes>

    </tx:advice>

    <!-- 切面 -->

    <bean id="dataSourceAspect" class="com.light.dynamicdatasource.DataSourceAspect"></bean>

    <aop:config proxy-target-class="true">

    	<aop:pointcut id="myPointcut" expression="execution(* com.light.service.*.*(..))" />

    	<!-- 事务切面 -->

        <aop:advisor advice-ref="txAdvice" pointcut-ref="myPointcut"/>

    	<!-- 自定义切面 -->

    	<aop:aspect ref="dataSourceAspect" order="-9999">

    		<aop:before method="before" pointcut-ref="myPointcut" />

    	</aop:aspect>

    </aop:config>

    <tx:annotation-driven transaction-manager="transactionManager"/>

</beans>
四、测试
笔者在项目的 web 层写了 UserController 类,里边包含 get 和 delete 两个方法。
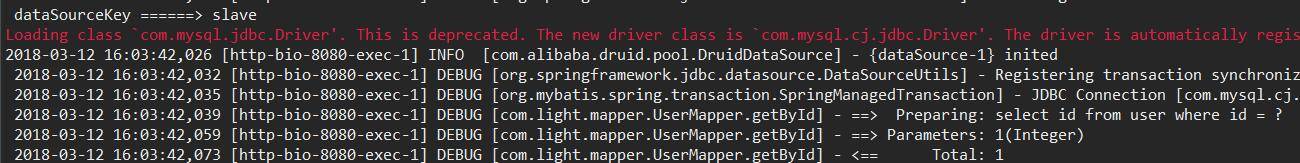
正常情况,当访问 get 方法(读操作)时,使用从库数据源,那么控制台应该打印 slave 。
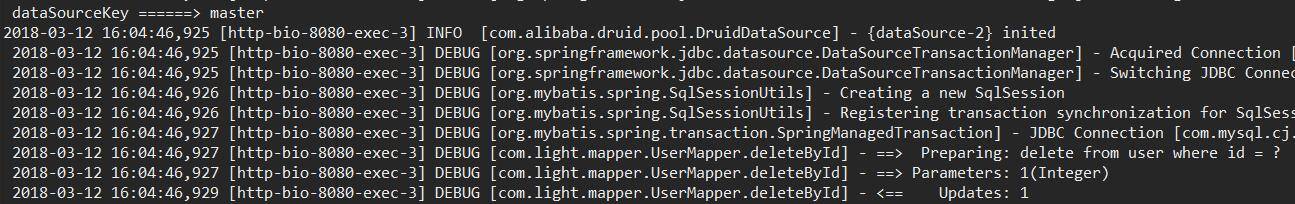
正常情况,当访问 delete 方法(写操作)时,使用主库数据源,那么控制台应该打印 master 。
以下是 2 次测试结果:
get 方法:
delete 方法:
五、源码
Spring AOP 实现读写分离的更多相关文章
- 使用Spring AOP实现读写分离(MySql实现主从复制)
1. 背景 我们一般应用对数据库而言都是“读多写少”,也就说对数据库读取数据的压力比较大,有一个思路就是说采用数据库集群的方案,其中一个是主库,负责写入数据,我们称之为:写库: 其它都是从库,负责读 ...
- spring+mybatis实现读写分离
springmore-core spring+ibatis实现读写分离 特点 无缝结合spring+ibatis,对于程序员来说,是透明的 除了修改配置信息之外,程序的代码不需要修改任何东西 支持sp ...
- 使用Spring实现MySQL读写分离
1. 为什么要进行读写分离 大量的JavaWeb应用做的是IO密集型任务, 数据库的压力较大, 需要分流 大量的应用场景, 是读多写少, 数据库读取的压力更大 一个很自然的思路是使用一主多从的数据库集 ...
- 使用Spring实现MySQL读写分离(转)
使用Spring实现MySQL读写分离 为什么要进行读写分离 大量的JavaWeb应用做的是IO密集型任务, 数据库的压力较大, 需要分流 大量的应用场景, 是读多写少, 数据库读取的压力更大 一个很 ...
- 基于spring的aop实现读写分离与事务配置
项目开发中经常会遇到读写分离等多数据源配置的需求,在Java项目中可以通过Spring AOP来实现多数据源的切换. 一.Spring事务开启流程 Spring中通常通过@Transactional来 ...
- Spring+mybatis 实现aop数据库读写分离,多数据库源配置
在数据库层面大都采用读写分离技术,就是一个Master数据库,多个Slave数据库.Master库负责数据更新和实时数据查询,Slave库当然负责非实时数据查询.因为在实际的应用中,数据库都是读多写少 ...
- Spring 实现数据库读写分离
随着互联网的大型网站系统访问量的增高,数据库访问压力方面不断的显现而出,所以许多公司在数据库层面采用读写分离技术,也就是一个master,多个slave.master负责数据的实时更新或实时查询,而s ...
- spring实现数据库读写分离
现在大型的电子商务系统,在数据库层面大都采用读写分离技术,就是一个Master数据库,多个Slave数据库.Master库负责数据更新和实时数据查询,Slave库当然负责非实时数据查询.因为在实际的应 ...
- 使用Spring+MySql实现读写分离(二)spring整合多数据库
紧接着上一章,因为现在做的项目还是以spring为主要的容器管理框架,所以写以下spring如何整合多个数据源. 1. 背景 我们一般应用对数据库而言都是“读多写少”,也就说对数据库读取数据的压力比较 ...
随机推荐
- STM32之独立版USB(Host)驱动+MSC+Fatfs移植
源:STM32之独立版USB(Host)驱动+MSC+Fatfs移植 STM32之USB驱动库详解(架构+文件+函数+使用说明+示例程序)
- ansible之template模块
趁着最近在搞ansible,现在学习了一波template模块的用法: 1.使用template模块在jinja2中引用变量,先来目录结构树 [root@master ansible]# tree . ...
- 2017-2018-1 JaWorld 第八周作业
2017-2018-1 JaWorld 第八周作业 团队分工 成员 分工 陈是奇 统计成员工具选择 马平川 类图 王译潇 编码规范 李昱兴 用例图 林臻 状态图 张师瑜 推进工作进展.写博客 UML ...
- luogu p3371 单源最短路径(dijkstral
本来我写的对的 我就多手写了个 ios::sync_with_stdio(false); 我程序里面用了cin 还有scanf 本来想偷偷懒 我就说 我查了半天错 根本找不到的啊... 后来交了几次 ...
- 记第一场atcoder和codeforces 2018-2019 ICPC, NEERC, Northern Eurasia Finals Online Mirror
下午连着两场比赛,爽. 首先是codeforses,我和一位dalao一起打的,结果考炸了,幸亏不计rating.. A Alice the Fan 这个就是记忆化搜索一下预处理,然后直接回答询问好了 ...
- Gym 101246D Fire in the Country(dfs求SG函数)
http://codeforces.com/gym/101246/problem/D 题意: 给定一个无向有环图,大火从1点开始,每个时间点与它相邻的点也将会着火,现在有两个人轮流操作机器人,机器人从 ...
- mysql循环查询树状数据
完整function )) ) CHARSET utf8 BEGIN ) ; ) ; SET str = ''; SET cid =cast(rootId as CHAR); WHILE cid is ...
- Codeforces Round #169 (Div. 2) E. Little Girl and Problem on Trees dfs序+线段树
E. Little Girl and Problem on Trees time limit per test 2 seconds memory limit per test 256 megabyte ...
- JavaScript里Math对象的ceil()、floor()、round()方法的区别
ceil(x) 官方含义:对一个数进行上舍入.理解:ceiling为天花板的意思,意译为向上取整.即取得大于于等于x的最大整数. floor(x) 官方含义:对一个数进行下舍入.理解:floor为地板 ...
- Hardcoded string should use @string resource 警告
在布局文件中,文本的设置使用如下写法时会有警告:Hardcoded string "下一步", should use @string resource <Button and ...