
Coursera, Big Data 4, Machine Learning With Big Data (week 1/2)
Week 1 Machine Learning with Big Data
KNime - GUI based
Spark MLlib - inside Spark
CRISP-DM

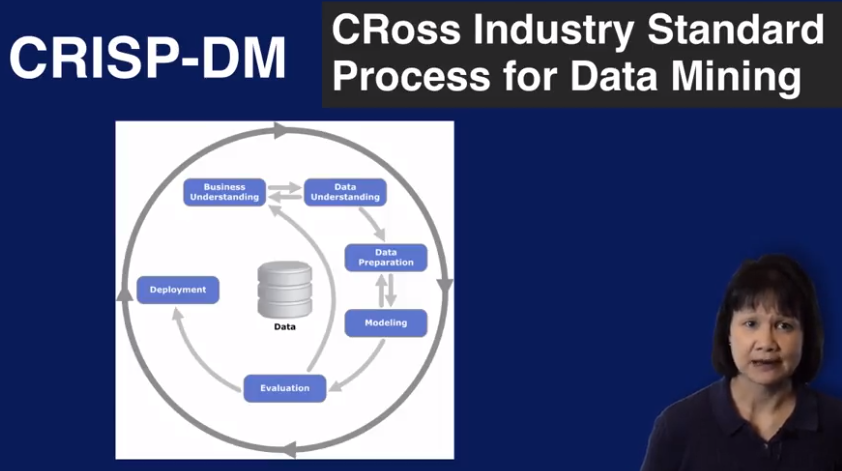
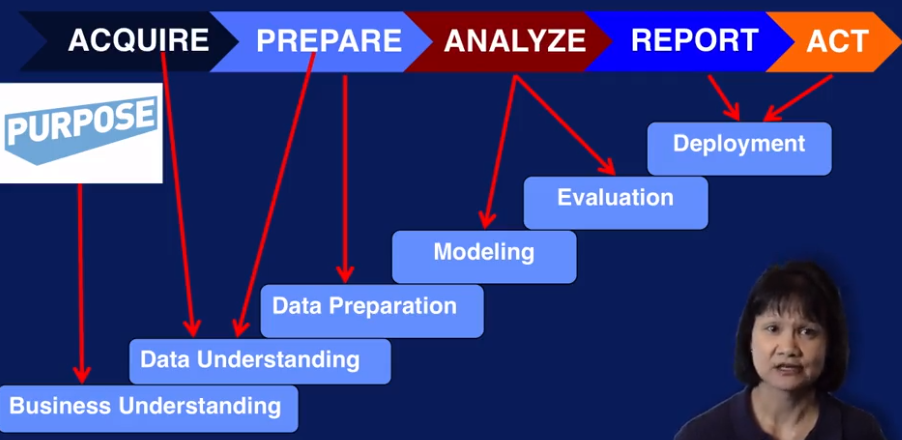
Week 2, Data Exploration
一般有两种方法,summary statistics 和 visualization

Summary statistics (mean 平均数,median 中位数, mode 最常见的数)


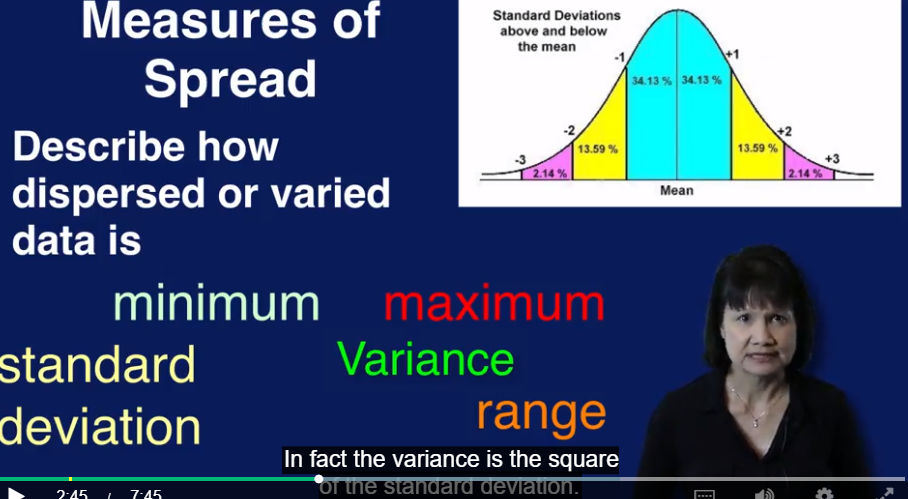
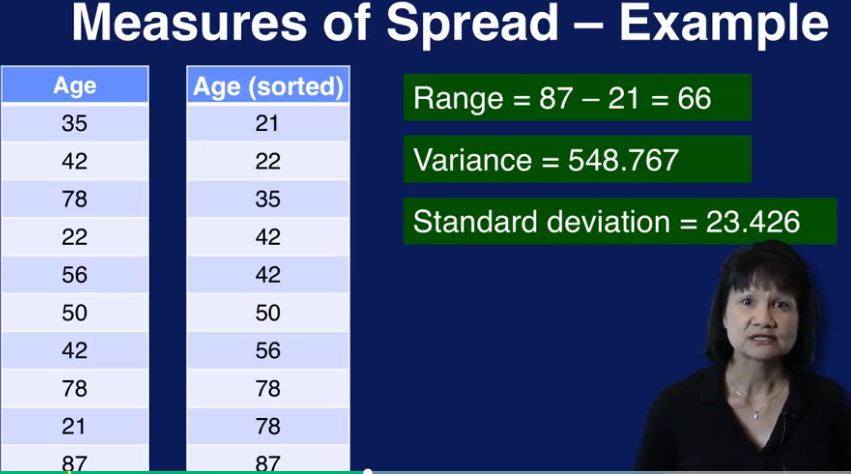
high Kurtosis 预示着有outlier的存在
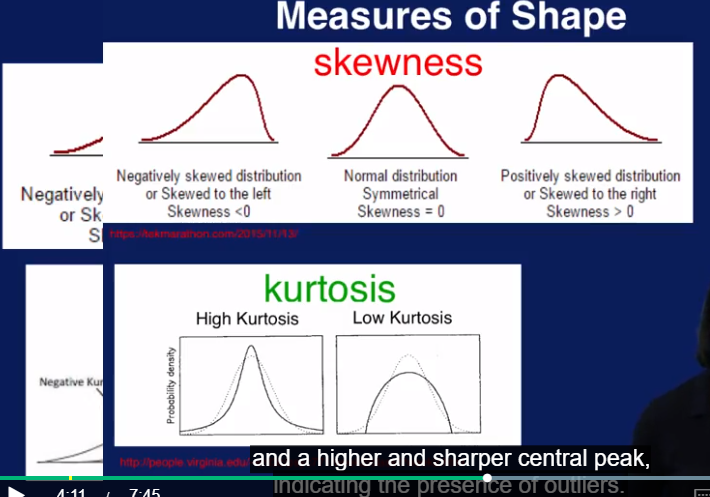
visualization
这里详细讲一下 box plot
下图的 upper quartile 和 lower quartile 分别指的是 75% 和 25% 的点, median 很明显是中位数点,中间柱状部分的数据占了总数据的50%. Upper extreme 和 Lower extreme 分别是90% 和 10% 数据的点,超出部分就是outliers.

Data preparing

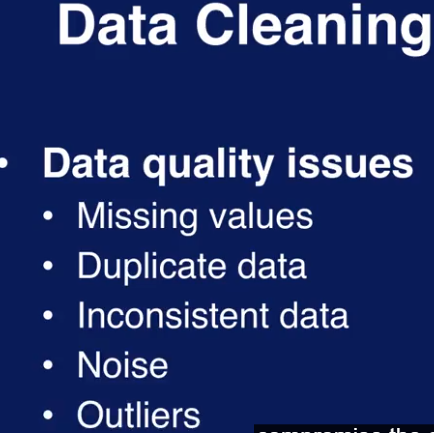
data wrangling 主要是transformation

Coursera, Big Data 4, Machine Learning With Big Data (week 1/2)的更多相关文章
- Coursera, Big Data 4, Machine Learning With Big Data (week 3/4/5)
week 3 Classification KNN :基本思想是 input value 类似,就可能是同一类的 Decision Tree Naive Bayes Week 4 Evaluating ...
- In machine learning, is more data always better than better algorithms?
In machine learning, is more data always better than better algorithms? No. There are times when mor ...
- [Javascript] Classify JSON text data with machine learning in Natural
In this lesson, we will learn how to train a Naive Bayes classifier and a Logistic Regression classi ...
- Coursera 学习笔记|Machine Learning by Standford University - 吴恩达
/ 20220404 Week 1 - 2 / Chapter 1 - Introduction 1.1 Definition Arthur Samuel The field of study tha ...
- [Machine Learning with Python] Data Preparation through Transformation Pipeline
In the former article "Data Preparation by Pandas and Scikit-Learn", we discussed about a ...
- [Machine Learning with Python] Data Preparation by Pandas and Scikit-Learn
In this article, we dicuss some main steps in data preparation. Drop Labels Firstly, we drop labels ...
- 斯坦福大学公开课机器学习:machine learning system design | data for machine learning(数据量很大时,学习算法表现比较好的原理)
下图为四种不同算法应用在不同大小数据量时的表现,可以看出,随着数据量的增大,算法的表现趋于接近.即不管多么糟糕的算法,数据量非常大的时候,算法表现也可以很好. 数据量很大时,学习算法表现比较好的原理: ...
- [Machine Learning with Python] Data Visualization by Matplotlib Library
Before you can plot anything, you need to specify which backend Matplotlib should use. The simplest ...
- Coursera《machine learning》--(14)数据降维
本笔记为Coursera在线课程<Machine Learning>中的数据降维章节的笔记. 十四.降维 (Dimensionality Reduction) 14.1 动机一:数据压缩 ...
随机推荐
- IBM developer:Setting up the Kafka plugin for Ranger
Follow these steps to enable and configure the Kafka plugin for Ranger. Before you begin The default ...
- Vue-cli在webpack内使用雪碧图(响应式)
先执行install cnpm install webpack-spritesmith 文件位置 build\webpack.dev.conf.js 添加内容: const SpritesmithPl ...
- python接口自动化-Cookie_绕过验证码登录
前言 有些登录的接口会有验证码,例如:短信验证码,图形验证码等,这种登录的验证码参数可以从后台获取(或者最直接的可查数据库) 获取不到也没关系,可以通过添加Cookie的方式绕过验证码 前面在“pyt ...
- python学习——读取染色体长度(三、用循环或者函数求总长并获取最长染色体长度)
# 读取fasta # 解析每条序列的长度 chr_len = [10,20,30,40,50] # 求和 # 方法一:通过循环 total_len = 0 #定义total_len的初始长度 for ...
- Django-CRM项目学习(八)-客户关系系统整体实现(待完成!)
注意点:利用stark组件与rbac组件实现客户关系系统 1.需求整理与确认 1.1 客户关系系统整体需求 a
- Elastic Stack-Elasticsearch使用介绍(二)
一.前言 写博客,更要努力写博客! 二.Mapping介绍 Mapping类似于数据库中的表结构的定义:这里我们试想一下表结构定义需要那些: 1.字段和字段类型,在Elasticsearch中 ...
- zoj 3605
链接 [https://vjudge.net/contest/293343#problem/F] 题意 就是有n碗,有一个宝石,知道开始宝石在那个碗下面 进行M次交换,但知道其中的k次,问你最可能在那 ...
- 实现Kubernetes跨集群服务应用的高可用
在Kubernetes 1.3版本,我们希望降低跨集群跨地区服务部署相关的管理和运营难度.本文介绍如何实现此目标. 注意:虽然本文示例使用谷歌容器引擎(GKE)来提供Kubernetes集群,您可以在 ...
- ora-14400:插入的分区关键字未映射到任何分区
参考:https://blog.csdn.net/rubychen410/article/details/5317553 出现该问题是由于: 1.为表设置了根据时间进行分区(PARTITION),而每 ...
- 写一个Python 1、通过select实现的最简单的web框架2、通过wsgiref实现的web框架
#!/usr/bin/env python # -*- coding: utf- -*- import socket import select class MyRequest: "&quo ...