
Hadoop源码篇--Client源码
一。前述
今天起剖析源码,先从Client看起,因为Client在MapReduce的过程中承担了很多重要的角色。
二。MapReduce框架主类
代码如下:
public static void main(String[] args) throws Exception {

        Configuration conf = new Configuration(true);

        //job  作业

        Job  job = Job.getInstance(conf);

         // Create a new Job

//         Job job = Job.getInstance();

         job.setJarByClass(MyWC.class);

         // Specify various job-specific parameters

         job.setJobName("myjob");

//         job.setInputPath(new Path("in"));

//         job.setOutputPath(new Path("out"));

         Path input = new Path("/user/root");

        FileInputFormat.addInputPath(job, input );

         Path output = new Path("/output/wordcount");

         if(output.getFileSystem(conf).exists(output)){

             output.getFileSystem(conf).delete(output,true);

         }

        FileOutputFormat.setOutputPath(job, output );

         job.setMapperClass(MyMapper.class);

         job.setMapOutputKeyClass(Text.class);

         job.setMapOutputValueClass(IntWritable.class);

         job.setReducerClass(MyReducer.class);

         // Submit the job, then poll for progress until the job is complete

         job.waitForCompletion(true);
第一步,先分析Job,可以看见源码中Job实现了public class Job extends JobContextImpl implements JobContext
然后JobContext实现了 MRJobConfig,可以看见其中有很多配置
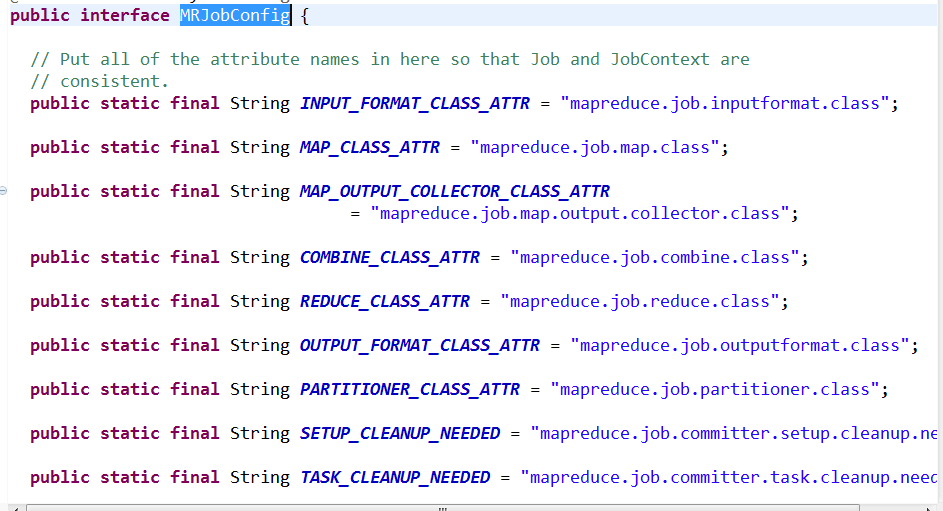
因为job中传的参数为conf,所以这里的配置即对应我们的配置文件中的属性值。
Job job = Job.getInstance(conf);
挑几个重要的看下:
public static final int DEFAULT_MAP_MEMORY_MB = 1024;//默认的Mapper任务内存大小。
第二步,分析提交过程 job.waitForCompletion(true); 追踪源码发现主要实现这个类
JobStatus submitJobInternal(Job job, Cluster cluster)
  throws ClassNotFoundException, InterruptedException, IOException
- Checking the input and output specifications of the job.//检查输入输出路径
- Computing the
InputSplits for the job.//检查切片 - Setup the requisite accounting information for the
DistributedCacheof the job, if necessary. - Copying the job's jar and configuration to the map-reduce system directory on the distributed file-system.
- Submitting the job to the
JobTrackerand optionally monitoring it's status.
在此方法中,中重点看下此方法 int maps = writeSplits(job, submitJobDir);
追踪后具体实现可知
private <T extends InputSplit>

  int writeNewSplits(JobContext job, Path jobSubmitDir) throws IOException,

      InterruptedException, ClassNotFoundException {

    Configuration conf = job.getConfiguration();

    InputFormat<?, ?> input =

      ReflectionUtils.newInstance(job.getInputFormatClass(), conf);

    List<InputSplit> splits = input.getSplits(job);

    T[] array = (T[]) splits.toArray(new InputSplit[splits.size()]);

    // sort the splits into order based on size, so that the biggest

    // go first

    Arrays.sort(array, new SplitComparator());

    JobSplitWriter.createSplitFiles(jobSubmitDir, conf,

        jobSubmitDir.getFileSystem(conf), array);

    return array.length;

  }
追踪job.getInputFormatClass()可以发现如下代码:

public Class<? extends InputFormat<?,?>> getInputFormatClass()

     throws ClassNotFoundException {

    return (Class<? extends InputFormat<?,?>>)

      conf.getClass(INPUT_FORMAT_CLASS_ATTR, TextInputFormat.class);
//根据用户配置文件首先取用,如果没有被取用则使用默认输入格式TextInputFormat

  }
所以可得知用户的默认输入类是TextInputformat类并且继承关系如下:
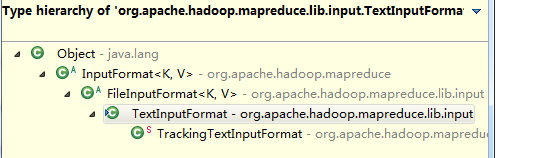
TextInputforMat-->FileinputFormat-->InputFormat
追踪 List<InputSplit> splits = input.getSplits(job);可以得到如下源码:
最为重要的一个源码!!!!!!!!!!!
public List<InputSplit> getSplits(JobContext job) throws IOException {

    Stopwatch sw = new Stopwatch().start();

    long minSize = Math.max(getFormatMinSplitSize(), getMinSplitSize(job));如果用户设置则取用户,没有是1

    long maxSize = getMaxSplitSize(job);//如果用户设置则取用户,没有取最大值

    // generate splits

    List<InputSplit> splits = new ArrayList<InputSplit>();

    List<FileStatus> files = listStatus(job);

    for (FileStatus file: files) {

      Path path = file.getPath();//取输入文件的大小和路径

      long length = file.getLen();

      if (length != 0) {

        BlockLocation[] blkLocations;

        if (file instanceof LocatedFileStatus) {

          blkLocations = ((LocatedFileStatus) file).getBlockLocations();

        } else {

          FileSystem fs = path.getFileSystem(job.getConfiguration());

          blkLocations = fs.getFileBlockLocations(file, 0, length);//获得所有块的位置。

        }

        if (isSplitable(job, path)) {

          long blockSize = file.getBlockSize();

          long splitSize = computeSplitSize(blockSize, minSize, maxSize);//获得切片大小

          long bytesRemaining = length;

          while (((double) bytesRemaining)/splitSize > SPLIT_SLOP) {

            int blkIndex = getBlockIndex(blkLocations, length-bytesRemaining);//这一块传参传的是切块的偏移量,返回这个块的索引

            splits.add(makeSplit(path, length-bytesRemaining, splitSize,

                        blkLocations[blkIndex].getHosts(),//根据当前块的索引号取出来块的位置包括副本的位置 然后传递给切片,然后切片知道往哪运算。即往块的位置信息计算

                        blkLocations[blkIndex].getCachedHosts()));

            bytesRemaining -= splitSize;

          }

          if (bytesRemaining != 0) {

            int blkIndex = getBlockIndex(blkLocations, length-bytesRemaining);

            splits.add(makeSplit(path, length-bytesRemaining, bytesRemaining,

                       blkLocations[blkIndex].getHosts(),

                       blkLocations[blkIndex].getCachedHosts()));

          }

        } else { // not splitable

          splits.add(makeSplit(path, 0, length, blkLocations[0].getHosts(),

                      blkLocations[0].getCachedHosts()));

        }

      } else {

        //Create empty hosts array for zero length files

        splits.add(makeSplit(path, 0, length, new String[0]));

      }

    }

    // Save the number of input files for metrics/loadgen

    job.getConfiguration().setLong(NUM_INPUT_FILES, files.size());

    sw.stop();

    if (LOG.isDebugEnabled()) {

      LOG.debug("Total # of splits generated by getSplits: " + splits.size()

          + ", TimeTaken: " + sw.elapsedMillis());

    }

    return splits;

  }
1.long splitSize = computeSplitSize(blockSize, minSize, maxSize);追踪源码发现
protected long computeSplitSize(long blockSize, long minSize, long maxSize) {

    return Math.max(minSize, Math.min(maxSize, blockSize));

  }
切片大小默认是块的大小!!!!
假如让切片大小 < 块的大小则更改配置的最大值MaxSize,让其小于blocksize
假如让切片大小 > 块的大小则更改配置的最小值MinSize,让其大于blocksize
通过FileInputFormat.setMinInputSplitSize即可。
2. int blkIndex = getBlockIndex(blkLocations, length-bytesRemaining) 追踪源码发现
 protected int getBlockIndex(BlockLocation[] blkLocations,

                              long offset) {

    for (int i = 0 ; i < blkLocations.length; i++) {

      // is the offset inside this block?

      if ((blkLocations[i].getOffset() <= offset) &&

          (offset < blkLocations[i].getOffset() + blkLocations[i].getLength())){//切片要大于>=块的起始量,小于一个块的末尾量。

        return i;//返回这个块

      }

    }

    BlockLocation last = blkLocations[blkLocations.length -1];

    long fileLength = last.getOffset() + last.getLength() -1;

    throw new IllegalArgumentException("Offset " + offset +

                                       " is outside of file (0.." +

                                       fileLength + ")");

  }
3. splits.add(makeSplit(path, length-bytesRemaining, splitSize, blkLocations[blkIndex].getHosts()
创建切片的时候,一个切片对应一个mapperr任务,所以创建切片的四个位置(path,0,10,host)
根据host可知mapper任务的计算位置,则对应计算向数据移动!!!!块是逻辑的,并没有真正切割数据。!!
4.上述getSplits方法最终得到一个切片的清单,清单的数目就是mapper的数量!!即开始方法的入口 int maps = writeSplits(job, submitJobDir);返回值。
5.计算向数据移动时会拉取只属于自己的文件。
持续更新中。。。。,欢迎大家关注我的公众号LHWorld.
Hadoop源码篇--Client源码的更多相关文章
- MyBatis 源码篇-MyBatis-Spring 剖析
本章通过分析 mybatis-spring-x.x.x.jar Jar 包中的源码,了解 MyBatis 是如何与 Spring 进行集成的. Spring 配置文件 MyBatis 与 Spring ...
- MyBatis 源码篇-Transaction
本章简单介绍一下 MyBatis 的事务模块,这块内容比较简单,主要为后面介绍 mybatis-spring-1.**.jar(MyBatis 与 Spring 集成)中的事务模块做准备. 类图结构 ...
- MyBatis 源码篇-DataSource
本章介绍 MyBatis 提供的数据源模块,为后面与 Spring 集成做铺垫,从以下三点出发: 描述 MyBatis 数据源模块的类图结构: MyBatis 是如何集成第三方数据源组件的: Pool ...
- MyBatis 源码篇-插件模块
本章主要描述 MyBatis 插件模块的原理,从以下两点出发: MyBatis 是如何加载插件配置的? MyBatis 是如何实现用户使用自定义拦截器对 SQL 语句执行过程中的某一点进行拦截的? 示 ...
- MyBatis 源码篇-日志模块2
上一章的案例,配置日志级别为 debug,执行一个简单的查询操作,会将 JDBC 操作打印出来.本章通过 MyBatis 日志部分源码分析它是如何实现日志打印的. 在 MyBatis 的日志模块中有一 ...
- MyBatis 源码篇-日志模块1
在 Java 开发中常用的日志框架有 Log4j.Log4j2.Apache Common Log.java.util.logging.slf4j 等,这些日志框架对外提供的接口各不相同.本章详细描述 ...
- MyBatis 源码篇-资源加载
本章主要描述 MyBatis 资源加载模块中的 ClassLoaderWrapper 类和 Java 加载配置文件的三种方式. ClassLoaderWrapper 上一章的案例,使用 org.apa ...
- MyBatis 源码篇-SQL 执行的流程
本章通过一个简单的例子,来了解 MyBatis 执行一条 SQL 语句的大致过程是怎样的. 案例代码如下所示: public class MybatisTest { @Test public void ...
- MyBatis 源码篇-整体架构
MyBatis 的整体架构分为三层, 分别是基础支持层.核心处理层和接口层,如下图所示. 基础支持层 反射模块 该模块对 Java 原生的反射进行了良好的封装,提供了更加简洁易用的 API ,方便上层 ...
随机推荐
- FiddlerCoreAPI开发(一)源码分析
1.前言 前一段时间想利用fiddlercore截取本地HTTPS的流量做一些分析,按照样例代码的注释学习了一下,没搞清楚怎么实现,后来又在网上查了些资料,对HTTPS的处理提及很少,都没有解决我的问 ...
- 用js解析XML文件,字符串一些心得
解析XML文件遇到的问题 今天秦博士叫我解析一下XML文件,将里面的所有的X坐标Y坐标放在一个数组里面然后写在文档里让他进行算法比对,大家都知道了啦,解析XML文件获取里面的坐标数据什么的,当然是用前 ...
- JSONArray - JSONObject - 遍历 \ 判断object空否
public static void main(String[] args) { String str = "[{name:'a',value:'aa'},{name:'b',value:' ...
- Map Task内部实现分析
上篇我刚刚学习完.Spilt的过程,还算比較简单的了,接下来学习的就是Map操作的过程了,Map和Reduce一样.是整个MapReduce的重要内容,所以.这一篇,我会好好的讲讲里面的内部实现过程. ...
- 为PHP摇旗呐喊!
如今市场上的电子商务软件基本上可归结为两大阵营.即PHP阵营和Java阵营.但对接触电子商务不久的用户来说.看到的往往仅仅是它们的表相,仅仅是明显的价格差异.却非常难看出它们之间的实际差异.事实上,P ...
- 三.RabbitMQ之异步消息队列(Work Queue)
上一篇文章简要介绍了RabbitMQ的基本知识点,并且写了一个简单的发送和接收消息的demo.这一篇文章继续介绍关于Work Queue(工作队列)方面的知识点,用于实现多个工作进程的分发式任务. 一 ...
- windows 下使用VMware Workstation Pro 工具,ubuntu创建虚拟机
本文记录windows 下使用VMware Workstation Pro 工具,ubuntu创建虚拟机 的步骤 第一步 [文件] --- [新建虚拟机] 第二步 弹出的新建虚拟机向导对话框 标准 ...
- 基于python的web应用开发-添加关注者
社交web允许用户之间相互联系. 例如: 关注者.好友.联系人.联络人或伙伴. 记录两个用户之间的定向联系,在数据库查询中也要使用这种联系. 一.论数据库关系 一对多关系 数据库使用关系建立记录之间的 ...
- 深入理解计算机系统_3e 第六章家庭作业 CS:APP3e chapter 6 homework
6.22 假设磁道沿半径均匀分布,即总磁道数和(1-x)r成正比,设磁道数为(1-x)rk: 由题单个磁道的位数和周长成正比,即和半径xr成正比,设单个磁道的位数为xrz: 其中r.k.z均为常数. ...
- Web服务器、应用服务器、Web容器、反向代理服务器区别与联系
作者: 帅虫哥 出处:www.cnblogs.com/vipyoumay/p/7455431.html(点击尾部阅读原文前往) 我们知道,不同肤色的人外貌差别很大,而双胞胎的辨识很难.有意思的是Web ...