
scrapy中对于item的把控
其实很简单,就是想要存储的位置发生改变。直接看例子,然后触类旁通。
以大众点评 评论的内容为例 ,位置:http://www.dianping.com/shop/77489519/review_more?pageno=1
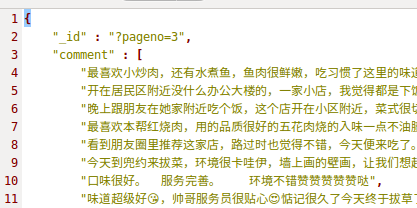
数据存储形式由A 变成B
A:
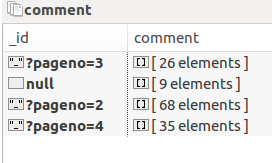
展开的话这样子:
B:
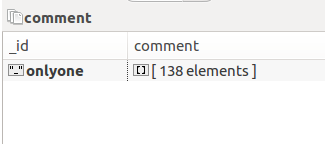
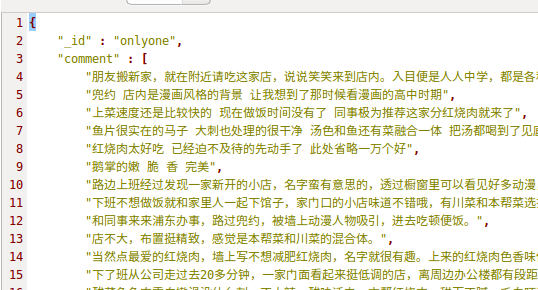
本质上看,就是多个相同类型的item可以合并,不需要那么多,分别来看下各自的代码:
A:
class GengduopinglunSpider(scrapy.Spider):

    name = 'gengduopinglun'

    start_urls = ['http://www.dianping.com/shop/77489519/review_more?pageno=1']

    def parse(self, response):

        item=PinglunItem()

        comment = item['comment'] if "comment" in item else []

        for i in response.xpath('//div[@class="content"]'):

            for j in i.xpath('.//div[@class="J_brief-cont"]/text()').extract():

                comment.append(j.strip())

        item['comment']=comment

        next_page = response.xpath(

            '//div[@class="Pages"]/div[@class="Pages"]/a[@class="NextPage"]/@href').extract_first()

        item['_id']=next_page

        # item['_id']='onlyone'

        if next_page != None:

            next_page = response.urljoin(next_page)

            # yield Request(next_page, callback=self.shop_comment,meta={'item': item})

            yield Request(next_page, callback=self.parse,)

        yield item
B:
class GengduopinglunSpider(scrapy.Spider):

    name = 'gengduopinglun'

    start_urls = ['http://www.dianping.com/shop/77489519/review_more?pageno=1']

    def parse(self, response):

        item=PinglunItem()

        comment = item['comment'] if "comment" in item else []

        for i in response.xpath('//div[@class="content"]'):

            for j in i.xpath('.//div[@class="J_brief-cont"]/text()').extract():

                comment.append(j.strip())

        item['comment']=comment

        next_page = response.xpath(

            '//div[@class="Pages"]/div[@class="Pages"]/a[@class="NextPage"]/@href').extract_first()

        # item['_id']=next_page

        item['_id']='onlyone'

        if next_page != None:

            next_page = response.urljoin(next_page)

            yield Request(next_page, callback=self.shop_comment,meta={'item': item})

            # yield Request(next_page, callback=self.parse,)

        # yield item

    def shop_comment(self, response):

        item = response.meta['item']

        comment = item['comment'] if "comment" in item else []

        for i in response.xpath('//div[@class="content"]'):

            for j in i.xpath('.//div[@class="J_brief-cont"]/text()').extract():

                comment.append(j.strip())

        item['comment']=comment

        next_page = response.xpath(

            '//div[@class="Pages"]/div[@class="Pages"]/a[@class="NextPage"]/@href').extract_first()

        if next_page != None:

            next_page = response.urljoin(next_page)

            yield Request(next_page, callback=self.shop_comment,meta={'item': item})

        yield item
B里面是有重复代码的,这个无关紧要,只是演示,注意看两个yield 的区别
以上只是演示scrapy中yield的用法,用来控制item,其余pipline,setting未展示.
scrapy中对于item的把控的更多相关文章
- Scrapy中的item是什么
这两天看Scrapy,看到item这个东西,觉得有点抽象,查了一下,有点明白了. Item 是保存爬取到的数据的容器:其使用方法和python字典类似, 并且提供了额外保护机制来避免拼写错误导致的未定 ...
- 关于ListView中item与子控件抢夺焦点的解决方法
1.在开发中,listview可以说是我们使用最频繁的控件之一了,但是关于listview的各种问题也是很多.当我们使用自定义布局的Listview的时候,如果在item的布局文件里面存在Button ...
- 手把手教你进行Scrapy中item类的实例化操作
接下来我们将在爬虫主体文件中对Item的值进行填充. 1.首先在爬虫主体文件中将Item模块导入进来,如下图所示. 2.第一步的意思是说将items.py中的ArticleItem类导入到爬虫主体文件 ...
- 第十七节:Scrapy爬虫框架之item.py文件以及spider中使用item
Scrapy原理图: item位于原理图的最左边 item.py文件是报存爬取数据的容器,他使用的方法和字典很相似,但是相比字典item多了额外的保护机制,可以避免拼写错误或者定义错误. 1.创建it ...
- Scrapy中使用cookie免于验证登录和模拟登录
Scrapy中使用cookie免于验证登录和模拟登录 引言 python爬虫我认为最困难的问题一个是ip代理,另外一个就是模拟登录了,更操蛋的就是模拟登录了之后还有验证码,真的是不让人省心,不过既然有 ...
- scrapy中的request
scrapy中的request 初始化参数 class scrapy.http.Request( url [ , callback, method='GET', headers, body, cook ...
- [转]scrapy中的request.meta
作者:知乎用户链接:https://www.zhihu.com/question/54773510/answer/146971644 meta属性是字典,字典格式即{'key':'value'},字典 ...
- 论Scrapy中的数据持久化
引入 Scrapy的数据持久化,主要包括存储到数据库.文件以及内置数据存储. 那我们今天就来讲讲如何把Scrapy中的数据存储到数据库和文件当中. 终端指令存储 保证爬虫文件的parse方法中有可迭代 ...
- 使用scrapy中xpath选择器的一个坑点
情景如下: 一个网页下有一个ul,这个ur下有125个li标签,每个li标签下有我们想要的 url 字段(每个 url 是唯一的)和 price 字段,我们现在要访问每个li下的url并在生成的请求中 ...
随机推荐
- linux网络编程框架
OSI七层模型与TCP四层模型 OSI七层模型与TCP四层模型 BS和CS服务器架构 (1)CS架构介绍(client server,客户端服务器架构)(2)BS架构介绍(broswer server ...
- html5页面头部
<base href="/bulid/"/> <meta charset="UTF-8"/> <meta http-equiv=& ...
- MESS-配置
Author:KillerLegend From:http://www.cnblogs.com/killerlegend/p/3824989.html Date:2014.7.4 Part A 第一部 ...
- CF&&CC百套计划3 Codeforces Round #204 (Div. 1) D. Jeff and Removing Periods
http://codeforces.com/problemset/problem/351/D 题意: n个数的一个序列,m个操作 给出操作区间[l,r], 首先可以删除下标为等差数列且数值相等的一些数 ...
- div内容超出后自动显示滚动条
一. <div style=" overflow:scroll; width:400px; height:400px;”></div> 记住宽和高一定要设置噢,否则不 ...
- Java并发编程原理与实战十九:AQS 剖析
一.引言在JDK1.5之前,一般是靠synchronized关键字来实现线程对共享变量的互斥访问.synchronized是在字节码上加指令,依赖于底层操作系统的Mutex Lock实现.而从JDK1 ...
- 【leetcode 简单】 第八十七题 两整数之和
不使用运算符 + 和-,计算两整数a .b之和. 示例: 若 a = 1 ,b = 2,返回 3. class Solution: def getSum(self, a, b): "&quo ...
- Mysql 关闭自动commit
更多内容推荐微信公众号,欢迎关注: 1. 会话级关闭自动提交 mysql> set autocommit=off; Query OK, 0 rows affected (0.00 sec) my ...
- [Openwrt 扩展下篇] Openwrt搭建私有云Owncloud 9
网上很多资料讲用Linux打造owncloud构建私有云 ,花了些时间研究了下,我将之前的需求打造成了Openwrt下的Owncloud 9.其实网上还有Seafile.大家对比来看下知乎的评论,其实 ...
- 【多视图几何】TUM 课程 第4章 同名点匹配
课程的 YouTube 地址为:https://www.youtube.com/playlist?list=PLTBdjV_4f-EJn6udZ34tht9EVIW7lbeo4 .视频评论区可以找到课 ...