
XiangBai——【AAAI2017】TextBoxes_A Fast Text Detector with a Single Deep Neural Network
XiangBai——【AAAI2017】TextBoxes:A Fast Text Detector with a Single Deep Neural Network
目录
- 作者和相关链接
- 方法概括
- 创新点和贡献
- 方法细节
- 实验结果
- 总结与收获点
作者和相关链接
- 作者
方法概括
文章核心:
- 改进版的SSD用来解决文字检测问题
端到端识别的pipeline:
- Step 1: 图像输入到修改版SSD网络中 + 非极大值抑制(NMS)→ 输出候选检测结果
- Step 2: 候选检测结果 + CRNN进行单词识别 → 新的检测结果 + 识别结果
方法的性能
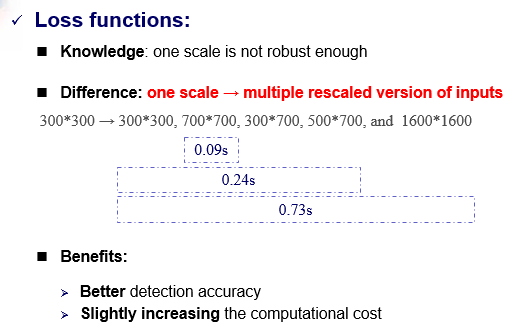
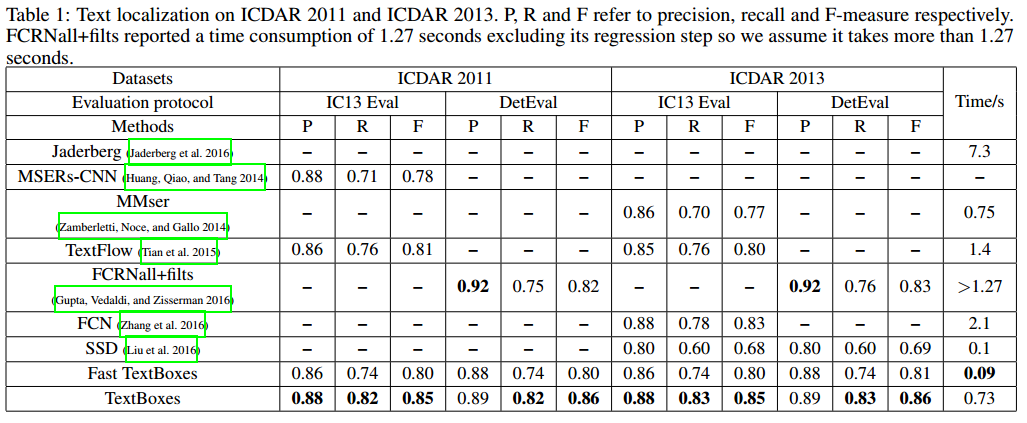
- 多尺度版本-定位:ICDAR2011-0.85(f),ICDAR2013-0.85(f),0.73s/per image
- 单尺度版本-定位:ICDAR2011-0.80(f),ICDAR2013-0.80(f),0.09s/per image
改进的SSD的地方:
- default box的长宽比进行修改(长条形),使其更适合文字检测(单词)
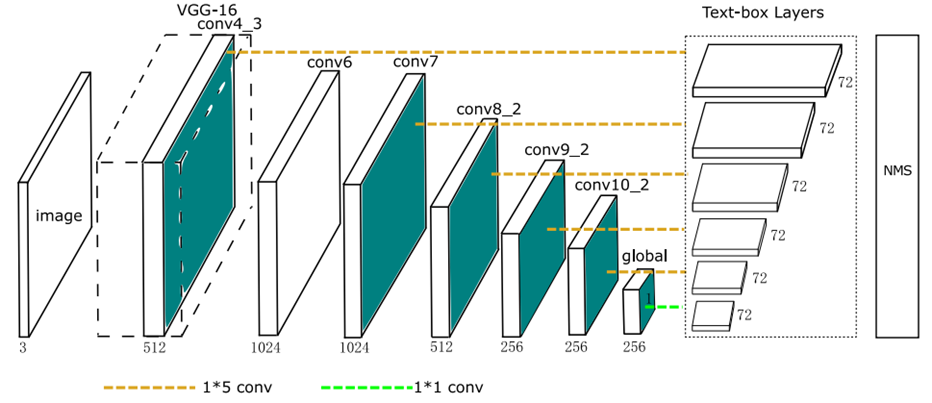
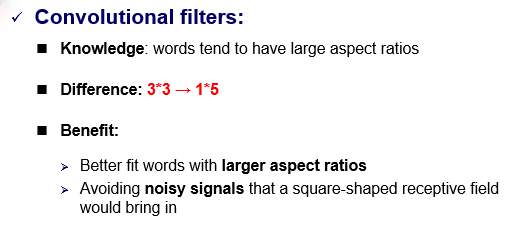
- 作为classifier的卷积滤波器大小从3*3变成1*5,更适合文字检测
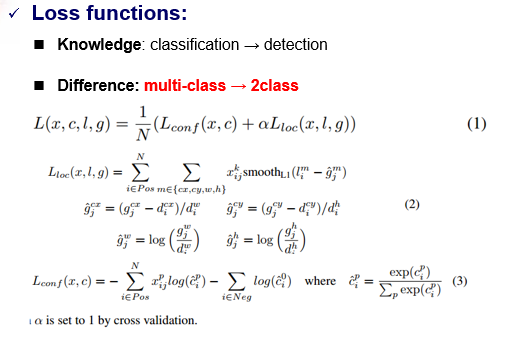
- SSD原来为多类检测问题,现在转为单类检测问题
- 从输入图像为单尺度变为多尺度
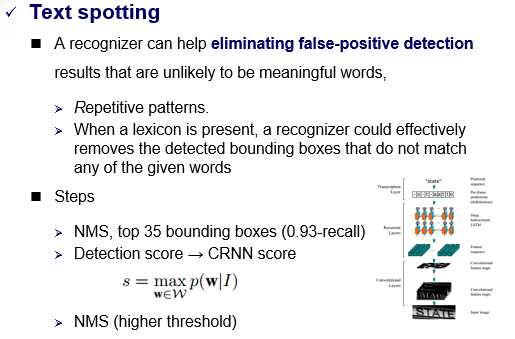
- 利用识别来调整检测的结果(text spotting)
创新点和贡献
创新点
- 把SSD进行修改,使其适用于文字检测(SSD本身对小目标识别不鲁棒)
贡献
- 提出一个端到端可训练的非常简洁的文字检测框架(SSD本身是single stage的,不像普通方法需要有多步骤组成)
- 提出一个完整的端到端识别的文字检测+识别框架
- 实验方法结果好,速度快
方法细节
相关背景——文字识别的任务
- 文字检测
- 文字/单词识别
- 端到端文字识别 = 文字 + 识别
- text spotting:和文字检测不同的是,可以利用带字典的文字识别进行调整检测结果,最终是用文字检测的结果进行评判
相关背景——SSD
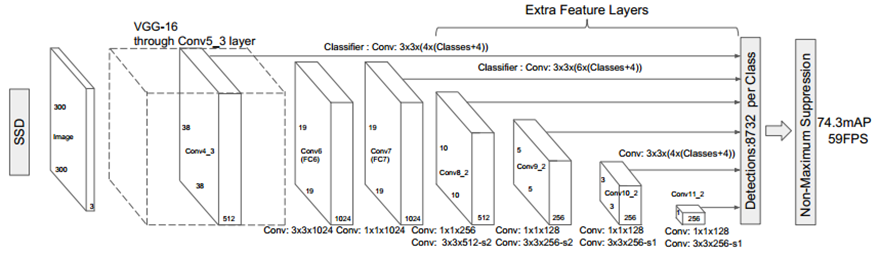
- SSD的网络结构
- SSD的default box
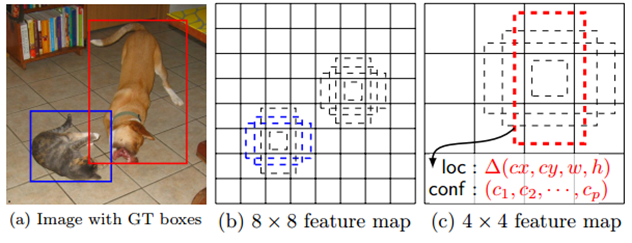
Fig. 1: SSD framework. (a) SSD only needs an input image and ground truth boxes for each object during training. In a convolutional fashion, we evaluate a small set (e.g. 4) of default boxes of different aspect ratios at each location in several feature maps with different scales (e.g. 8 × 8 and 4 × 4 in (b) and (c)). For each default box, we predict both the shape offsets and the confidences for all object categories ((c1; c2; · · · ; cp)). At training time, we first match these default boxes to the ground truth boxes. For example, we have matched two default boxes with the cat and one with the dog, which are treated as positives and the rest as negatives. The model loss is a weighted sum between localization loss (e.g. Smooth L1 [6]) and confidence loss (e.g. Softmax).
相关背景——CRNN
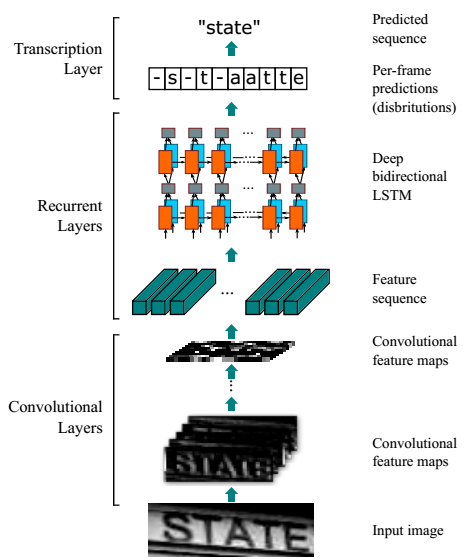
- CRNN的网络结构
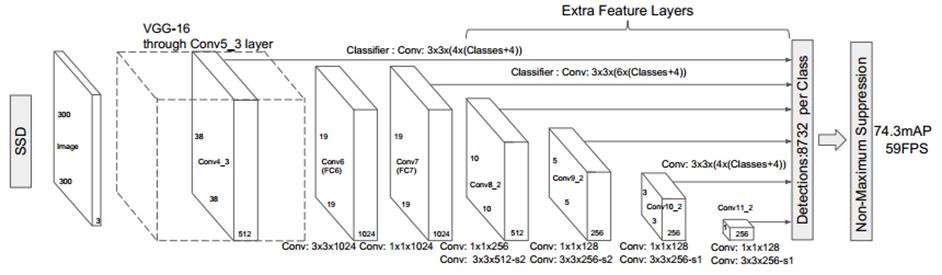
TextBoxes与SSD网络结构对比
- TextBoxes网络结构
- SSD 网络结构
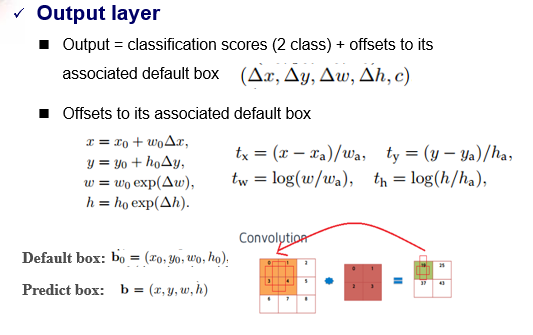
Text-box layers的输出
(与SSD一样)
TextBoxes与SSD不同的修改细节
default box长宽比
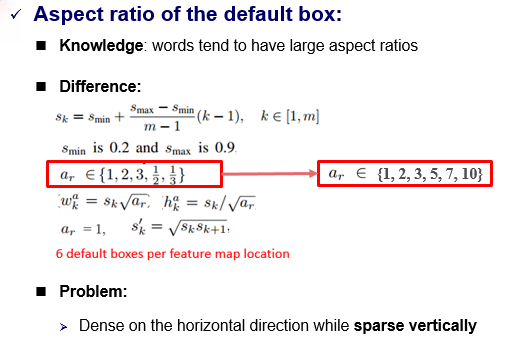

(右边图)Figure 2: Illustration of default boxes for a 4*4 grid. For better visualization, only a column of default boxes whose aspect ratios 1 and 5 are plotted. The rest of the aspect ratios are 2,3,7 and 10, which are placed similarly. The black (aspect ratio: 5) and blue (ar: 1) default boxes are centered in their cells. The green (ar: 5) and red (ar: 1) boxes have the same aspect ratios and a vertical offset(half of the height of the cell) to the grid center respectively
卷积滤波器大小
损失函数
多尺度输入
TextBoxes+CRNN进行识别
实验结果
定位
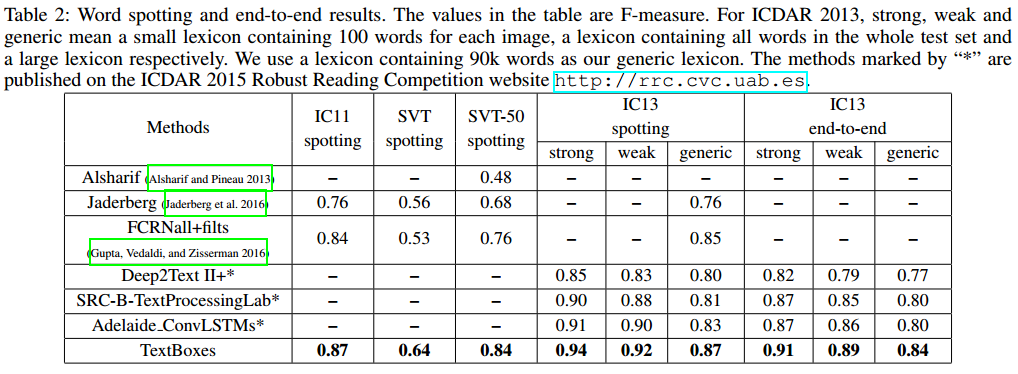
text spotting和端到端识别
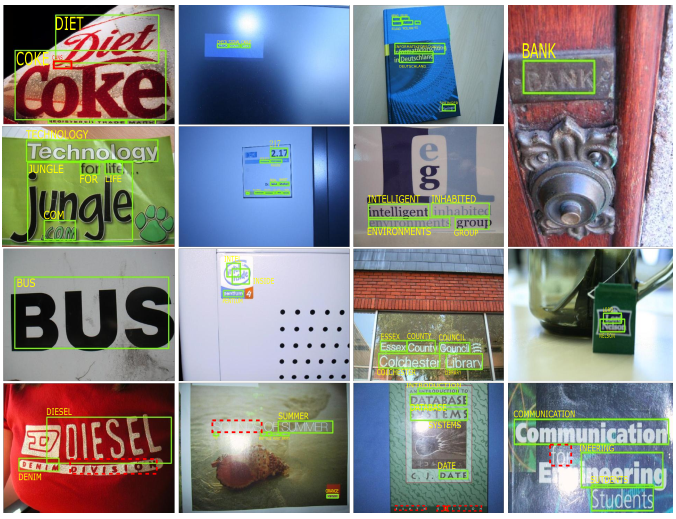
效果展示
总结与收获点
- 原始的SSD是无法直接用在文字上的,需要进行许多修改才能达到比较好的效果,这一点作者在实验中也证明了
- 现在越来越多用Faster r-cnn,ssd,yolo,这类一般的目标检测方法进行修改后用在特定的目标检测上(例如文字,行人),这些方法不但速度快,而且鲁棒性也高,很重要一点,越来越倾向于端到端训练,这是因为single stage和传统的step-wise的方法相比有很多优势,例如,总体训练简单,没有stage衔接上的性能损耗,没有逐步的误差积累等等;
XiangBai——【AAAI2017】TextBoxes_A Fast Text Detector with a Single Deep Neural Network的更多相关文章
- 论文阅读(XiangBai——【AAAI2017】TextBoxes_A Fast Text Detector with a Single Deep Neural Network)
XiangBai——[AAAI2017]TextBoxes:A Fast Text Detector with a Single Deep Neural Network 目录 作者和相关链接 方法概括 ...
- XiangBai——【CVPR2018】Multi-Oriented Scene Text Detection via Corner Localization and Region Segmentation
XiangBai——[CVPR2018]Multi-Oriented Scene Text Detection via Corner Localization and Region Segmentat ...
- 论文阅读(XiangBai——【CVPR2017】Detecting Oriented Text in Natural Images by Linking Segments)
XiangBai——[CVPR2017]Detecting Oriented Text in Natural Images by link Segments 目录 作者和相关链接 方法概括 方法细节 ...
- 【RS】Automatic recommendation technology for learning resources with convolutional neural network - 基于卷积神经网络的学习资源自动推荐技术
[论文标题]Automatic recommendation technology for learning resources with convolutional neural network ( ...
- 论文阅读(XiangBai——【PAMI2018】ASTER_An Attentional Scene Text Recognizer with Flexible Rectification )
目录 XiangBai--[PAMI2018]ASTER_An Attentional Scene Text Recognizer with Flexible Rectification 作者和论文 ...
- 论文阅读(Lukas Neuman——【ICDAR2015】Efficient Scene Text Localization and Recognition with Local Character Refinement)
Lukas Neuman--[ICDAR2015]Efficient Scene Text Localization and Recognition with Local Character Refi ...
- 论文阅读(Weilin Huang——【AAAI2016】Reading Scene Text in Deep Convolutional Sequences)
Weilin Huang--[AAAI2016]Reading Scene Text in Deep Convolutional Sequences 目录 作者和相关链接 方法概括 创新点和贡献 方法 ...
- 【论文笔记】Malware Detection with Deep Neural Network Using Process Behavior
[论文笔记]Malware Detection with Deep Neural Network Using Process Behavior 论文基本信息 会议: IEEE(2016 IEEE 40 ...
- 论文阅读笔记(三)【AAAI2017】:Learning Heterogeneous Dictionary Pair with Feature Projection Matrix for Pedestrian Video Retrieval via Single Query Image
Introduction (1)IVPR问题: 根据一张图片从视频中识别出行人的方法称为 image to video person re-id(IVPR) 应用: ① 通过嫌犯照片,从视频中识别出嫌 ...
随机推荐
- @寒冬winter 大神的css作业问题
块级元素 ①总是在新行上开始: ②高度,行高以及外边距和内边距都可控制: ③宽度缺省是它的容器的100%,除非设定一个宽度. ④它可以容纳内联元素和其他块元素 行内级元素 ①和其他元素都在一行 ...
- 为什么angularjs使用ui-router时要使用html5Mode?
为什么我们要在使用angular ui-router时要使用html5Mode=true这个呢? 在angular中,你在访问链接时,可能访问的链接为"#/link". 如果你设置 ...
- GO语言练习:反射
列举几个反射的例子:1)简单类型反射,2)复杂类型反射,3)对反射回来的数据的可修改属性 1.简单类型反射 1.1)代码 package main import ( "fmt" & ...
- Graph Cuts初步理解
一些知识点的初步理解_8(Graph Cuts,ing...) Graph cuts是一种十分有用和流行的能量优化算法,在计算机视觉领域普遍应用于前背景分割(Image segmentation).立 ...
- linux内核分析作业:操作系统是如何工作的进行:完成一个简单的时间片轮转多道程序内核代码
计算机如何工作 三个法宝:存储程序计算机.函数调用堆栈.中断机制. 堆栈 函数调用框架 传递参数 保存返回地址 提供局部变量空间 堆栈相关的寄存器 Esp 堆栈指针 (stack pointer) ...
- 一般企业网站,电商可以完全可以水平拓展的lanmp系统架构
本来不打算把所有的架构方案和基础技术写出,毕竟是吃饭的家伙事,拿这套东西去面试完全可以对付只做过中小网站的经验的开发面试人员,但是我也是从别人的博客和文章学习和实践出来的 如果你没有基础的linux一 ...
- Run P4 without P4factory - A Simple Example In Tutorials.
前言 本文是我运行P4社区于Github开源教程Tutorials中的P4 SIGCOMM 2015 Tutorial一些实战小结,Github链接: Github. 测试的例子:P4 SIGCOMM ...
- sonarqube插件开发(一) 环境搭建
1. 下载Docker容器 # 最新版本镜像 docker pull sonarqube # 长期支持版镜像 docker pull sonarqube:lts 2. 将已有的插件导出(使用docke ...
- apache2.2 做后端,增加真实ip到日志中
apache2.2使用mod_remoteip模块 一.安装 wget https://github.com/ttkzw/mod_remoteip-httpd22/raw/master/mod_rem ...
- FireDAC 连接SQL Server一些要注意的地方
TFDConnection: FetchOptions.Mode 设置为fmAll, 返回全部结果, 否则默认只返回前50条, 效果与open以后再执行FetchAll一样 Specifies how ...