
Unalignable boolean Series provided as indexer (index of the boolean Series and of the indexed object do not match
最近在用python做数据挖掘,在聚类的时候遇到了一个非常恶心的问题。话不多说,直接上代码:
 from sklearn.cluster import KMeans

 from sklearn.decomposition import PCA

 import matplotlib.pyplot as plt

 #kmeans算法

 df1=df23

 kmeans = KMeans(n_clusters=5, random_state=10).fit(df1)

 #贴上每个样本对应的簇类别标签

 df1['level']=kmeans.labels_

 #df1.to_csv('new_df.csv')

 df2=df1.groupby('level',as_index=False)['level'].agg({'num': np.size})

 print(df2.head())

 #将用于聚类的数据的特征的维度降至2维

 pca = PCA(n_components=2)

 new_pca = pd.DataFrame(pca.fit_transform(df1))

 print(new_pca.head())

 #可视化

 d = new_pca[df1['level'] == 0]

 plt.plot(d[0], d[1], 'gv')

 d = new_pca[df1['level'] == 1]

 plt.plot(d[0], d[1], 'ko')

 d = new_pca[df1['level'] == 2]

 plt.plot(d[0], d[1], 'b*')

 d = new_pca[df1['level'] == 3]

 plt.plot(d[0], d[1], 'y+')

 d = new_pca[df1['level'] == 4]

 plt.plot(d[0], d[1], 'c.')

 plt.title('the result of polymerization')

 plt.show()
错误如下:
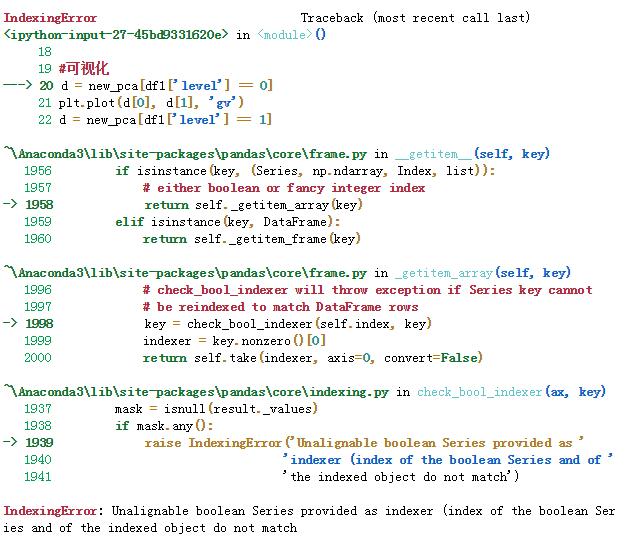
网上找了好久都没找到解决方法,明明之前成功过的。于是我查看了df23数据,发现它是这样的:
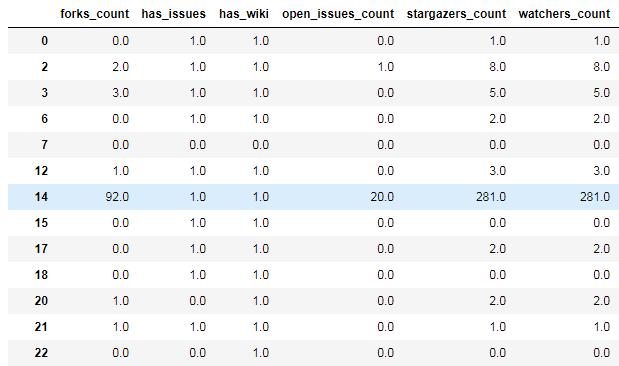
与之前成功的dataframe的唯一差别就是索引!!!重要的事情说三遍!!!索引!!!索引!!!于是乎,我去找怎么重置索引的方法,见代码:
 df24=df23[["forks_count","has_issues","has_wiki","open_issues_count","stargazers_count","watchers_count","created_pushed_time","created_updated_time"]]

 df24=df24.reset_index()

 df24=df24[["forks_count","has_issues","has_wiki","open_issues_count","stargazers_count","watchers_count","created_pushed_time","created_updated_time"]]
然后聚类就成功了。。。心累。。。。
Unalignable boolean Series provided as indexer (index of the boolean Series and of the indexed object do not match的更多相关文章
- pandas之Seris和DataFrame
pandas是一个强大的python工具包,提供了大量处理数据的函数和方法,用于处理数据和分析数据. 使用pandas之前需要先安装pandas包,并通过import pandas as pd导入. ...
- pandas中的Series
我们使用pandas经常会用到其下面的一个类:Series,那么这个类都有哪些方法呢?另外Series和DataFrame都继承了NDFrame这个类,df.to_sql()这个方法其实就是NDFra ...
- [简单]docx4j常用方法小结
http://53873039oycg.iteye.com/blog/2194479?utm_source=tuicool&utm_medium=referral —————————————— ...
- Android Folding View(折叠视图、控件)
版本号:1.0 日期:2014.4.21 版权:© 2014 kince 转载注明出处 非常早之前看过有人求助以下这个效果是怎样实现的, 也就是側滑菜单的一个折叠效果,事实上关于这个效果的实现,谷 ...
- 深入理解Android中ViewGroup
文章目录 [隐藏] 一.ViewGroup是什么? 二.ViewGroup这个容器 2.1 添加View的算法 2.1.1 我们先来分析addViewInner方法: 2.1.2 addInArr ...
- dev简单实现柱状图,曲线图
1.数据源代码: DataTable dt = new DataTable(); dt.Columns.Add("A"); dt.Columns.Add("B" ...
- 【docx4j】docx4j操作docx,实现替换内容、转换pdf、html等操作
主要是想要用此功插件操作docx,主要的操作就是操作段落等信息,另外,也想实现替换docx的内容,实现根据模板动态生成内容的效果,也想用此插件实现docx转换pdf. word的格式其实可以用xml来 ...
- CopyOnWriteList-JDK1.8
CopyOnWrite,一个写时复制的技术来保证并发操作的安全,使用这种技术的前提是读大于写. 读读之间相容, 写写之间互斥, 读写操作相容. 实现方法: 在对底层数据进行写的时候,把底层数据复制一份 ...
- 推荐系统之基于图的推荐:基于随机游走的PersonalRank算法
转自http://blog.csdn.net/sinat_33741547/article/details/53002524 一 基本概念 基于图的模型是推荐系统中相当重要的一种方法,以下内容的基本思 ...
随机推荐
- matplotlib基础整理
matplotlib主要从下面几个方面进行整理: 折线图绘制:https://douzujun.github.io/page/%E6%95%B0%E6%8D%AE%E6%8C%96%E6%8E%98% ...
- Java并发编程原理与实战四十:JDK8新增LongAdder详解
传统的原子锁AtomicLong/AtomicInt虽然也可以处理大量并发情况下的计数器,但是由于使用了自旋等待,当存在大量竞争时,会存在大量自旋等待,而导致CPU浪费,而有效计算很少,降低了计算效率 ...
- SpringBoot 线程池配置 实现AsyncConfigurer接口方法
目的是: 通过实现AsyncConfigurer自定义线程池,包含异常处理 实现AsyncConfigurer接口对异常线程池更加细粒度的控制 *a) 创建线程自己的线程池 b) 对void ...
- 令assignment操作符返回一个reference to *this
[令assignment操作符返回一个reference to *this] 关于赋值,可以把它们写成连锁形式: int x, y, z; x =y =z =15; II赋值连锁形式 上述连锁赋值被解 ...
- [整理]ASP.NET vNext学习资源
http://www.hanselman.com/blog/IntroducingASPNETVNext.aspx http://blogs.msdn.com/b/dotnet/archive/201 ...
- HDU 1160 FatMouse's Speed (最长上升子序列)
题目链接 题意:n个老鼠有各自的重量和速度,要求输出最长的重量依次严格递增,速度依次严格递减的序列,n最多1000,重量速度1-10000. 题解:按照重量递增排序,找出最长的速度下降子序列,记录序列 ...
- 结构体变量的sizeof计算
结构体字节对齐准则: 1. 结构体变量的首地址能够被其最宽基本类型成员的大小所整除: 2. 结构体每个成员相对于结构体首地址的偏移量都是当前成员大小的整数倍,如有需要编译器会在成员之间加上填充字节: ...
- torch.nn.CrossEntropyLoss
class torch.nn.CrossEntropyLoss(weight=None, size_average=True, ignore_index=-100, reduce=True) 我这里没 ...
- Integer to Roman & Roman to Integer
Integer to Roman Given an integer, convert it to a roman numeral. The number is guaranteed to be wit ...
- scrapy shell命令的【选项】简介
在使用scrapy shell测试某网站时,其返回400 Bad Request,那么,更改User-Agent请求头信息再试. DEBUG: Crawled () <GET https://w ...