
ElasticSearch教程——自定义分词器(转学习使用)
一、分词器
Elasticsearch中,内置了很多分词器(analyzers),例如standard(标准分词器)、english(英文分词)和chinese(中文分词),默认是standard.
standard tokenizer:以单词边界进行切分
standard token filter:什么都不做
lowercase token filter:将所有字母转换为小写
stop token filer(默认被禁用):移除停用词,比如a the it等等
二、修改分词器设置
启用english,停用词token filter
PUT /my_index

{

  "settings": {

    "analysis": {

      "analyzer": {

        "es_std":{

          "type":"standard",

          "stopwords":"_english_"

        }

      }

    }

  }

}
三、标准分词测试代码
GET /my_index/_analyze

{

  "analyzer": "standard",

  "text":"a dog is in the house"

}
结果:
{

  "tokens": [

    {

      "token": "a",

      "start_offset": 0,

      "end_offset": 1,

      "type": "<ALPHANUM>",

      "position": 0

    },

    {

      "token": "dog",

      "start_offset": 2,

      "end_offset": 5,

      "type": "<ALPHANUM>",

      "position": 1

    },

    {

      "token": "is",

      "start_offset": 6,

      "end_offset": 8,

      "type": "<ALPHANUM>",

      "position": 2

    },

    {

      "token": "in",

      "start_offset": 9,

      "end_offset": 11,

      "type": "<ALPHANUM>",

      "position": 3

    },

    {

      "token": "the",

      "start_offset": 12,

      "end_offset": 15,

      "type": "<ALPHANUM>",

      "position": 4

    },

    {

      "token": "house",

      "start_offset": 16,

      "end_offset": 21,

      "type": "<ALPHANUM>",

      "position": 5

    }

  ]

}
四、设置的英文分词测试代码
GET /my_index/_analyze

{

  "analyzer": "es_std",

  "text":"a dog is in the house"

}
结果:
{

  "tokens": [

    {

      "token": "dog",

      "start_offset": 2,

      "end_offset": 5,

      "type": "<ALPHANUM>",

      "position": 1

    },

    {

      "token": "house",

      "start_offset": 16,

      "end_offset": 21,

      "type": "<ALPHANUM>",

      "position": 5

    }

  ]

}
五、自定义分词器
PUT /my_index

{

  "settings": {

    "analysis": {

      "char_filter": {

        "&_to_and": {

          "type": "mapping",

          "mappings": ["&=> and"]

        }

      },

      "filter": {

        "my_stopwords": {

          "type": "stop",

          "stopwords": ["the", "a"]

        }

      },

      "analyzer": {

        "my_analyzer": {

          "type": "custom",

          "char_filter": ["html_strip", "&_to_and"],

          "tokenizer": "standard",

          "filter": ["lowercase", "my_stopwords"]

        }

      }

    }

  }

}
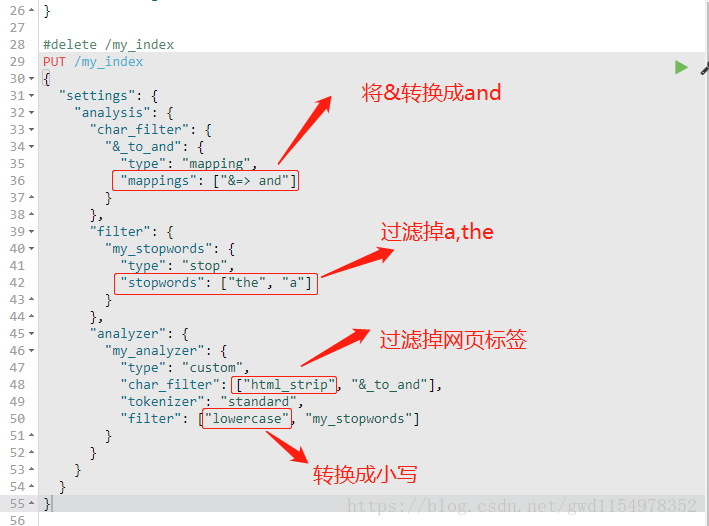
测试:
GET /my_index/_analyze

{

  "text": "tom&jerry are a friend in the house, <a>, HAHA!!",

  "analyzer": "my_analyzer"

}
结果:
{

  "tokens": [

    {

      "token": "tomandjerry",

      "start_offset": 0,

      "end_offset": 9,

      "type": "<ALPHANUM>",

      "position": 0

    },

    {

      "token": "are",

      "start_offset": 10,

      "end_offset": 13,

      "type": "<ALPHANUM>",

      "position": 1

    },

    {

      "token": "friend",

      "start_offset": 16,

      "end_offset": 22,

      "type": "<ALPHANUM>",

      "position": 3

    },

    {

      "token": "in",

      "start_offset": 23,

      "end_offset": 25,

      "type": "<ALPHANUM>",

      "position": 4

    },

    {

      "token": "house",

      "start_offset": 30,

      "end_offset": 35,

      "type": "<ALPHANUM>",

      "position": 6

    },

    {

      "token": "haha",

      "start_offset": 42,

      "end_offset": 46,

      "type": "<ALPHANUM>",

      "position": 7

    }

  ]

}
六、type中的使用
PUT /my_index/_mapping/my_type

{

  "properties": {

    "content": {

      "type": "text",

      "analyzer": "my_analyzer"

    }

  }

}
ElasticSearch教程——自定义分词器(转学习使用)的更多相关文章
- elasticsearch教程--中文分词器作用和使用
概述 本文都是基于elasticsearch安装教程 中的elasticsearch安装目录(/opt/environment/elasticsearch-6.4.0)为范例 环境准备 ·全新最小 ...
- Elasticsearch集成HanLP分词器-个人学习
1.通过git下载分词器代码. 连接如下:https://gitee.com/hualongdata/hanlp-ext hanlp官网如下:http://hanlp.linrunsoft.com/ ...
- Elasticsearch之中文分词器插件es-ik的自定义热更新词库
不多说,直接上干货! 欢迎大家,关注微信扫码并加入我的4个微信公众号: 大数据躺过的坑 Java从入门到架构师 人工智能躺过的坑 Java全栈大联盟 ...
- Elasticsearch笔记六之中文分词器及自定义分词器
中文分词器 在lunix下执行下列命令,可以看到本来应该按照中文"北京大学"来查询结果es将其分拆为"北","京","大" ...
- 【自定义IK词典】Elasticsearch之中文分词器插件es-ik的自定义词库
Elasticsearch之中文分词器插件es-ik 针对一些特殊的词语在分词的时候也需要能够识别 有人会问,那么,例如: 如果我想根据自己的本家姓氏来查询,如zhouls,姓氏“周”. 如 ...
- 【分词器及自定义】Elasticsearch中文分词器及自定义分词器
中文分词器 在lunix下执行下列命令,可以看到本来应该按照中文”北京大学”来查询结果es将其分拆为”北”,”京”,”大”,”学”四个汉字,这显然不符合我的预期.这是因为Es默认的是英文分词器我需要为 ...
- Elasticsearch修改分词器以及自定义分词器
Elasticsearch修改分词器以及自定义分词器 参考博客:https://blog.csdn.net/shuimofengyang/article/details/88973597
- ElasticSearch最全分词器比较及使用方法
介绍:ElasticSearch 是一个基于 Lucene 的搜索服务器.它提供了一个分布式多用户能力的全文搜索引擎,基于 RESTful web 接口.Elasticsearch 是用 Java 开 ...
- elasticsearch安装ansj分词器
1.概述 elasticsearch用于搜索引擎,需要设置一些分词器来优化索引.常用的有ik_max_word: 会将文本做最细粒度的拆分.ik_smart: 会做最粗粒度的拆分.ansj等. ...
随机推荐
- 第15.5节 PyQt的历史沿革介绍
当朋友向我推荐PyQt时,老猿才知道有这样一个在Python下的开源的图形界面开发工具,当准备学习PyQt安装时,发现要安装sip.PyQt.PyQt-tools,然后还要进行相关配置.老猿很好奇为什 ...
- PyQt(Python+Qt)学习随笔:QAbstractItemView的defaultDropAction属性
老猿Python博文目录 老猿Python博客地址# 一.概述 defaultDropAction属性用于控制QAbstractItemView及其子类的实例视图中拖放时放下的默认操作.该属性的类型为 ...
- 【聊技术】在Android中实现自适应文本大小显示
本周的聊技术话题和大家说说如何在Android中实现自适应文本大小显示. 想象一下,在布局中,通常显示文本的区域大小是固定的,但是文本长度并不总是固定的.比如列表中的文章标题.界面下方的按钮文本等等. ...
- 支持“EFDBContext”上下文的模型已在数据库创建后发生更改。请考虑使用 Code First 迁移更新数据库
在修改数据库表后会出现 支持"EFDBContext"上下文的模型已在数据库创建后发生更改.请考虑使用 Code First 迁移更新数据库 这个问题解决方法: 在Global.a ...
- webpack项目如何正确打包引入的自定义字体?
一. 如何在Vue或React项目中使用自定义字体 在开发前端项目时,经常会遇到UI同事希望在项目中使用一个炫酷字体的需求.那么怎么在项目中使用自定义字体呢? 其实实现起来并不复杂,可以借用CSS3 ...
- selenium模拟淘宝登陆,过所有验证
淘宝模拟登陆实现 由于淘宝使用了滑动验证码,需要进行模糊手动滑动,因此考虑使用selenium+chromedriver进行模拟登陆. 淘宝的登陆网址:https://login.taobao.com ...
- CF1400F - x-prime Substrings
1400F - x-prime Substrings 首先发现 \(x\) 很小,所以发现对应的 x-prime 字符串数也很少,最多的情况是 \(x = 19\),有 2399 个,先爆搜出来. 现 ...
- 【学习笔记】K-D tree 区域查询时间复杂度简易证明
查询算法的流程 如果查询与当前结点的区域无交集,直接跳出. 如果查询将当前结点的区域包含,直接跳出并上传答案. 有交集但不包含,继续递归求解. K-D Tree 如何划分区域 可以借助下文图片理解. ...
- dp斜率优化
算法-dp斜率优化 前置知识: 凸包 斜率优化很玄学,凭空讲怎么也讲不好,所以放例题. [APIO2014]序列分割 [APIO2014]序列分割 给你一个长度为 \(n\) 的序列 \(a_1,a_ ...
- SpringBoot + SpringSecurity + Mybatis-Plus + JWT + Redis 实现分布式系统认证和授权(刷新Token和Token黑名单)
1. 前提 本文在基于SpringBoot整合SpringSecurity实现JWT的前提中添加刷新Token以及添加Token黑名单.在浏览之前,请查看博客: SpringBoot + Sp ...