
Spring Boot集成sharding-jdbc实现分库分表
一、水平分割
1、水平分库
1)、概念:
以字段为依据,按照一定策略,将一个库中的数据拆分到多个库中。
2)、结果
每个库的结构都一样;数据都不一样;
所有库的并集是全量数据;
2、水平分表
1)、概念
以字段为依据,按照一定策略,将一个表中的数据拆分到多个表中。
2)、结果
每个表的结构都一样;数据都不一样;
所有表的并集是全量数据;
二、Shard-jdbc 中间件
1、架构图
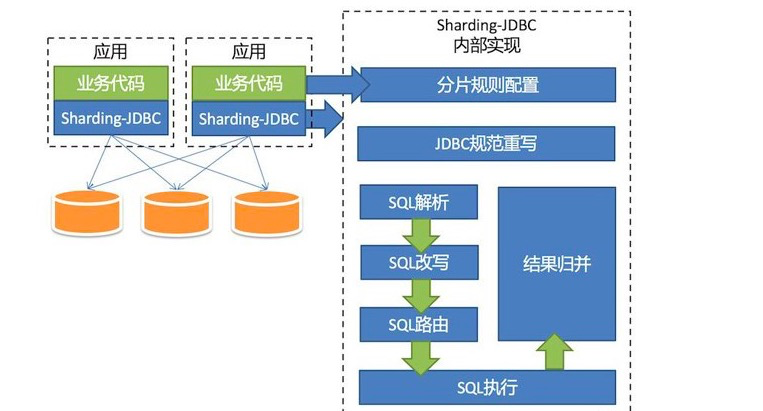
2、特点
1)、Sharding-JDBC直接封装JDBC API,旧代码迁移成本几乎为零。
2)、适用于任何基于Java的ORM框架,如Hibernate、Mybatis等 。
3)、可基于任何第三方的数据库连接池,如DBCP、C3P0、 BoneCP、Druid等。
4)、以jar包形式提供服务,无proxy代理层,无需额外部署,无其他依赖。
5)、分片策略灵活,可支持等号、between、in等多维度分片,也可支持多分片键。
6)、SQL解析功能完善,支持聚合、分组、排序、limit、or等查询。
三、项目演示

核心代码块
数据源配置文件
spring:

  datasource:

    # 数据源:shard_one

    dataOne:

      type: com.alibaba.druid.pool.DruidDataSource

      druid:

        driverClassName: com.mysql.jdbc.Driver

        url: jdbc:mysql://localhost:3306/shard_one?useUnicode=true&characterEncoding=UTF8&zeroDateTimeBehavior=convertToNull&useSSL=false

        username: root

        password: 123

        initial-size: 10

        max-active: 100

        min-idle: 10

        max-wait: 60000

        pool-prepared-statements: true

        max-pool-prepared-statement-per-connection-size: 20

        time-between-eviction-runs-millis: 60000

        min-evictable-idle-time-millis: 300000

        max-evictable-idle-time-millis: 60000

        validation-query: SELECT 1 FROM DUAL

        # validation-query-timeout: 5000

        test-on-borrow: false

        test-on-return: false

        test-while-idle: true

        connectionProperties: druid.stat.mergeSql=true;druid.stat.slowSqlMillis=5000

    # 数据源:shard_two

    dataTwo:

      type: com.alibaba.druid.pool.DruidDataSource

      druid:

        driverClassName: com.mysql.jdbc.Driver

        url: jdbc:mysql://localhost:3306/shard_two?useUnicode=true&characterEncoding=UTF8&zeroDateTimeBehavior=convertToNull&useSSL=false

        username: root

        password: 123

        initial-size: 10

        max-active: 100

        min-idle: 10

        max-wait: 60000

        pool-prepared-statements: true

        max-pool-prepared-statement-per-connection-size: 20

        time-between-eviction-runs-millis: 60000

        min-evictable-idle-time-millis: 300000

        max-evictable-idle-time-millis: 60000

        validation-query: SELECT 1 FROM DUAL

        # validation-query-timeout: 5000

        test-on-borrow: false

        test-on-return: false

        test-while-idle: true

        connectionProperties: druid.stat.mergeSql=true;druid.stat.slowSqlMillis=5000

    # 数据源:shard_three

    dataThree:

      type: com.alibaba.druid.pool.DruidDataSource

      druid:

        driverClassName: com.mysql.jdbc.Driver

        url: jdbc:mysql://localhost:3306/shard_three?useUnicode=true&characterEncoding=UTF8&zeroDateTimeBehavior=convertToNull&useSSL=false

        username: root

        password: 123

        initial-size: 10

        max-active: 100

        min-idle: 10

        max-wait: 60000

        pool-prepared-statements: true

        max-pool-prepared-statement-per-connection-size: 20

        time-between-eviction-runs-millis: 60000

        min-evictable-idle-time-millis: 300000

        max-evictable-idle-time-millis: 60000

        validation-query: SELECT 1 FROM DUAL

        # validation-query-timeout: 5000

        test-on-borrow: false

        test-on-return: false

        test-while-idle: true

        connectionProperties: druid.stat.mergeSql=true;druid.stat.slowSqlMillis=5000

数据库分库策略
/**

 * 数据库映射计算

 */

public class DataSourceAlg implements PreciseShardingAlgorithm<String> {

    private static Logger LOG = LoggerFactory.getLogger(DataSourceAlg.class);

    @Override

    public String doSharding(Collection<String> names, PreciseShardingValue<String> value) {

        LOG.debug("分库算法参数 {},{}",names,value);

        int hash = HashUtil.rsHash(String.valueOf(value.getValue()));

        return "ds_" + ((hash % 2) + 2) ;

    }

}
数据表1分表策略
/**

 * 分表算法

 */

public class TableOneAlg implements PreciseShardingAlgorithm<String> {

    private static Logger LOG = LoggerFactory.getLogger(TableOneAlg.class);

    /**

     * 该表每个库分5张表

     */

    @Override

    public String doSharding(Collection<String> names, PreciseShardingValue<String> value) {

        LOG.debug("分表算法参数 {},{}",names,value);

        int hash = HashUtil.rsHash(String.valueOf(value.getValue()));

        return "table_one_" + (hash % 5+1);

    }

}

数据表2分表策略
/**

 * 分表算法

 */

public class TableTwoAlg implements PreciseShardingAlgorithm<String> {

    private static Logger LOG = LoggerFactory.getLogger(TableTwoAlg.class);

    /**

     * 该表每个库分5张表

     */

    @Override

    public String doSharding(Collection<String> names, PreciseShardingValue<String> value) {

        LOG.debug("分表算法参数 {},{}",names,value);

        int hash = HashUtil.rsHash(String.valueOf(value.getValue()));

        return "table_two_" + (hash % 5+1);

    }

}

数据源集成配置
/**

 * 数据库分库分表配置

 */

@Configuration

public class ShardJdbcConfig {

    // 省略了 druid 配置,源码中有

    /**

     * Shard-JDBC 分库配置

     */

    @Bean

    public DataSource dataSource (@Autowired DruidDataSource dataOneSource,

                                  @Autowired DruidDataSource dataTwoSource,

                                  @Autowired DruidDataSource dataThreeSource) throws Exception {

        ShardingRuleConfiguration shardJdbcConfig = new ShardingRuleConfiguration();

        shardJdbcConfig.getTableRuleConfigs().add(getTableRule01());

        shardJdbcConfig.getTableRuleConfigs().add(getTableRule02());

        shardJdbcConfig.setDefaultDataSourceName("ds_0");

        Map<String,DataSource> dataMap = new LinkedHashMap<>() ;

        dataMap.put("ds_0",dataOneSource) ;

        dataMap.put("ds_2",dataTwoSource) ;

        dataMap.put("ds_3",dataThreeSource) ;

        Properties prop = new Properties();

        return ShardingDataSourceFactory.createDataSource(dataMap, shardJdbcConfig, new HashMap<>(), prop);

    }

    /**

     * Shard-JDBC 分表配置

     */

    private static TableRuleConfiguration getTableRule01() {

        TableRuleConfiguration result = new TableRuleConfiguration();

        result.setLogicTable("table_one");

        result.setActualDataNodes("ds_${2..3}.table_one_${1..5}");

        result.setDatabaseShardingStrategyConfig(new StandardShardingStrategyConfiguration("phone", new DataSourceAlg()));

        result.setTableShardingStrategyConfig(new StandardShardingStrategyConfiguration("phone", new TableOneAlg()));

        return result;

    }

    private static TableRuleConfiguration getTableRule02() {

        TableRuleConfiguration result = new TableRuleConfiguration();

        result.setLogicTable("table_two");

        result.setActualDataNodes("ds_${2..3}.table_two_${1..5}");

        result.setDatabaseShardingStrategyConfig(new StandardShardingStrategyConfiguration("phone", new DataSourceAlg()));

        result.setTableShardingStrategyConfig(new StandardShardingStrategyConfiguration("phone", new TableTwoAlg()));

        return result;

    }

}
Spring Boot集成sharding-jdbc实现分库分表的更多相关文章
- Sharding Sphere的分库分表
什么是 ShardingSphere? 1.一套开源的分布式数据库中间件解决方案 2.有三个产品:Sharding-JDBC 和 Sharding-Proxy 3.定位为关系型数据库中间件,合理在分布 ...
- spring boot:shardingsphere多数据源,支持未分表的数据源(shardingjdbc 4.1.1)
一,为什么要给shardingsphere配置多数据源? 1,shardingjdbc默认接管了所有的数据源, 如果我们有多个非分表的库时,则最多只能设置一个为默认数据库, 其他的非分表数据库不能访问 ...
- Spring Boot中整合Sharding-JDBC单库分表示例
本文是Sharding-JDBC采用Spring Boot Starter方式配置第二篇,第一篇是读写分离讲解,请参考:<Spring Boot中整合Sharding-JDBC读写分离示例> ...
- Spring boot项目集成Sharding Jdbc
环境 jdk:1.8 framework: spring boot, sharding jdbc database: MySQL 搭建步骤 在pom 中加入sharding 依赖 <depend ...
- 分库分表技术演进&最佳实践
每个优秀的程序员和架构师都应该掌握分库分表,这是我的观点. 移动互联网时代,海量的用户每天产生海量的数量,比如: 用户表 订单表 交易流水表 以支付宝用户为例,8亿:微信用户更是10亿.订单表更夸张, ...
- 分库分表后跨分片查询与Elastic Search
携程酒店订单Elastic Search实战:http://www.lvesu.com/blog/main/cms-610.html 为什么分库分表后不建议跨分片查询:https://www.jian ...
- 【大数据和云计算技术社区】分库分表技术演进&最佳实践笔记
1.需求背景 移动互联网时代,海量的用户每天产生海量的数量,这些海量数据远不是一张表能Hold住的.比如 用户表:支付宝8亿,微信10亿.CITIC对公140万,对私8700万. 订单表:美团每天几千 ...
- java 取模运算% 实则取余 简述 例子 应用在数据库分库分表
java 取模运算% 实则取余 简述 例子 应用在数据库分库分表 取模运算 求模运算与求余运算不同.“模”是“Mod”的音译,模运算多应用于程序编写中. Mod的含义为求余.模运算在数论和程序设计中 ...
- spring boot sharding-jdbc实现分佈式读写分离和分库分表的实现
分布式读写分离和分库分表采用sharding-jdbc实现. sharding-jdbc是当当网推出的一款读写分离实现插件,其他的还有mycat,或者纯粹的Aop代码控制实现. 接下面用spring ...
随机推荐
- MyBatis(七):MyBatis缓存详解(一级缓存/二级缓存)
一级缓存 MyBatis一级缓存上SqlSession缓存,即在统一SqlSession中,在不执行增删改操作提交事务的前提下,对同一条数据进行多次查询时,第一次查询从数据库中查询,完成后会存入缓 ...
- Hibernate在oracle中ID增长的方式(续)
引用链接:http://blog.csdn.net/w183705952/article/details/7367272 第二种:设置ID的增长策略是native,但是需要创建一个名字为hiberna ...
- 卷积神经网络学习笔记——轻量化网络MobileNet系列(V1,V2,V3)
完整代码及其数据,请移步小编的GitHub地址 传送门:请点击我 如果点击有误:https://github.com/LeBron-Jian/DeepLearningNote 这里结合网络的资料和Mo ...
- android分析之mutex
Android的锁是对Linux锁的一种包装: // ------------------------------------------------------------------------- ...
- golang 实现两数组对应元素相除
func ArrayDivision(arr1 []float64,arr2 []float64) (arr3 []float64) { //两数组对应元素相除 for p:=0;p< len( ...
- HiveHA机制源码分析
hive让大数据飞了起来,不再需要专人写MR.平常我们都可以用基于thrift的任意语言来调用hive. 不过爱恨各半,hive的thrift不稳定也是出了名的.很容易就出问题,让人无计可施.唯一的办 ...
- 高精地图技术专栏 | 基于空间连续性的异常3D点云修复技术
1.背景 1.1 高精资料采集 高精采集车是集成了测绘激光.高性能惯导.高分辨率相机等传感器为一体的移动测绘系统.高德高精团队经过多年深耕打造的采集车,具有精度高.速度快.数据产生周期短.自动化程度高 ...
- 从键盘读入学生成绩,找出最高分, 并输出学生成绩等级(Java)
从键盘读入学生成绩,找出最高分, 并输出学生成绩等级 一.题目 从键盘读入学生成绩,找出最高分,并输出学生成绩等级. 成绩>=最高分-10 等级为'A' 成绩>=最高分-20 等级为'B' ...
- Spring Boot demo系列(十):Redis缓存
1 概述 本文演示了如何在Spring Boot中将Redis作为缓存使用,具体的内容包括: 环境搭建 项目搭建 测试 2 环境 Redis MySQL MyBatis Plus 3 Redis安装 ...
- 源码编译安装MySQL8.0.20
1 概述 本文章主要讲述了如何从源码编译安装MySQL社区版8.0.20,首先会介绍一些编译安装的相关知识,然后开始编译安装 2 源码编译安装的相关知识 2.1 make与configure make ...