
莫烦大大TensorFlow学习笔记(8)----优化器
一、TensorFlow中的优化器
- tf.train.GradientDescentOptimizer:梯度下降算法
- tf.train.AdadeltaOptimizer
- tf.train.AdagradOptimizer
- tf.train.MomentumOptimizer:动量梯度下降算法
- tf.train.AdamOptimizer:自适应矩估计优化算法
- tf.train.RMSPropOptimizer
- tf.train.AdagradDAOptimizer
- tf.train.FtrlOptimizer
- tf.train.ProximalGradientDescentOptimizer
- tf.train.ProximalAdagradOptimizertf.train.RMSProOptimizer
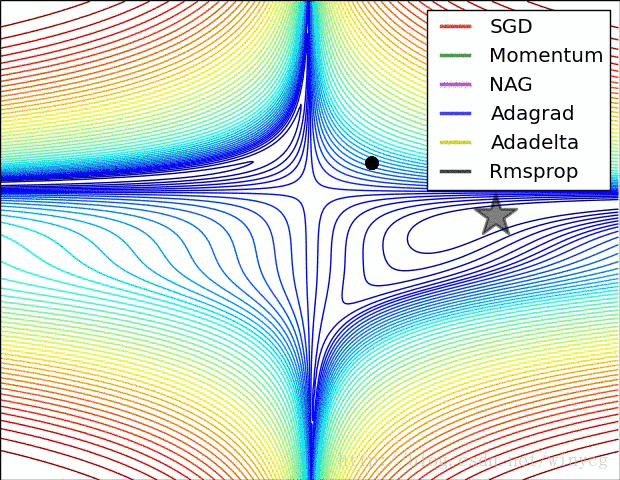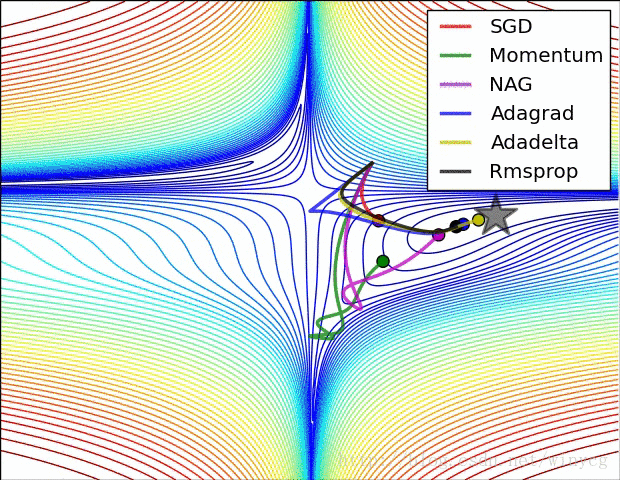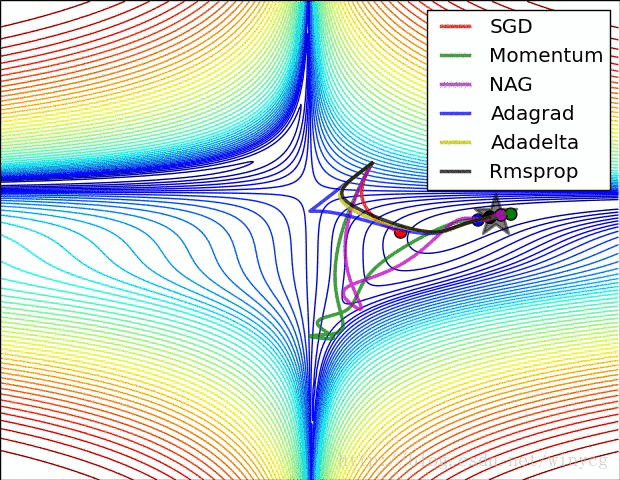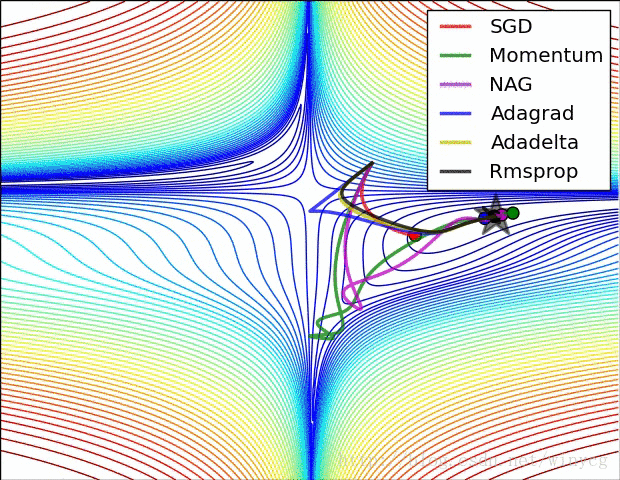
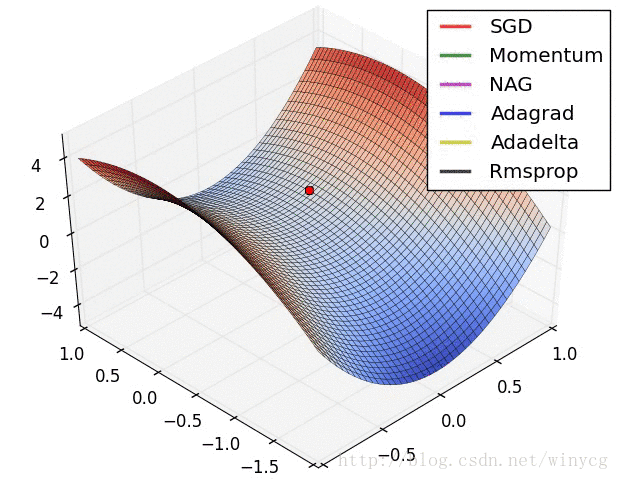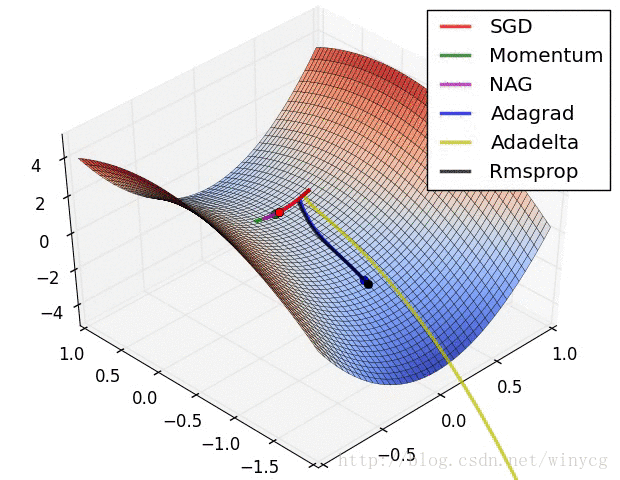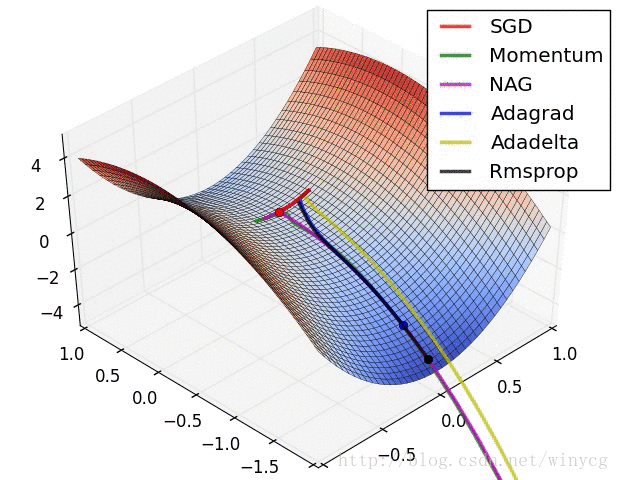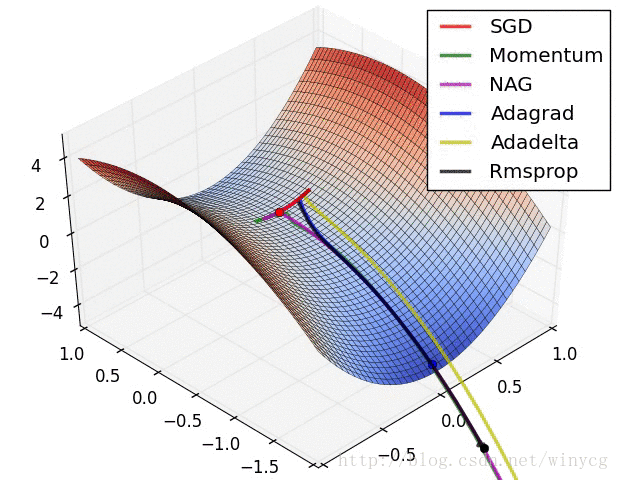
(1)如果数据是稀疏的,使用自适应学习方法。
(2)RMSprop,Adadelta,Adam是非常相似的优化算法,Adam的bias-correction帮助其在最后优化期间梯度变稀疏的情况下略微战胜了RMSprop。整体来讲,Adam是最好的选择。
(3)很多论文中使用vanilla SGD without momentum。SGD通常能找到最小值,但是依赖健壮的初始化,并且容易陷入鞍点。因此,如果要获得更快的收敛速度和训练更深更复杂的神经网络,需要选择自适应学习方法。
https://blog.csdn.net/winycg/article/details/79363169
二、常用的种类:
1、tf.train.Optimizer:
2、tf.train.GradientDescentOptimizer:梯度下降
原理:
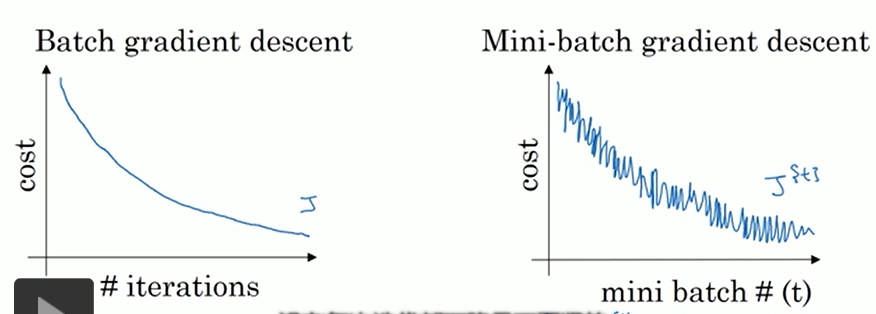
batch GD【全部样本,速度慢】
随机GD【随机一个样本,速度快,但局部最优】
mini-batch GD 【batch个样本,常在数据量较大时使用】
训练集样本数少【≤2000】:采用batchGD
训练集样本数多:采用mini-batch GD,batch大小一般为64-512. 训练时多尝试一下2的次方来找到最合适的batch大小。
应用:
这个类是实现梯度下降算法的优化器。这个构造函数需要的一个学习率就行了。
构造函数:tf.train.GradientDescentOptimizer(0.001).minimize(loss,global_step=None,var_list=None,gate_gradients=GATE_OP,aggregation_method=None,colocate_gradients_with_ops=False,name=None,grad_loss=None)
 __init__(

     learning_rate,

     use_locking=False,

     name='GradientDescent'

 )
learning_rate: (学习率)张量或者浮点数
use_locking: 为True时锁定更新
name: 梯度下降名称,默认为"GradientDescent".
3、tf.train.AdadeltaOptimizer:
实现了 Adadelta算法的优化器,可以算是下面的Adagrad算法改进版本。
构造函数: tf.train.AdadeltaOptimizer.init(learning_rate=0.001, rho=0.95, epsilon=1e-08, use_locking=False, name=’Adadelta’)
4、tf.train.AdagradOptimizer:
构造函数:tf.train.AdagradOptimizer.__init__(learning_rate, initial_accumulator_value=0.1, use_locking=False, name=’Adagrad’)
5、tf.train.MomentumOptimizer:
原理:

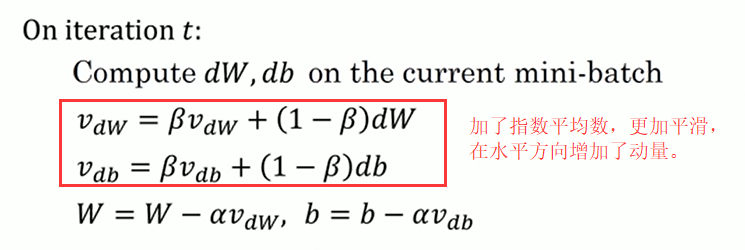
momentum表示要在多大程度上保留原来的更新方向,这个值在0-1之间,在训练开始时,由于梯度可能会很大,所以初始值一般选为0.5;当梯度不那么大时,改为0.9。 α是学习率,即当前batch的梯度多大程度上影响最终更新方向,跟普通的SGD含义相同。
应用:
构造函数:tf.train.MomentumOptimizer.__init__(learning_rate, momentum, use_locking=False, name=’Momentum’, use_nesterov=False)
 __init__(

     learning_rate,

     momentum,

     use_locking=False,

     name='Momentum',

     use_nesterov=False

 )
learning_rate: (学习率)张量或者浮点数
momentum: (动量)张量或者浮点数
use_locking: 为True时锁定更新
name: 梯度下降名称,默认为 "Momentum".
use_nesterov: 为True时,使用 Nesterov Momentum.
6、tf.train.RMSPropOptimizer
目的和动量梯度一样,减小垂直方向,增大水平方向。W为水平方向,b为垂直方向。

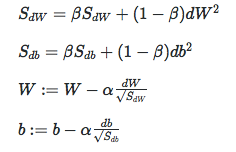
7、tf.train.AdamOptimizer:动量和RMSProp结合

应用:
 __init__(

     learning_rate=0.001,

     beta1=0.9,

     beta2=0.999,

     epsilon=1e-08,

     use_locking=False,

     name='Adam'

 )
构造函数:tf.train.AdamOptimizer.__init__(learning_rate=0.001, beta1=0.9, beta2=0.999, epsilon=1e-08, use_locking=False, name=’Adam’)
learning_rate: (学习率)张量或者浮点数,需要调试
beta1: 浮点数或者常量张量 ,表示 The exponential decay rate for the 1st moment estimates.【推荐使用0.9】
beta2: 浮点数或者常量张量 ,表示 The exponential decay rate for the 2nd moment estimates.【推荐使用0.999】
epsilon: A small constant for numerical stability. This epsilon is "epsilon hat" in the Kingma and Ba paper (in the formula just before Section 2.1), not the epsilon in Algorithm 1 of the paper.
use_locking: 为True时锁定更新
name: 梯度下降名称,默认为 "Adam".
莫烦大大TensorFlow学习笔记(8)----优化器的更多相关文章
- 莫烦大大TensorFlow学习笔记(9)----可视化
一.Matplotlib[结果可视化] #import os #os.environ['TF_CPP_MIN_LOG_LEVEL'] = '2' import tensorflow as tf i ...
- 莫烦python教程学习笔记——总结篇
一.机器学习算法分类: 监督学习:提供数据和数据分类标签.--分类.回归 非监督学习:只提供数据,不提供标签. 半监督学习 强化学习:尝试各种手段,自己去适应环境和规则.总结经验利用反馈,不断提高算法 ...
- 莫烦python教程学习笔记——保存模型、加载模型的两种方法
# View more python tutorials on my Youtube and Youku channel!!! # Youtube video tutorial: https://ww ...
- 莫烦python教程学习笔记——validation_curve用于调参
# View more python learning tutorial on my Youtube and Youku channel!!! # Youtube video tutorial: ht ...
- 莫烦python教程学习笔记——learn_curve曲线用于过拟合问题
# View more python learning tutorial on my Youtube and Youku channel!!! # Youtube video tutorial: ht ...
- 莫烦python教程学习笔记——利用交叉验证计算模型得分、选择模型参数
# View more python learning tutorial on my Youtube and Youku channel!!! # Youtube video tutorial: ht ...
- 莫烦python教程学习笔记——数据预处理之normalization
# View more python learning tutorial on my Youtube and Youku channel!!! # Youtube video tutorial: ht ...
- 莫烦python教程学习笔记——线性回归模型的属性
#调用查看线性回归的几个属性 # Youtube video tutorial: https://www.youtube.com/channel/UCdyjiB5H8Pu7aDTNVXTTpcg # ...
- 莫烦python教程学习笔记——使用波士顿数据集、生成用于回归的数据集
# View more python learning tutorial on my Youtube and Youku channel!!! # Youtube video tutorial: ht ...
随机推荐
- 在Win32 Application 环境下实现MFC窗口的创建
// Win32下MFC.cpp : Defines the entry point for the application.// #include "stdafx.h" clas ...
- lucene_02_IKAnalyre
前言 在lucene中虽然已经提供了许多的分词器:StandardAnalyzer.CJKAnalyzer等,但在解析中文的时候都会把文中拆成一个个的单子. 毕竟老外不懂中文.这里介绍一个中文的分词器 ...
- LaTeX的简单使用方法
先来一个总结得比较好的https://blog.csdn.net/garfielder007/article/details/51646604 1.普通公式 $公式不换行$ $公式不换行$ $$公式独 ...
- rabbitmq安装、集群搭建
rabbitmq的安装: CentOS上面部署: 首先修改hosts文件 修改hosts文件vi /etc/hosts1.1.1.1 hostname 2.2.2.2 hostname 3.3.3.3 ...
- 一次完整的http事务
一次完整的http事务 https://www.processon.com/view/link/56c6679ce4b0f0c4285e69c0 规范把 HTTP 请求分为三个部分:状态行.请求头.消 ...
- HDU 3432
水题,就是把一个矩形平分. 题意:一个wid*hei的矩形,过底边上的一点(dor,0)做m-1条射线,把这个矩形的面积平均分成m份,求这些射线和矩形的另外一个交点. 直接枚举,然而求三角形高底移动坐 ...
- GitLab 7.5.3 CentOS7安装和SMTP配置
CentOS 7安装GitLab还是比較简单的,依照官方文档的提示一步一步操作下来.就一个地方须要改动. 參考:GitLab安装说明 在安装好以后,执行 gitlab-ctl reconfigure ...
- Maven学习--------基础2
继续学习Maven. 4.2 变量 1) 问:怎样使用变量替换?项目中的某个配置文件比方jdbc.properties使用了一些pom中的变量,怎样在公布中使用包括真实内容的终于结果文件? 答:使用资 ...
- Hadoop入门进阶步步高(一)-环境准备
前言 Hadoop从存储上来说,是相似于冗余磁盘阵列(RAID)的存储方式.将数据分散存储并提供以提供吞吐量,它的存储系统就是HDFS(Hadoop Distuibute Fils System).从 ...
- @RequiresPermissions 注解说明
@RequiresAuthentication验证用户是否登录,等同于方法subject.isAuthenticated() 结果为true时.@RequiresUser验证用户是否被记忆,user有 ...