
Strom的trident单词计数代码
 /**

  * 单词计数

  */

 public class LocalTridentCount {

     public static class MyBatchSpout implements IBatchSpout {

         Fields fields;

         HashMap<Long, List<List<Object>>> batches = new HashMap<Long, List<List<Object>>>();

         public MyBatchSpout(Fields fields) {

             this.fields = fields;

         }

         @Override

         public void open(Map conf, TopologyContext context) {

         }

         @Override

         public void emitBatch(long batchId, TridentCollector collector) {

             List<List<Object>> batch = this.batches.get(batchId);

             if(batch == null){

                 batch = new ArrayList<List<Object>>();

                 Collection<File> listFiles = FileUtils.listFiles(new File("d:\\stormtest"), new String[]{"txt"}, true);

                 for (File file : listFiles) {

                     List<String> readLines;

                     try {

                         readLines = FileUtils.readLines(file);

                         for (String line : readLines) {

                             batch.add(new Values(line));

                         }

                         FileUtils.moveFile(file, new File(file.getAbsolutePath()+System.currentTimeMillis()));

                     } catch (IOException e) {

                         e.printStackTrace();

                     }

                 }

                 if(batch.size()>0){

                     this.batches.put(batchId, batch);

                 }

             }

             for(List<Object> list : batch){

                 collector.emit(list);

             }

         }

         @Override

         public void ack(long batchId) {

             this.batches.remove(batchId);

         }

         @Override

         public void close() {

         }

         @Override

         public Map getComponentConfiguration() {

             Config conf = new Config();

             conf.setMaxTaskParallelism(1);

             return conf;

         }

         @Override

         public Fields getOutputFields() {

             return fields;

         }

     }

     /**

      * 对一行行的数据进行切割成一个个单词

      */

     public static class MySplit extends BaseFunction{

         @Override

         public void execute(TridentTuple tuple, TridentCollector collector) {

             String line = tuple.getStringByField("lines");

             String[] words = line.split("\t");

             for (String word : words) {

                 collector.emit(new Values(word));

             }

         }

     }

     public static class MyWordAgge extends BaseAggregator<Map<String, Integer>>{

         @Override

         public Map<String, Integer> init(Object batchId,

                 TridentCollector collector) {

             return new HashMap<String, Integer>();

         }

         @Override

         public void aggregate(Map<String, Integer> val, TridentTuple tuple,

                 TridentCollector collector) {

             String key = tuple.getString(0);

             /*Integer integer = val.get(key);

             if(integer==null){

                 integer=0;

             }

             integer++;

             val.put(key, integer);*/

             val.put(key, MapUtils.getInteger(val, key, 0)+1);

         }

         @Override

         public void complete(Map<String, Integer> val,

                 TridentCollector collector) {

             collector.emit(new Values(val));

         }

     }

     /**

      * 汇总局部的map,并且打印结果

      *

      */

     public static class MyCountPrint extends BaseFunction{

         HashMap<String, Integer> hashMap = new HashMap<String, Integer>();

         @Override

         public void execute(TridentTuple tuple, TridentCollector collector) {

             Map<String, Integer> map = (Map<String, Integer>)tuple.get(0);

             for (Entry<String, Integer> entry : map.entrySet()) {

                 String key = entry.getKey();

                 Integer value = entry.getValue();

                 Integer integer = hashMap.get(key);

                 if(integer==null){

                     integer=0;

                 }

                 hashMap.put(key, integer+value);

             }

             Utils.sleep(1000);

             System.out.println("==================================");

             for (Entry<String, Integer> entry : hashMap.entrySet()) {

                 System.out.println(entry);

             }

         }

     }

     public static void main(String[] args) {

         //大体流程:首先设置一个数据源MyBatchSpout,会监控指定目录下文件的变化,当发现有新文件的时候把文件中的数据取出来,

         //然后封装到一个batch中发射出来.就会对tuple中的数据进行处理,把每个tuple中的数据都取出来,然后切割..切割成一个个的单词.

         //单词发射出来之后,会对单词进行分组,会对一批假设有10个tuple,会对这10个tuple分完词之后的单词进行分组, 相同的单词分一块

         //分完之后聚合 把相同的单词使用同一个聚合器聚合  然后出结果  每个单词出现多少次...

         //进行汇总  先每一批数据局部汇总  最后全局汇总....

         //这个代码也不是很简单...挺多....就是使用批处理的方式.

         TridentTopology tridentTopology = new TridentTopology();

         tridentTopology.newStream("spoutid", new MyBatchSpout(new Fields("lines")))

             .each(new Fields("lines"), new MySplit(), new Fields("word"))

             .groupBy(new Fields("word"))//用到了分组 对一批tuple中的单词进行分组..

             .aggregate(new Fields("word"), new MyWordAgge(), new Fields("wwwww"))//用到了聚合

             .each(new Fields("wwwww"), new MyCountPrint(), new Fields(""));

         LocalCluster localCluster = new LocalCluster();

         String simpleName = TridentMeger.class.getSimpleName();

         localCluster.submitTopology(simpleName, new Config(), tridentTopology.build());

     }

 }
指定路径下文件中的内容:
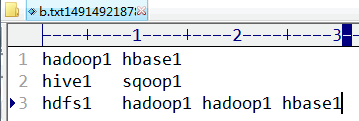
程序运行结果:

Strom的trident单词计数代码的更多相关文章
- Storm官方提供的trident单词计数的例子
上代码: public class TridentWordCount { public static class Split extends BaseFunction { @Override publ ...
- Strom实现单词统计代码
import java.io.File; import java.io.IOException; import java.util.Collection; import java.util.HashM ...
- 自定义实现InputFormat、OutputFormat、输出到多个文件目录中去、hadoop1.x api写单词计数的例子、运行时接收命令行参数,代码例子
一:自定义实现InputFormat *数据源来自于内存 *1.InputFormat是用于处理各种数据源的,下面是实现InputFormat,数据源是来自于内存. *1.1 在程序的job.setI ...
- storm(5)-分布式单词计数例子
例子需求: spout:向后端发送{"sentence":"my dog has fleas"}.一般要连数据源,此处简化写死了. 语句分割bolt(Split ...
- MapReduce之单词计数
最近在看google那篇经典的MapReduce论文,中文版可以参考孟岩推荐的 mapreduce 中文版 中文翻译 论文中提到,MapReduce的编程模型就是: 计算利用一个输入key/value ...
- hadoop笔记之MapReduce的应用案例(WordCount单词计数)
MapReduce的应用案例(WordCount单词计数) MapReduce的应用案例(WordCount单词计数) 1. WordCount单词计数 作用: 计算文件中出现每个单词的频数 输入结果 ...
- 第一章 flex单词计数程序
学习Flex&Bison目标, 读懂SQLite中SQL解析部分代码 Flex&Bison简介Flex做词法分析Bison做语法分析 第一个Flex程序, wc.fl, 单词计数程序 ...
- 大数据【四】MapReduce(单词计数;二次排序;计数器;join;分布式缓存)
前言: 根据前面的几篇博客学习,现在可以进行MapReduce学习了.本篇博客首先阐述了MapReduce的概念及使用原理,其次直接从五个实验中实践学习(单词计数,二次排序,计数器,join,分 ...
- Storm实现单词统计代码
import java.io.File; import java.io.IOException; import java.util.Collection; import java.util.HashM ...
随机推荐
- 3-具体学习git--reset回到过去的版本(commit间穿梭),checkout单个文件穿梭
git log --oneline 命令可以在一块儿显示做过的改动. 我在change 2时忘了一条,想在change 1后再添加一个语句或一个操作,然后这个状态再提交仍作为change 2.将这个s ...
- vue中的路由独享守卫的理解
1.vue中路由独享守卫意思就是对这个路由有一个单独的守卫,因为他的守卫方式于其他的凡是不太同 独享守卫于前置守卫使用方法大致是一样的 在路由配置的时候进行配置, { path:'/login', c ...
- JAVA技术路线2
https://www.zhihu.com/question/56110328 1.JavaSE学习视频 http://pan.baidu.com/s/1bp3g6rd2.javaweb的学习视频 h ...
- java并发控制工具类和集合等
转载自:https://my.oschina.net/hosee/blog/607677 摘要: 本系列基于炼数成金课程,为了更好的学习,做了系列的记录. 本文主要介绍: 1.各种同步控制工具的使用 ...
- 微信分享接口 略缩图 php
php插件下载地址: https://files.cnblogs.com/files/fan-bk/jssdk_php.rar 提示:如果插件里面的jssdk.php函数 file_get_cont ...
- 微信小程序两种滑动方式
竖向滑动: <scroll-view scroll-y="true" style="height: 200rpx;"> <view style ...
- 快速创建一个 Servlet 项目(1)
1. 新建一个 maven project (web app) 得到如下项目 2. 添加 servlet 和 jsp 依赖 通常 servlet 和 jsp 依赖由web容器提供,这个编译错误并不会影 ...
- MyBatis(一)helloWorld程序
一.准备两个jar包,第一个:下载myBatis-3.3.1.jar,这里是在CSDN网站处下载的,因为官网打不开.第二个:mysql-connector-java-5.0.8-bin.jar,这个j ...
- mach_absolute_time 使用
今天看荣哥时间常用函数封装里有个不常见的函数 ,mach_absolute_time() ,经查询后感觉是个不错的函数,网上关于这个函数搜索以后简单整理来一下. 什么事Mach? 时间例程依赖于所需要 ...
- TypeScript开发环境搭建(Visual studio code)
使用Visual Studio Code搭建TypeScript开发环境 1.TypeScript是干什么的 ? TypeScript是由微软Anders Hejlsberg(安德斯·海尔斯伯格,也是 ...