
Python爬虫:设置Cookie解决网站拦截并爬取蚂蚁短租
前言
文的文字及图片来源于网络,仅供学习、交流使用,不具有任何商业用途,版权归原作者所有,如有问题请及时联系我们以作处理。
作者: Eastmount
PS:如有需要Python学习资料的小伙伴可以加点击下方链接自行获取
http://note.youdao.com/noteshare?id=3054cce4add8a909e784ad934f956cef
我们在编写Python爬虫时,有时会遇到网站拒绝访问等反爬手段,比如这么我们想爬取蚂蚁短租数据,它则会提示“当前访问疑似黑客攻击,已被网站管理员设置为拦截”提示,如下图所示。此时我们需要采用设置Cookie来进行爬取,下面我们进行详细介绍。非常感谢我的学生承峰提供的思想,后浪推前浪啊!
一. 网站分析与爬虫拦截
当我们打开蚂蚁短租搜索贵阳市,反馈如下图所示结果。 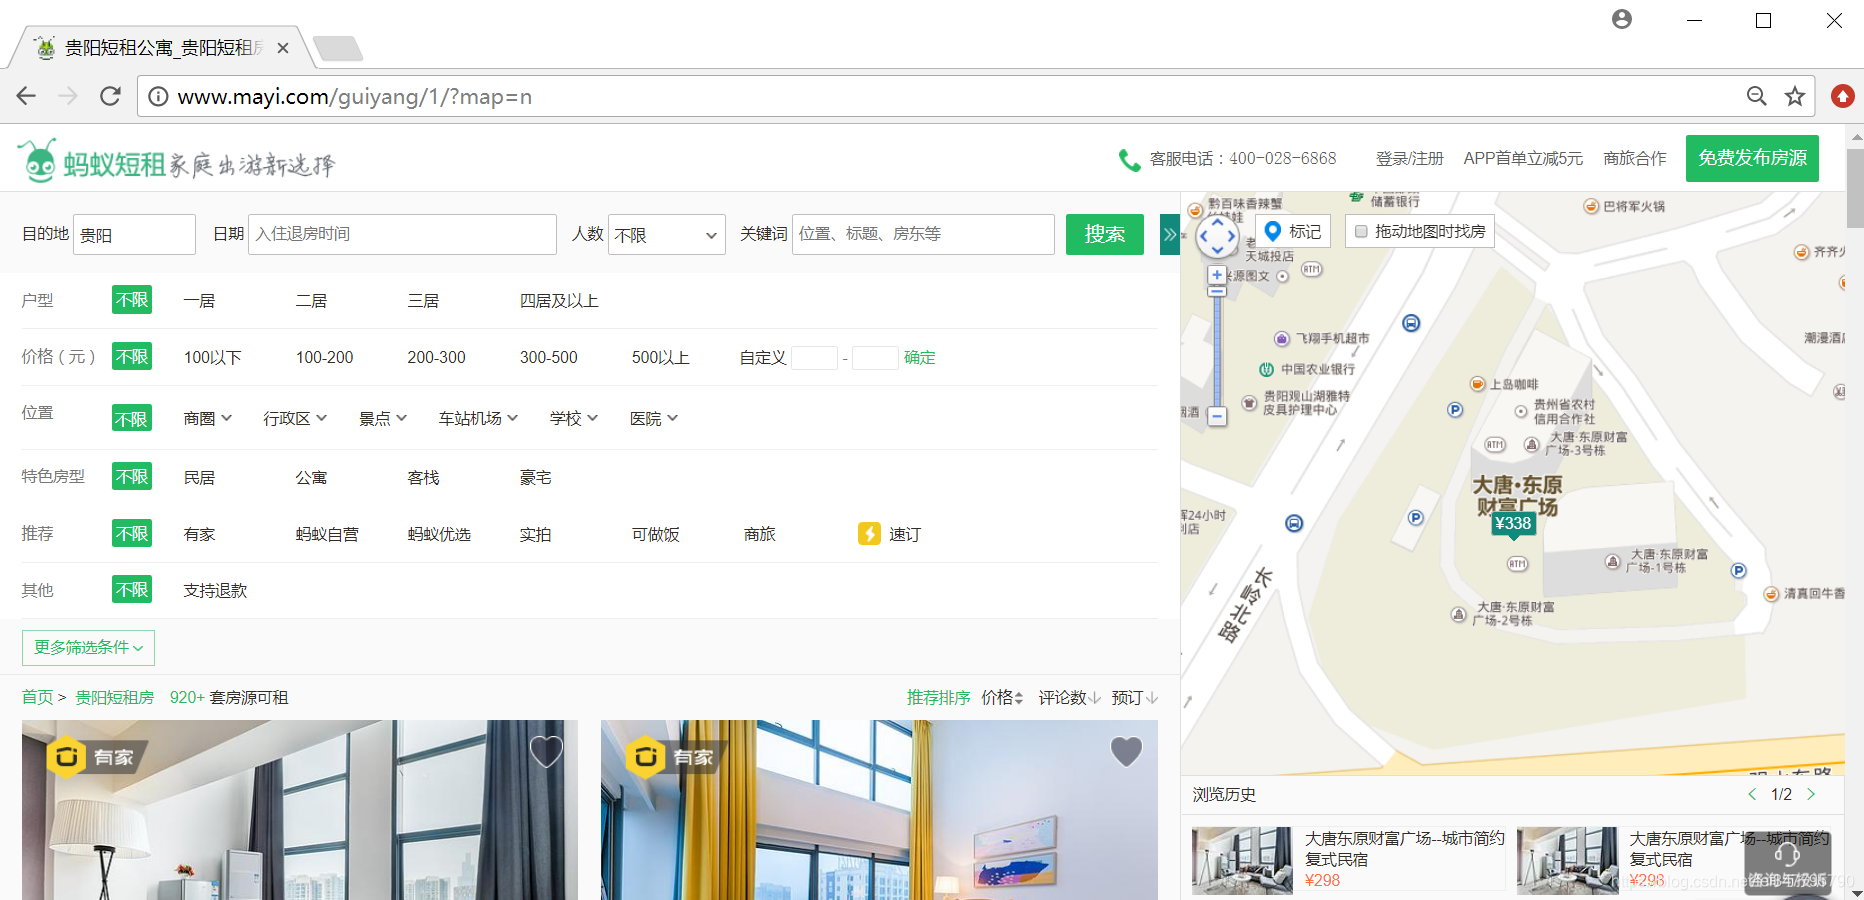 我们可以看到短租房信息呈现一定规律分布,如下图所示,这也是我们要爬取的信息。
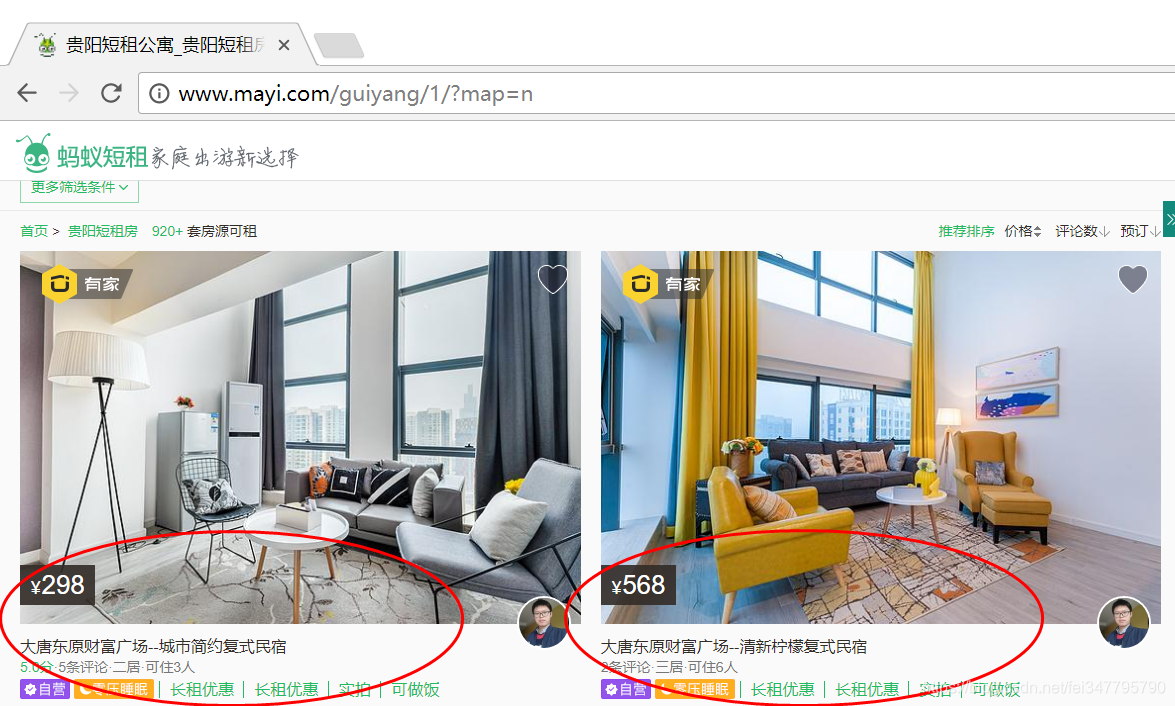
通过浏览器审查元素,我们可以看到需要爬取每条租房信息都位于<dd></dd>节点下。 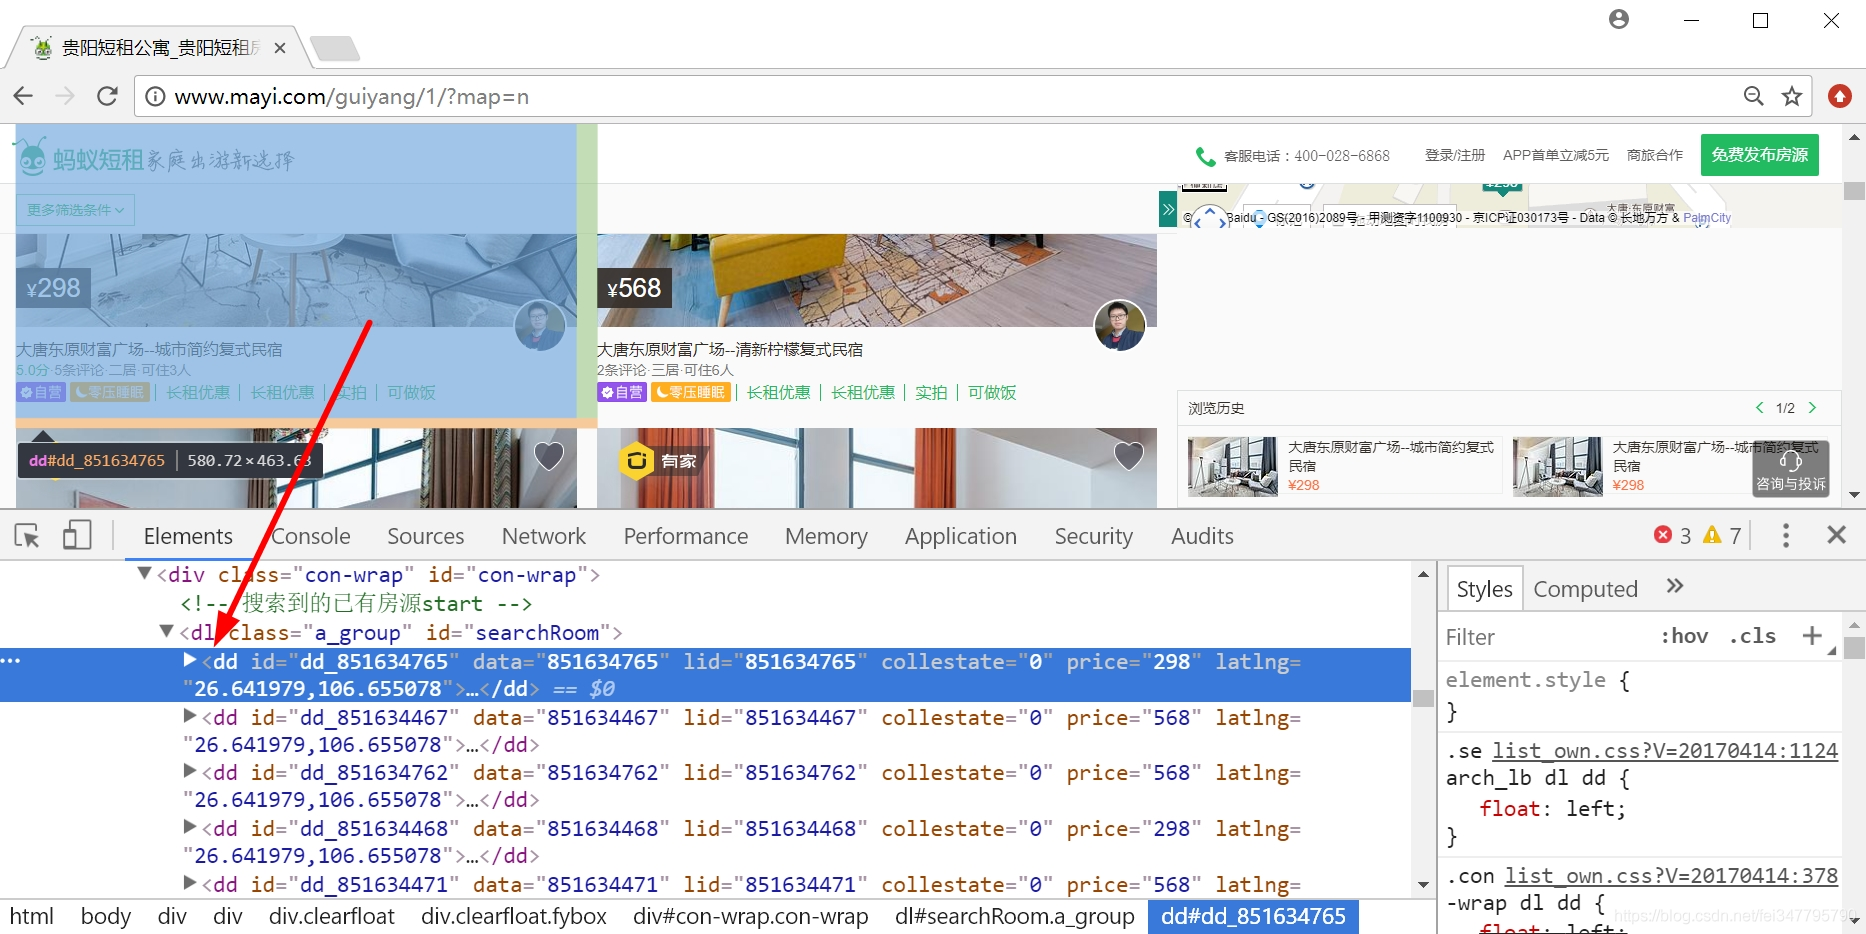 在定位房屋名称,如下图所示,位于<div class="room-detail clearfloat"></div>节点下。
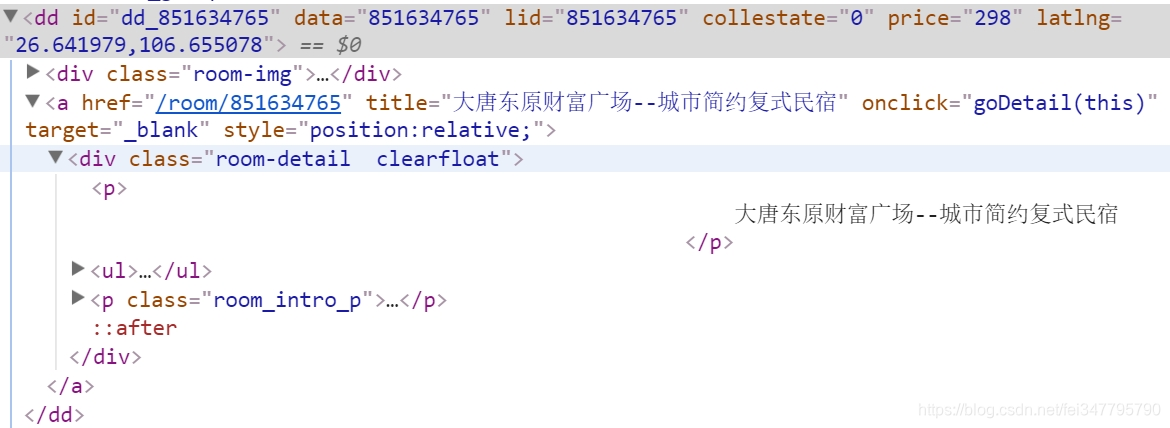
接下来我们写个简单的BeautifulSoup进行爬取。
 # -*- coding: utf-8 -*-

 import urllib

 import re

 from bs4 import BeautifulSoup

 import codecs

 url = 'http://www.mayi.com/guiyang/?map=no'

 response=urllib.urlopen(url)

 contents = response.read()

 soup = BeautifulSoup(contents, "html.parser")

 print soup.title

 print soup

 #短租房名称

 for tag in soup.find_all('dd'):

     for name in tag.find_all(attrs={"class":"room-detail clearfloat"}):

         fname = name.find('p').get_text()

         print u'[短租房名称]', fname.replace('\n','').strip()
但很遗憾,报错了,说明蚂蚁金服防范措施还是挺到位的。 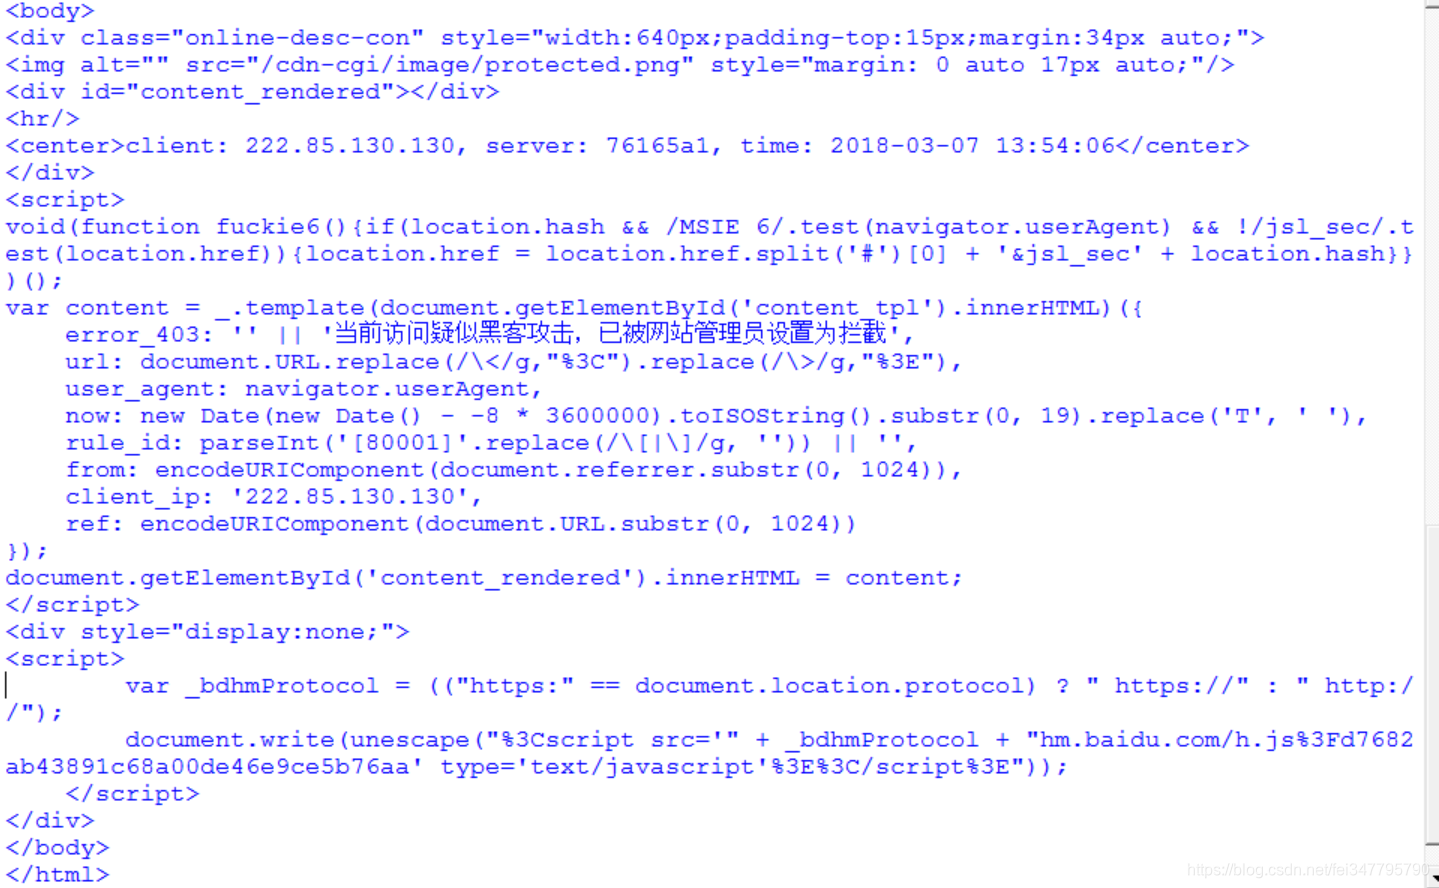
二. 设置Cookie的BeautifulSoup爬虫
添加消息头的代码如下所示,这里先给出代码和结果,再教大家如何获取Cookie。
 # -*- coding: utf-8 -*-

 import urllib2

 import re

 from bs4 import BeautifulSoup

 #爬虫函数

 def gydzf(url):

     user_agent="Mozilla/5.0 (Windows NT 10.0; Win64; x64) AppleWebKit/537.36 (KHTML, like Gecko) Chrome/51.0.2704.103 Safari/537.36"

     headers={"User-Agent":user_agent}

     request=urllib2.Request(url,headers=headers)

     response=urllib2.urlopen(request)

     contents = response.read()

     soup = BeautifulSoup(contents, "html.parser")

     for tag in soup.find_all('dd'):

         #短租房名称

         for name in tag.find_all(attrs={"class":"room-detail clearfloat"}):

             fname = name.find('p').get_text()

             print u'[短租房名称]', fname.replace('\n','').strip()

         #短租房价格

         for price in tag.find_all(attrs={"class":"moy-b"}):

             string = price.find('p').get_text()

             fprice = re.sub("[¥]+".decode("utf8"), "".decode("utf8"),string)

             fprice = fprice[0:5]

             print u'[短租房价格]', fprice.replace('\n','').strip()

             #评分及评论人数

             for score in name.find('ul'):

                 fscore = name.find('ul').get_text()

             print u'[短租房评分/评论/居住人数]', fscore.replace('\n','').strip()

             #网页链接url

             url_dzf = tag.find(attrs={"target":"_blank"})

             urls = url_dzf.attrs['href']

             print u'[网页链接]', urls.replace('\n','').strip()

             urlss = 'http://www.mayi.com' + urls + ''

             print urlss

 #主函数

 if __name__ == '__main__':

     i = 1

     while i<10:

         print u'页码', i

         url = 'http://www.mayi.com/guiyang/' + str(i) + '/?map=no'

         gydzf(url)

         i = i+1

     else:

         print u"结束"
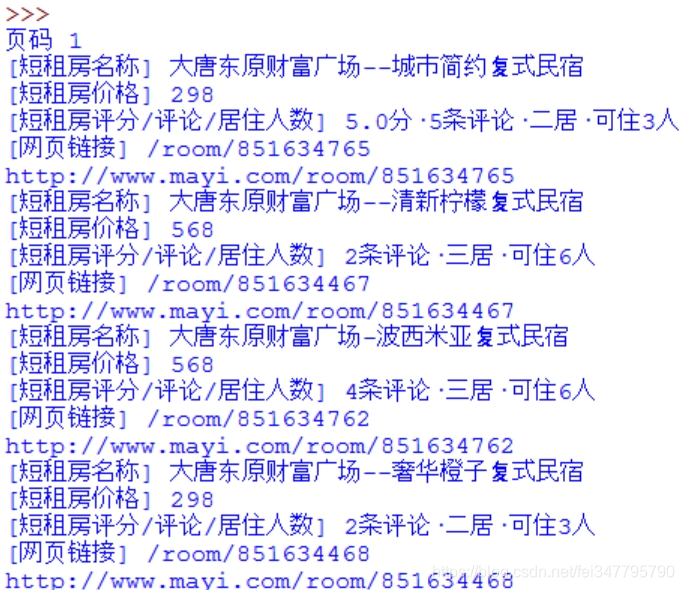
输出结果如下图所示:
 页码 1

 [短租房名称] 大唐东原财富广场--城市简约复式民宿

 [短租房价格] 298

 [短租房评分/评论/居住人数] 5.0分·5条评论·二居·可住3人

 [网页链接] /room/851634765

 http://www.mayi.com/room/851634765

 [短租房名称] 大唐东原财富广场--清新柠檬复式民宿

 [短租房价格] 568

 [短租房评分/评论/居住人数] 2条评论·三居·可住6人

 [网页链接] /room/851634467

 http://www.mayi.com/room/851634467

 ...

 页码 9

 [短租房名称] 【高铁北站公园旁】美式风情+超大舒适安逸

 [短租房价格] 366

 [短租房评分/评论/居住人数] 3条评论·二居·可住5人

 [网页链接] /room/851018852

 http://www.mayi.com/room/851018852

 [短租房名称] 大营坡(中大国际购物中心附近)北欧小清新三室

 [短租房价格] 298

 [短租房评分/评论/居住人数] 三居·可住6人

 [网页链接] /room/851647045

 http://www.mayi.com/room/851647045
接下来我们想获取详细信息 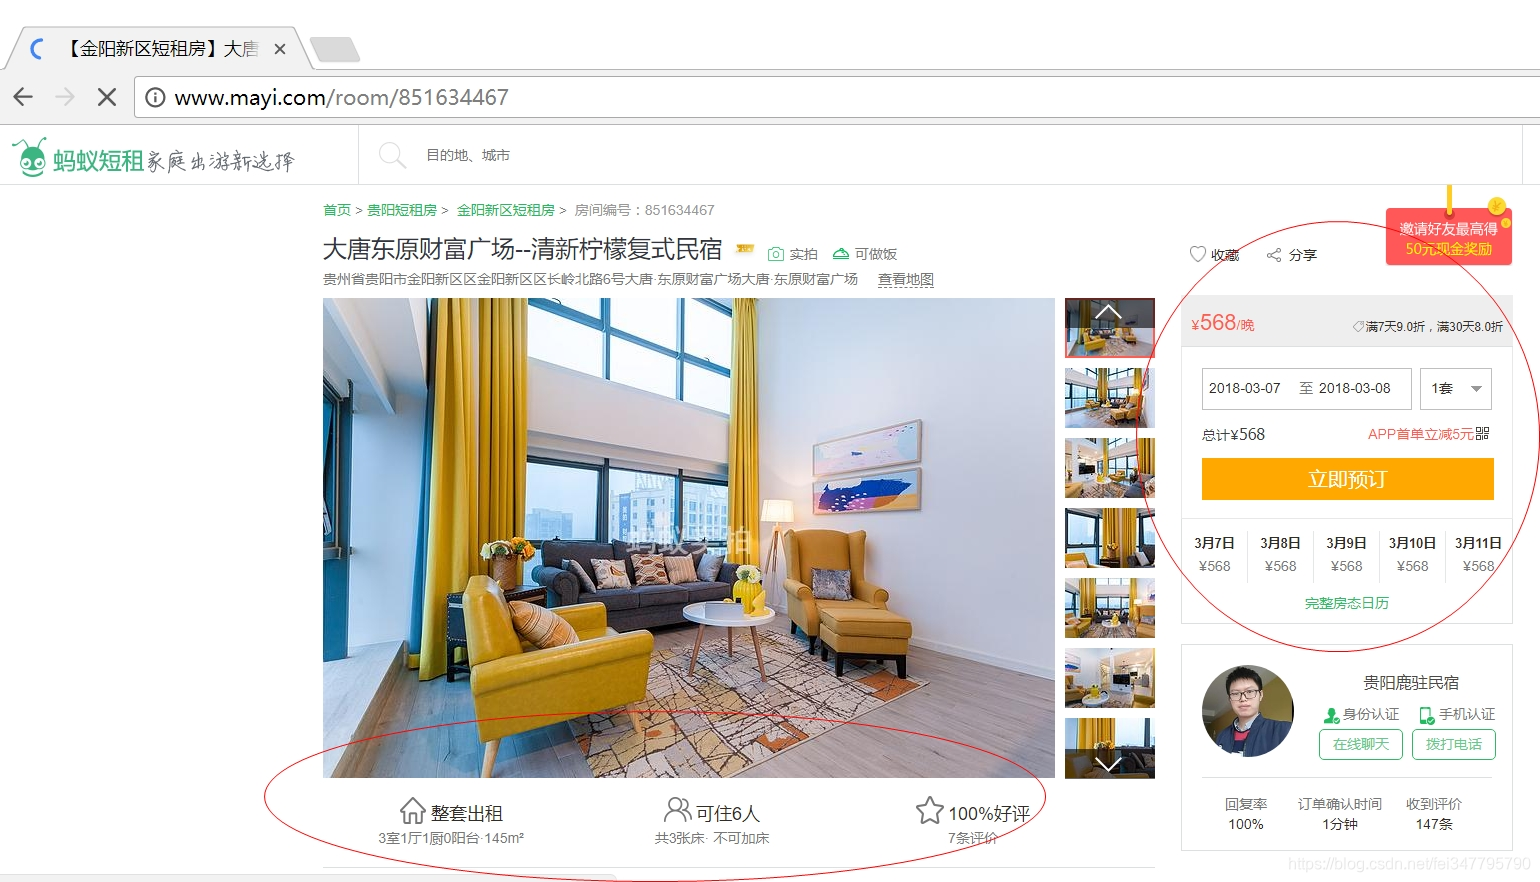
这里作者主要是提供分析Cookie的方法,使用浏览器打开网页,右键“检查”,然后再刷新网页。在“NetWork”中找到网页并点击,在弹出来的Headers中就隐藏这这些信息。 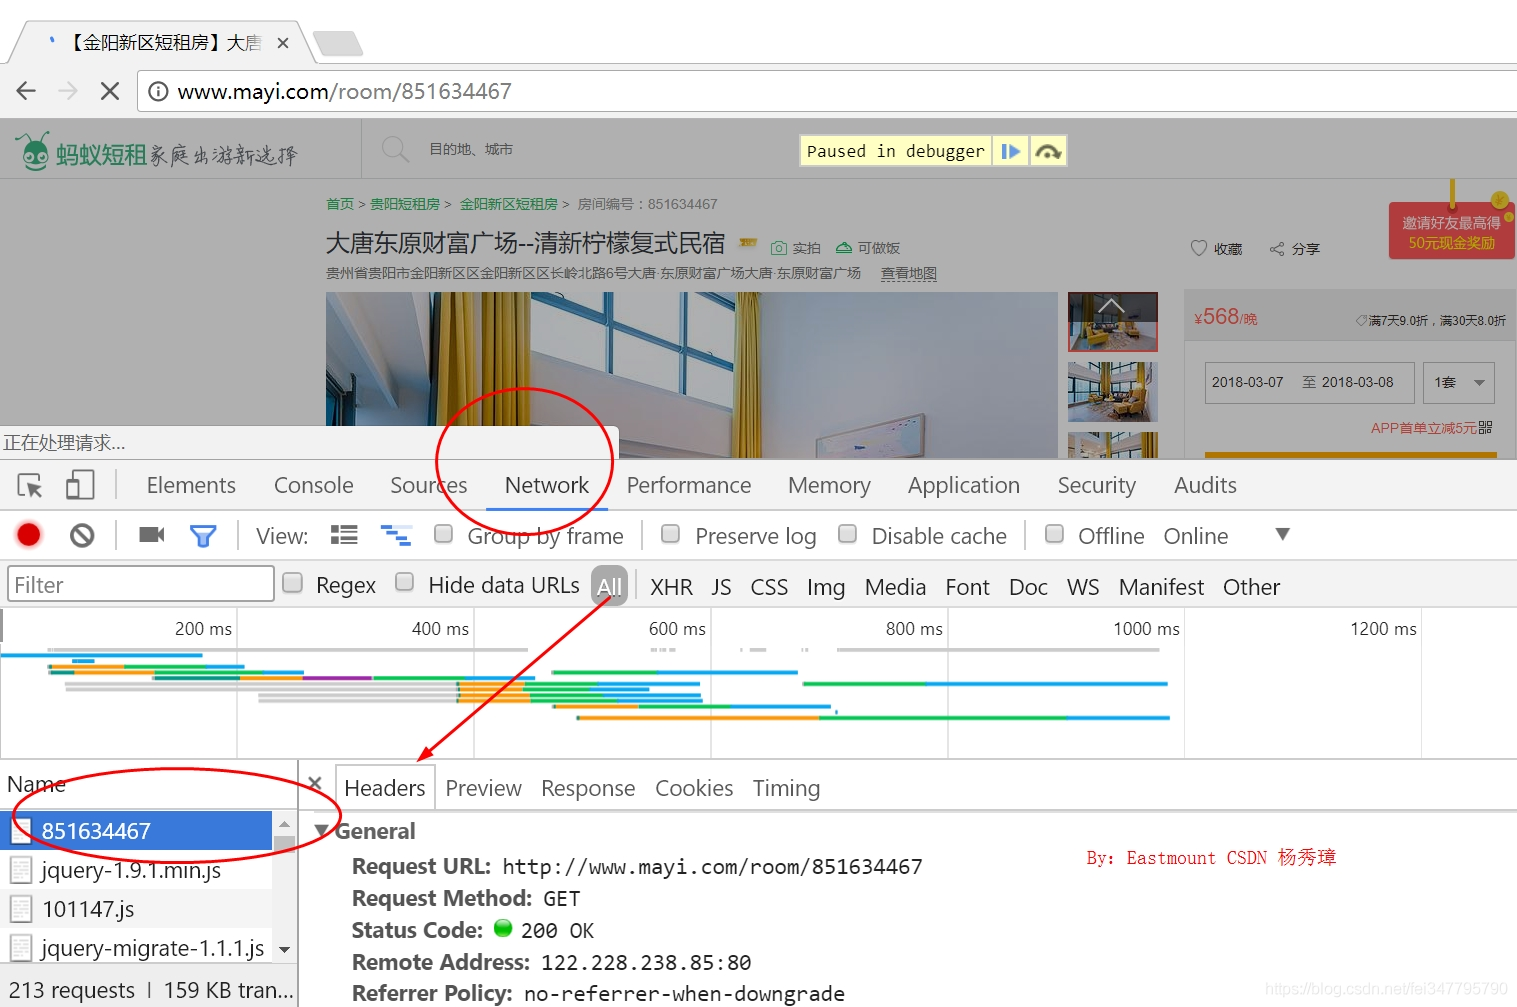
最常见的两个参数是Cookie和User-Agent,如下图所示:
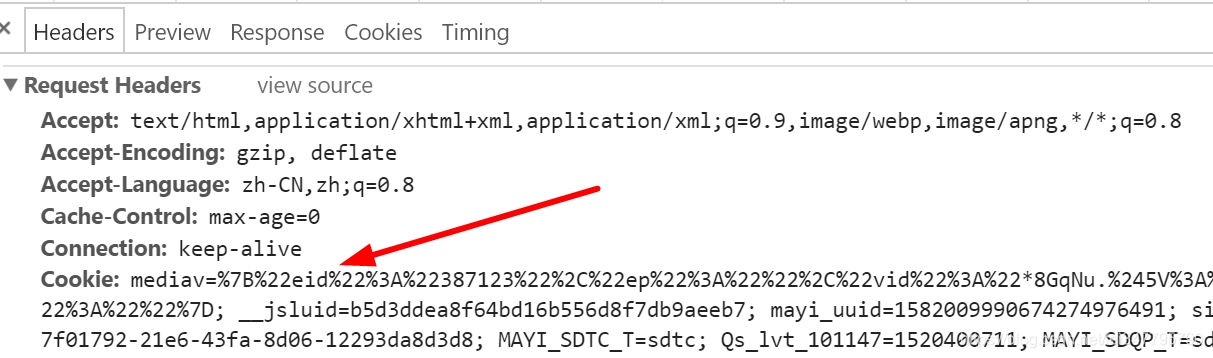
然后在Python代码中设置这些参数,再调用Urllib2.Request()提交请求即可,核心代码如下:
   user_agent="Mozilla/5.0 (Windows NT 10.0; Win64; x64) ... Chrome/61.0.3163.100 Safari/537.36"

   cookie="mediav=%7B%22eid%22%3A%22387123...b3574ef2-21b9-11e8-b39c-1bc4029c43b8"

   headers={"User-Agent":user_agent,"Cookie":cookie}

   request=urllib2.Request(url,headers=headers)

   response=urllib2.urlopen(request)

   contents = response.read()

   soup = BeautifulSoup(contents, "html.parser")

   for tag1 in soup.find_all(attrs={"class":"main"}):
注意,每小时Cookie会更新一次,我们需要手动修改Cookie值即可,就是上面代码的cookie变量和user_agent变量。完整代码如下所示:
 import urllib2

 import re

 from bs4 import BeautifulSoup

 import codecs

 import csv

 c = open("ycf.csv","wb") #write 写

 c.write(codecs.BOM_UTF8)

 writer = csv.writer(c)

 writer.writerow(["短租房名称","地址","价格","评分","可住人数","人均价格"])

 #爬取详细信息

 def getInfo(url,fname,fprice,fscore,users):

     #通过浏览器开发者模式查看访问使用的user_agent及cookie设置访问头(headers)避免反爬虫,且每隔一段时间运行要根据开发者中的cookie更改代码中的cookie

     user_agent="Mozilla/5.0 (Windows NT 10.0; Win64; x64) AppleWebKit/537.36 (KHTML, like Gecko) Chrome/61.0.3163.100 Safari/537.36"

     cookie="mediav=%7B%22eid%22%3A%22387123%22eb7; mayi_uuid=1582009990674274976491; sid=42200298656434922.85.130.130"

     headers={"User-Agent":user_agent,"Cookie":cookie}

     request=urllib2.Request(url,headers=headers)

     response=urllib2.urlopen(request)

     contents = response.read()

     soup = BeautifulSoup(contents, "html.parser")

     #短租房地址

     for tag1 in soup.find_all(attrs={"class":"main"}):

         print u'短租房地址:'

         for tag2 in tag1.find_all(attrs={"class":"desWord"}):

             address = tag2.find('p').get_text()

             print address

     #可住人数

         print u'可住人数:'

         for tag4 in tag1.find_all(attrs={"class":"w258"}):

             yy = tag4.find('span').get_text()

             print yy

         fname = fname.encode("utf-8")

         address = address.encode("utf-8")

         fprice = fprice.encode("utf-8")

         fscore = fscore.encode("utf-8")

         fpeople = yy[2:3].encode("utf-8")

         ones = int(float(fprice))/int(float(fpeople))

         #存储至本地

         writer.writerow([fname,address,fprice,fscore,fpeople,ones])

 #爬虫函数

 def gydzf(url):

     user_agent="Mozilla/5.0 (Windows NT 10.0; Win64; x64) AppleWebKit/537.36 (KHTML, like Gecko) Chrome/51.0.2704.103 Safari/537.36"

     headers={"User-Agent":user_agent}

     request=urllib2.Request(url,headers=headers)

     response=urllib2.urlopen(request)

     contents = response.read()

     soup = BeautifulSoup(contents, "html.parser")

     for tag in soup.find_all('dd'):

     #短租房名称

         for name in tag.find_all(attrs={"class":"room-detail clearfloat"}):

             fname = name.find('p').get_text()

             print u'[短租房名称]', fname.replace('\n','').strip()

     #短租房价格

         for price in tag.find_all(attrs={"class":"moy-b"}):

             string = price.find('p').get_text()

             fprice = re.sub("[¥]+".decode("utf8"), "".decode("utf8"),string)

             fprice = fprice[0:5]

             print u'[短租房价格]', fprice.replace('\n','').strip()

     #评分及评论人数

             for score in name.find('ul'):

                 fscore = name.find('ul').get_text()

             print u'[短租房评分/评论/居住人数]', fscore.replace('\n','').strip()

    #网页链接url

             url_dzf = tag.find(attrs={"target":"_blank"})

             urls = url_dzf.attrs['href']

             print u'[网页链接]', urls.replace('\n','').strip()

             urlss = 'http://www.mayi.com' + urls + ''

             print urlss

             getInfo(urlss,fname,fprice,fscore,user_agent)

 #主函数

 if __name__ == '__main__':

     i = 0

     while i<33:

         print u'页码', (i+1)

         if(i==0):

             url = 'http://www.mayi.com/guiyang/?map=no'

         if(i>0):

             num = i+2 #除了第一页是空的,第二页开始按2顺序递增

             url = 'http://www.mayi.com/guiyang/' + str(num) + '/?map=no'

         gydzf(url)

         i=i+1

 c.close()
输出结果如下,存储本地CSV文件:
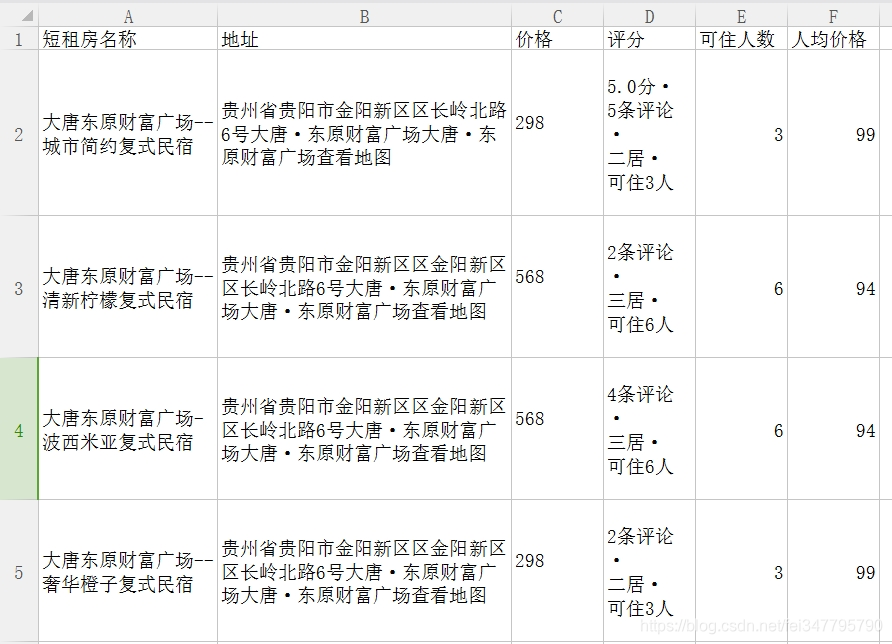
同时,大家可以尝试Selenium爬取蚂蚁短租,应该也是可行的方法。最后希望文章对您有所帮助,如果存在不足之处,请海涵~
Python爬虫:设置Cookie解决网站拦截并爬取蚂蚁短租的更多相关文章
- python爬虫11 | 这次,将带你爬取b站上的NBA形象大使蔡徐坤和他的球友们
在上一篇中 python爬虫10 | 网站维护人员:真的求求你们了,不要再来爬取了!! 小帅b给大家透露了我们这篇要说的牛逼利器 selenium + phantomjs 如果你看了 python爬虫 ...
- Python爬虫入门教程:豆瓣Top电影爬取
基本开发环境 Python 3.6 Pycharm 相关模块的使用 requests parsel csv 安装Python并添加到环境变量,pip安装需要的相关模块即可. 爬虫基本思路 一. ...
- python爬虫实战(六)--------新浪微博(爬取微博帐号所发内容,不爬取历史内容)
相关代码已经修改调试成功----2017-4-13 详情代码请移步我的github:https://github.com/pujinxiao/sina_spider 一.说明 1.目标网址:新浪微博 ...
- python爬虫中文乱码问题(request方式爬取)
https://blog.csdn.net/guoxinian/article/details/83047746 req = requests.get(url)返回的是类对象 其包括的属性有: r ...
- python爬虫---CrawlSpider实现的全站数据的爬取,分布式,增量式,所有的反爬机制
CrawlSpider实现的全站数据的爬取 新建一个工程 cd 工程 创建爬虫文件:scrapy genspider -t crawl spiderName www.xxx.com 连接提取器Link ...
- Python爬虫:用BeautifulSoup进行NBA数据爬取
爬虫主要就是要过滤掉网页中没用的信息.抓取网页中实用的信息 一般的爬虫架构为: 在python爬虫之前先要对网页的结构知识有一定的了解.如网页的标签,网页的语言等知识,推荐去W3School: W3s ...
- Python爬虫与一汽项目【二】爬取中国东方电气集中采购平台
网站地址:https://srm.dongfang.com/bid_detail.screen 东方电气采购的页面看似很友好,实际上并不好爬取 在观察网页的审查元素之后发现,1处的网页响应只是单纯的一 ...
- python爬虫学习(三):使用re库爬取"淘宝商品",并把结果写进txt文件
第二个例子是使用requests库+re库爬取淘宝搜索商品页面的商品信息 (1)分析网页源码 打开淘宝,输入关键字“python”,然后搜索,显示如下搜索结果 从url连接中可以得到搜索商品的关键字是 ...
- PYTHON 爬虫笔记九:利用Ajax+正则表达式+BeautifulSoup爬取今日头条街拍图集(实战项目二)
利用Ajax+正则表达式+BeautifulSoup爬取今日头条街拍图集 目标站点分析 今日头条这类的网站制作,从数据形式,CSS样式都是通过数据接口的样式来决定的,所以它的抓取方法和其他网页的抓取方 ...
随机推荐
- C - Train Problem II——卡特兰数
题目链接_HDU-1023 题目 As we all know the Train Problem I, the boss of the Ignatius Train Station want to ...
- C#属性方法 构造函数(不知道自己理解的对不对)
using System; namespace test { class Program { static void Main(string[] args) { Cat kitty = new Cat ...
- RDIFramework.NET ━ .NET敏捷开发框架全新发布-最好用的.NET开发框架 100%源码授权
RDIFramework.NET,基于.NET的快速信息化系统敏捷开发框架.10年沉淀.历经上千项目检验,致力于企业智能化开发,帮助提升软件开发效率.最好用的.NET开发框架,100%源码授权. 1. ...
- 中间人攻击,HTTPS也可以被碾压
摘要: 当年12306竟然要自己安装证书... 原文:知道所有道理,真的可以为所欲为 公众号:可乐 Fundebug经授权转载,版权归原作者所有. 一.什么是MITM 中间人攻击(man-in-the ...
- PHP 部分语法(二)
array() 创建数组: 1.数值数组:带数字 ID 键的数组 2.关联数组:带有指定键的数组,键关联一个值 3.多维数组:包含一个或多个数组的数组 $arr = array("Hello ...
- MySQL数据篇(八)-- 存储过程的简单实现
思考:一般我们的数据都是存储在数据库里面,对于常规的CRUD操作都是用代码实现,比如使用PHP做项目,所有的数据处理都需要主动操作代码实现.如果我们现在有一项目,业务需要在用户下单后,对用户的订单进行 ...
- Visual Studio Code管理MySQL
1. VS Code安装插件:MySQL , 安装完毕重新加载即可激活 2. 连接 mysql 3. 断开连接mysql 4. 简单操作 查看字段 新建查询语句 显示表结构 插入数据
- Codeforces Round #598 (Div. 3)
传送门 A. Payment Without Change 签到. Code /* * Author: heyuhhh * Created Time: 2019/11/4 21:19:19 */ #i ...
- 题解:SPOJ1026 Favorite Dice
原题链接 题目大意 给你一个n个面的骰子,每个面朝上的几率相等,问每个面都被甩到的期望次数 题解 典型的赠券收集问题. 我们考虑当你手上已有\(i\)种不同的数,从集合中任选一个数得到新数的概率,为\ ...
- python爬虫初认识
一.爬虫是什么? 如果我们把互联网比作一张大的蜘蛛网,数据便是存放于蜘蛛网的各个节点,而爬虫就是一只小蜘蛛, 沿着网络抓取自己的猎物(数据)爬虫指的是:向网站发起请求,获取资源后分析并提取有用数据的程 ...