
Transformers for Graph Representation
Do Transformers Really Perform Badfor Graph Representation?
1 Introduction
作者们发现关键问题在于如何补回Transformer模型的自注意力层丢失掉的图结构信息!不同于序列数据(NLP, Speech)或网格数据(CV),图的结构信息是图数据特有的属性,且对图的性质预测起着重要的作用。
There are many attempts of leveraging Transformer into the graph domain, but the only effective way is replacing some key modules (e.g., feature aggregation) in classic GNN variants by the softmax attention[47,7,22,48,58,43,13]
- [47] Graph attention networks. ICLR, 2018.
- [7] Graph transformer for graph-to-sequence learning. In Proceedings of the AAAI Conference on Artificial Intelligence, volume 34, pages 7464–7471, 2020.
- [22] Heterogeneous graph transformer. In Proceedings of The Web Conference 2020, pages 2704–2710, 2020.
- [48] Direct multi-hop attention based graph neural network.arXiv preprint arXiv:2009.14332, 2020.
- [58] Graph-bert: Only attention is needed forlearning graph representations.arXiv preprint arXiv:2001.05140, 2020.
- [43] Self-supervised graph transformer on large-scale molecular data. Advances in Neural Information ProcessingSystems, 33, 2020.
- [13] generalization of transformer networks to graphs. AAAI Workshop on Deep Learning on Graphs: Methods and Applications, 2021
- Centrality Encoding: capture the node importance in the graph. In particular, we leverage the degree centrality for the centrality encoding, where a learnable vectoris assigned to each node according to its degree and added to the node features in the input layer.
- Spatial Encoding: capture the structural relation between nodes.
- Edge Encoding
2 Graphormer
2.1 Structural Encodings in Graphormer
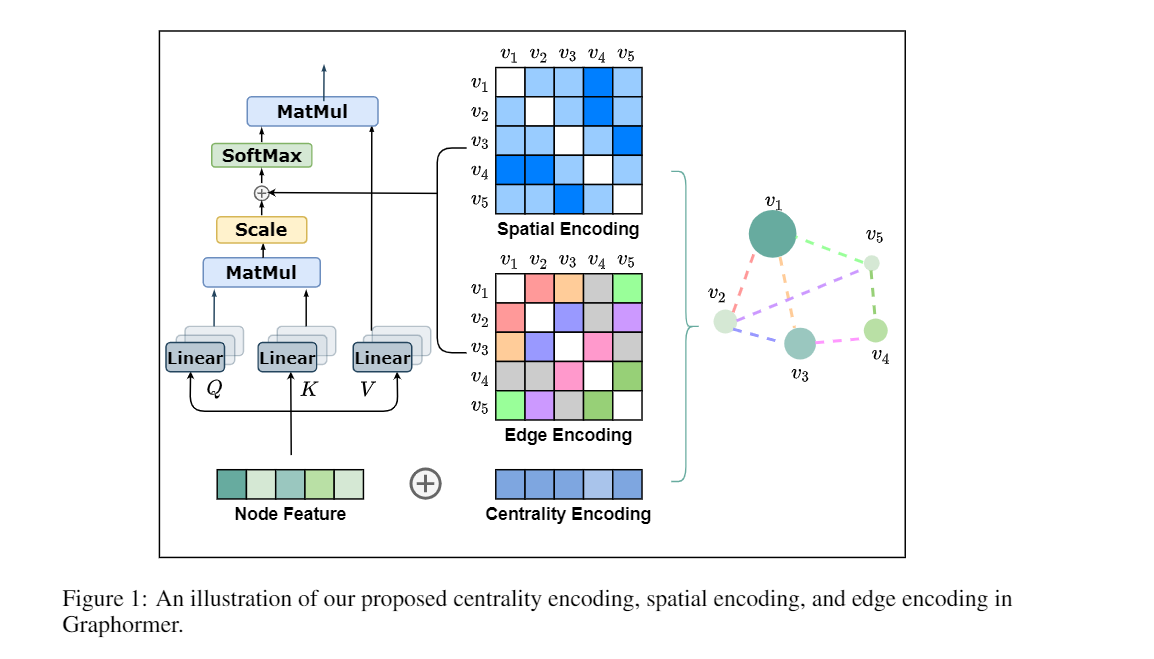
2.1.1 a Centrality Encoding
In Graphormer, we use the degree centrality, which is one of the standard centrality measures inliterature, as an additional signal to the neural network. To be specific, we develop a Centrality Encoding which assigns each node two real-valued embedding vectors according to its indegree and outdegree.
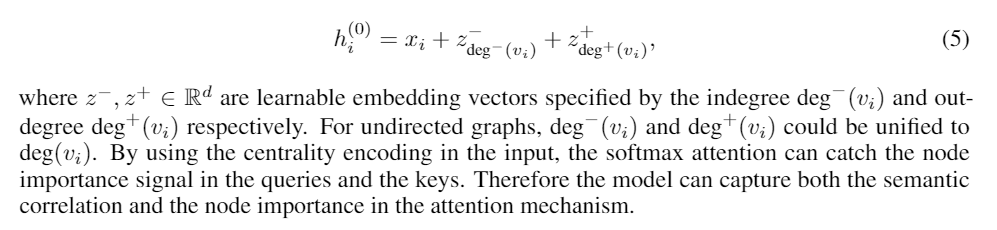
2.1.2 a Centrality Encoding
An advantage of Transformer is its global receptive field.
Spatial Encoding:
In this paper, we choose φ(vi,vj) to be the distance of the shortest path (SPD) between vi and vj if the two nodes are connected. If not, we set the output ofφto be a special value, i.e., -1. We assign each (feasible) output value a learnable scalar which will serve as a bias term in the self-attention module. Denote Aij as the (i,j)-element of the Query-Key product matrix A, we have:
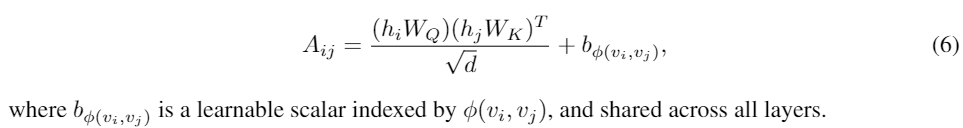
2.1.3 Edge Encoding in the Attention
In many graph tasks, edges also have structural features.
In the first method, the edge features areadded to the associated nodes’ features [21,29].
- [21] Open graph benchmark: Datasets for machine learning on graphs.arXiv preprintarXiv:2005.00687, 2020.
- [29] Deepergcn: All you need to train deepergcns.arXiv preprint arXiv:2006.07739, 2020
In the second method, for each node, its associated edges’ features will be used together with the node features in the aggregation [15,51,25].
- [51] How powerful are graph neural networks?InInternational Conference on Learning Representations, 2019.
- [25] Semi-supervised classification with graph convolutional networks.arXiv preprint arXiv:1609.02907, 2016
However, such ways of using edge feature only propagate the edge information to its associated nodes, which may not be an effective way to leverage edge information in representation of the whole graph.
a new edge encoding method in Graphormer:
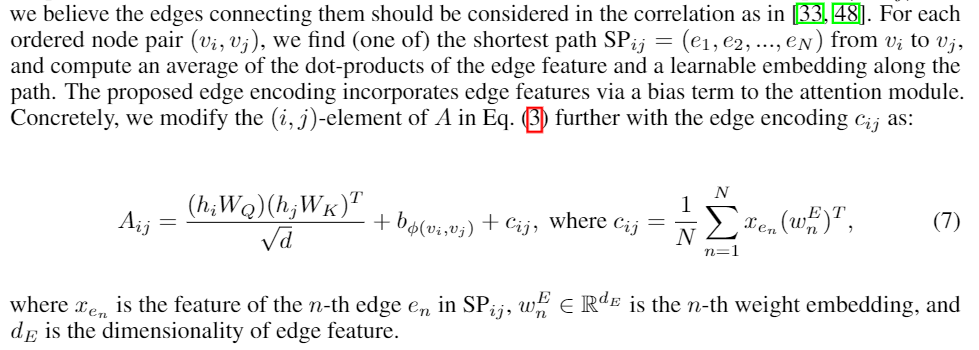
3.2 Implementation Details of Graphormer
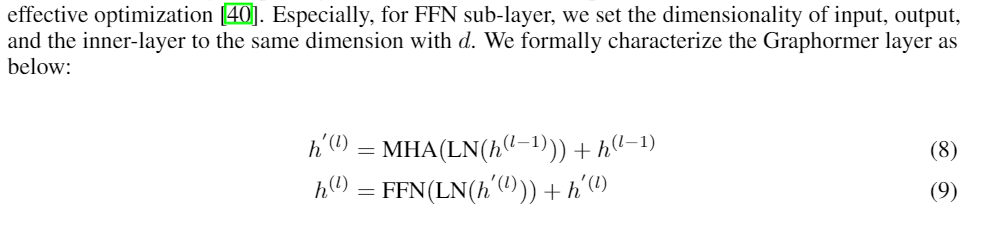
Graphormer Layer:
- MHA: multi-head self-attention (MHA)
- FFN: the feed-forward blocks
- LN: the layer normalization
Special Node:
生成一个VNODE连接图中所有的点,而它与所有节点的 spatial encodings 是 a distinct learnable scalar
3 Experiments
3.1 OGB Large-Scale Challenge
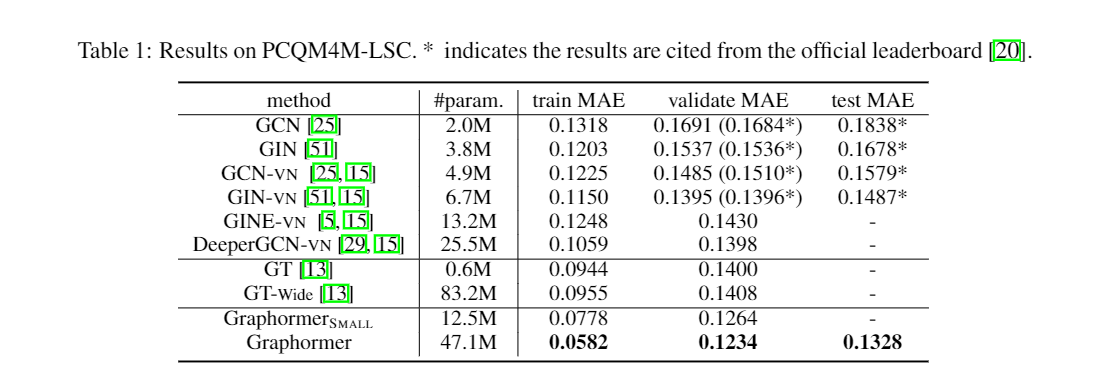
3.2 Graph Representation

Transformers for Graph Representation的更多相关文章
- 论文解读(Graphormer)《Do Transformers Really Perform Bad for Graph Representation?》
论文信息 论文标题:Do Transformers Really Perform Bad for Graph Representation?论文作者:Chengxuan Ying, Tianle Ca ...
- 论文解读GALA《Symmetric Graph Convolutional Autoencoder for Unsupervised Graph Representation Learning》
论文信息 Title:<Symmetric Graph Convolutional Autoencoder for Unsupervised Graph Representation Learn ...
- 论文解读(SUGRL)《Simple Unsupervised Graph Representation Learning》
Paper Information Title:Simple Unsupervised Graph Representation LearningAuthors: Yujie Mo.Liang Pen ...
- 论文解读(GMI)《Graph Representation Learning via Graphical Mutual Information Maximization》2
Paper Information 论文作者:Zhen Peng.Wenbing Huang.Minnan Luo.Q. Zheng.Yu Rong.Tingyang Xu.Junzhou Huang ...
- 论文解读(GMI)《Graph Representation Learning via Graphical Mutual Information Maximization》
Paper Information 论文作者:Zhen Peng.Wenbing Huang.Minnan Luo.Q. Zheng.Yu Rong.Tingyang Xu.Junzhou Huang ...
- 论文解读(GRCCA)《 Graph Representation Learning via Contrasting Cluster Assignments》
论文信息 论文标题:Graph Representation Learning via Contrasting Cluster Assignments论文作者:Chun-Yang Zhang, Hon ...
- 论文解读(MERIT)《Multi-Scale Contrastive Siamese Networks for Self-Supervised Graph Representation Learning》
论文信息 论文标题:Multi-Scale Contrastive Siamese Networks for Self-Supervised Graph Representation Learning ...
- 论文解读(SUBG-CON)《Sub-graph Contrast for Scalable Self-Supervised Graph Representation Learning》
论文信息 论文标题:Sub-graph Contrast for Scalable Self-Supervised Graph Representation Learning论文作者:Yizhu Ji ...
- 论文阅读 Dynamic Graph Representation Learning Via Self-Attention Networks
4 Dynamic Graph Representation Learning Via Self-Attention Networks link:https://arxiv.org/abs/1812. ...
随机推荐
- spring-boot-maven-plugin not found的解决方案
spring-boot-maven-plugin not found 在maven测试的生命周期都没有错,但是就是爆红 参考了很多的链接,没有成功解决,最后得到真正有帮助的方法,添加springboo ...
- java之泛型的使用
在java中,普通的类和方法只能用具体的类型,这对代码的限制很大,代码的可重用性大大降低. 那么如何才能让同一个类和方法使用不同类型的对象呢?在接触泛型之前我们可能会想到通过类型转换的方法来实现. p ...
- 你管这破玩意叫CPU?
每次回家开灯时你有没有想过,用你按的开关实际上能打造出 复杂的 CPU来,只不过需要的数量可能比较多,也就几十亿个吧. 伟大的发明 过去200年人类最重要的发明是什么?蒸汽机?电灯?火箭?这些可能都不 ...
- (9)MySQL进阶篇SQL优化(InnoDB锁-记录锁)
1.概述 InnoDB行锁是通过给索引上的索引项加锁来实现的,这一点MySQL与Oracle不同,后者是通过在数据块中对相应数据行加锁来实现的.InnoDB这种行锁实现特点意味着:只有通过索引条件检索 ...
- X264码率控制总结1——ABR,CQP,CRF
1. X264显式支持的一趟码率控制方法有:ABR, CQP, CRF. 缺省方法是CRF.这三种方式的优先级是ABR > CQP > CRF. if ( bitrate ) rc_me ...
- matlab添加当前路径下的所有子目录
% 添加当前路径下的所有子目录addpath(genpath(pwd));
- 笔记·RCNN系相关
这篇博客总述了从RCNN到Mask RCNN的发展过程 https://blog.csdn.net/heavenpeien/article/details/80534963 简单的说,Fast RCN ...
- 克鲁斯卡尔(Kruskal)算法
概览 相比于普里姆算法(Prim算法),克鲁斯卡尔算法直接以边为目标去构建最小生成树.从按权值由小到大排好序的边集合{E}中逐个寻找权值最小的边来构建最小生成树,只要构建时,不会形成环路即可保证当边集 ...
- Can’t update table ‘xxx’ in stored function/trigger because it is already used by statement which invoked this stored function/trigger
MySQL: Solution for ERROR 1442 (HY000): Can't update table 'xxx' in stored function/trigger because ...
- [bug] httpd服务启动问题
参考 httpd服务器启动失败 https://www.cnblogs.com/Crazy-Liu/p/11550824.html Apache-httpd服务器启动成功网页却不能访问 https:/ ...