
Visual Question Answering with Memory-Augmented Networks
Visual Question Answering with Memory-Augmented Networks
2018-05-15 20:15:03
Motivation:
虽然 VQA 已经取得了很大的进步,但是这种方法依然对完全 general,freeform VQA 表现很差,作者认为是因为如下两点:
1. deep models trained with gradient based methods learn to respond to the majority of training data rather than specific scarce exemplars ;
用梯度下降的方法训练得到的深度模型,对主要的训练数据有较好的相应,但是对特定的稀疏样本却不是;
2. existing VQA systems learn about the properties of objects from question-answer pairs, sometimes indepently of the image.
选择性的关注图像中的某些区域是很重要的策略。
我们从最近的 memory-augmented neural networks 以及 co-attention mechanism 得到启发,本文中,我们利用 memory-networks 来记忆 rare events,然后用 memory-augmented networks with attention to rare answers for VQA.

The Proposed Algorithm :
本文的算法流程如上图所示,首先利用 embedding 的方法,提取问题和图像的 feature,然后进行 co-attention 的学习,然后将两个加权后的feature进行组合,然后输入到 memory network 中,最终进行答案的选择。
Image Embedding:用 pre-trained model 进行特征的提取;
Question Embedding:用双向 LSTM 网络进行语言特征的学习;
Sequential Co-attention:
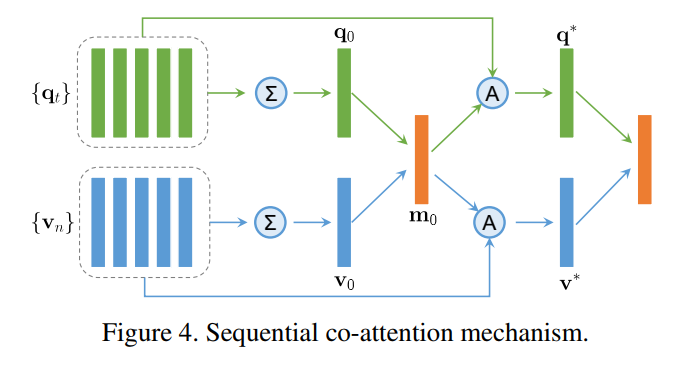
这里的协同 attention 机制,考虑到图像和文本共同的特征,相互影响,得到共同的注意力机制。我们根据 视觉特征和语言特征的平均值,进行点乘,得到一个 base vector m0 :
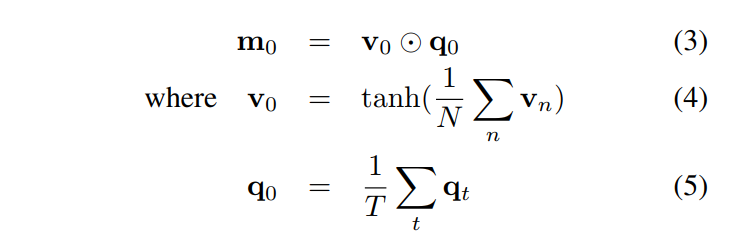
我们用一个两层的神经网络进行 soft attention 的计算。对于 visual attention,the soft attention 以及 加权后的视觉特征向量分别为:
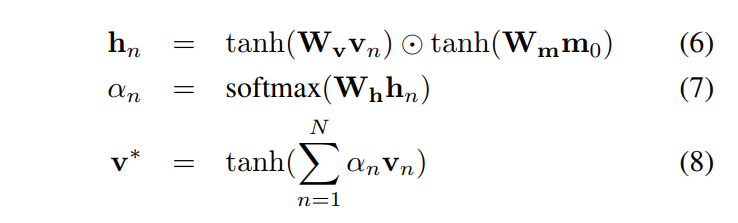
其中 Wv, Wm,Wh 都表示 hidden states。类似的,我们计算加权后的问题特征向量,如下:
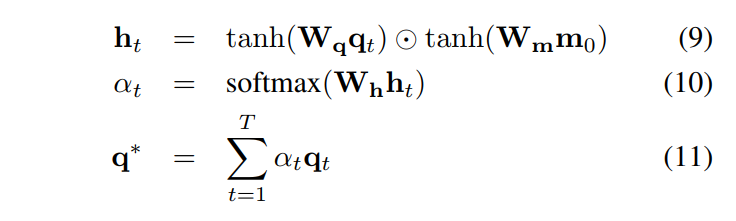
我们将加权后的 v 和 q 组合,用来表示输入图像和问题对,图4,展示了 co-attention 机制的整个过程。
Memory Augmented Network:
The RNNs lack external memory to maintain a long-term memory for scarce training data. This paper use a memory-augmented NN for VQA.
特别的,我们采用了标准的 LSTM 模型作为 controller,起作用是 receives input data,然后跟外部记忆模块进行交互。外部记忆,Mt,是有一系列的 row vectors 作为 memory slots。
xt 代表的是视觉特征和文本特征的组合;yt 是对应的编码的问题答案(one-hot encoded answer vector)。然后将该 xt 输入到 LSTM controller,如:
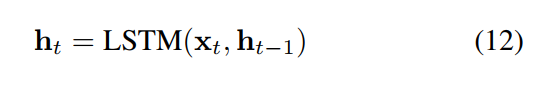
对于从外部记忆单元中读取,我们将 the hidden state ht 作为 Mt 的 query。首先,我们计算 搜索向量 ht 和 记忆中每一行的余弦距离:
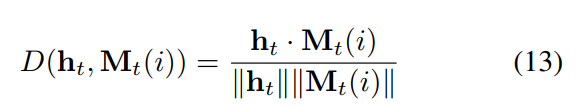
然后,我们通过 the cosine distance 用 softmax 计算一个 read weight vector wr:
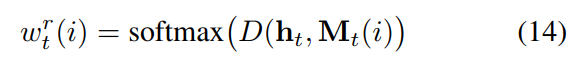
有这些 read-weights, 一个新的检索的记忆 rt 可以通过下面的式子得到:
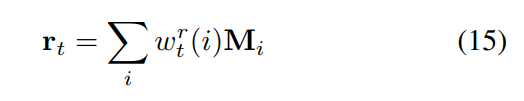
最后,我们将 the new memory vector rt 和 controller hidden state ht 组合,然后产生 the output vector ot for learning classifier.
我们采用 the usage weights wu 来控制写入到 memory。我们通过衰减之前的 state 来更新 the usage weights :
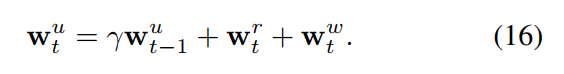
为了计算 the write weights,我们引入一个截断机制 来更新 the least-used positions。此处,我们采用 m(v, n) 来表示 the n-th smallest element of a vector v. 我们采用 a learnable sigmoid gate parameter 来计算之前的 read weights 和 usage weights 的 convex combination:
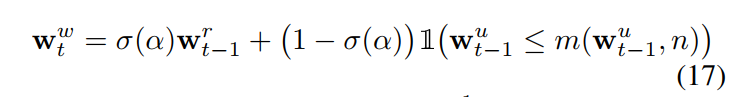
A larger n results in maintaining a longer term of memory of scarce training data. 跟 LSTM 内部的记忆单元相比,这里的两个参数都可以用来调整 the rate of writing to exernal memory. 这给我们更多的自由来调整模型的更新。公式(12)中输出的隐层状态 ht 可以根据 the write weights 写入到 memory 中:
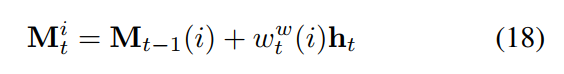
Answer Reasoning:
有了 the hidden state ht 以及 那个外部记忆单元中得到的 the reading memory rt,我们将这两个组合起来,作为当前问题和图片的表达,输入到分类网络中,然后得到答案的分布。
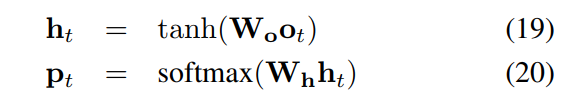
--- Done !
Visual Question Answering with Memory-Augmented Networks的更多相关文章
- 论文笔记:Visual Question Answering as a Meta Learning Task
Visual Question Answering as a Meta Learning Task ECCV 2018 2018-09-13 19:58:08 Paper: http://openac ...
- Hierarchical Question-Image Co-Attention for Visual Question Answering
Hierarchical Question-Image Co-Attention for Visual Question Answering NIPS 2016 Paper: https://arxi ...
- 【自然语言处理】--视觉问答(Visual Question Answering,VQA)从初始到应用
一.前述 视觉问答(Visual Question Answering,VQA),是一种涉及计算机视觉和自然语言处理的学习任务.这一任务的定义如下: A VQA system takes as inp ...
- 论文阅读:Learning Visual Question Answering by Bootstrapping Hard Attention
Learning Visual Question Answering by Bootstrapping Hard Attention Google DeepMind ECCV-2018 2018 ...
- Learning Conditioned Graph Structures for Interpretable Visual Question Answering
Learning Conditioned Graph Structures for Interpretable Visual Question Answering 2019-05-29 00:29:4 ...
- 第八讲_图像问答Image Question Answering
第八讲_图像问答Image Question Answering 课程结构 图像问答的描述 具备一系列AI能力:细分识别,物体检测,动作识别,常识推理,知识库推理..... 先要根据问题,判断什么任务 ...
- 论文:Bottom-Up and Top-Down Attention for Image Captioning and Visual Question Answering-阅读总结
Bottom-Up and Top-Down Attention for Image Captioning and Visual Question Answering-阅读总结 笔记不能简单的抄写文中 ...
- 论文笔记:Heterogeneous Memory Enhanced Multimodal Attention Model for Video Question Answering
Heterogeneous Memory Enhanced Multimodal Attention Model for Video Question Answering 2019-04-25 21: ...
- SalGAN: Visual saliency prediction with generative adversarial networks
SalGAN: Visual saliency prediction with generative adversarial networks 2017-03-17 摘要:本文引入了对抗网络的对抗训练 ...
随机推荐
- jQuery属性--attr(name|properties|key,value|fn)和removeAttr(name)
attr(name|properties|key,value|fn) 概述 设置或返回被选元素的属性值 参数 key,function(index, attr) 1:属性名称:2:返回 ...
- MVC请求管道
下面是请求管道中的19个事件. (1)BeginRequest: 开始处理请求 (2)AuthenticateRequest授权验证请求,获取用户授权信息 (3):PostAuthenticateRe ...
- Lua语言特色
[1]多重赋值 多重赋值规则:若值的个数少于变量的个数,那么多余的变量会被赋值为nil 若值的个数多余变量的个数,那么多余的值会被“悄悄地”丢弃掉. 多重赋值应用示例: a, b = , * prin ...
- wrapper class (Integer 为例)
1,导入 Integer a = 100; Integer b = 100; Integer c = 150; Integer d = 150; a == b; true c == d; false ...
- 关于Weex你需要知道的一切
QCon第一天,GMTC全球移动技术大会联席主席.手淘技术老大庄卓然(花名南天)在Keynote上宣布跨平台开发框架Weex开始内测,并将于6月份开源,同时他们也放出官网:http://alibaba ...
- read 命令详解
read 命令从标准输入中读取一行,并把输入行的每个字段的值指定给 shell 变量 语法选项 -p read –p “提示语句”,则屏幕就会输出提示语句,等待输入,并将输入存储在REPLY中 -n ...
- <转>jmeter(四)HTTP请求
本博客转载自:http://www.cnblogs.com/imyalost/category/846346.html 个人感觉不错,对jmeter讲解非常详细,担心以后找不到了,所以转发出来,留着慢 ...
- linux下的ifconfig命令
ifconfig工具不仅可以被用来简单地获取网络接口配置信息,还可以修改这些配置. 1.命令格式: ifconfig [网络设备] [参数] 2.命令功能: ifconfig 命令用来查看和配置网络设 ...
- Linux环境jdk的安装
1.下载jdk1.7,oracle的下载地址已经失效,找了个其他的地址进行下载. wget http://pc.xzstatic.com/2017/03/jdk7u79linuxx64.tar.gz ...
- 安装PHP扩展32位与64位的误区(x86与x64的查看)
在安装PHP扩展(DLL,SO),除了需要对应的PHP版本外,在WINDOWS还需要区分(TS线程,NTS非线程),如何判断呢? 1.如何判断是NTS还是TS(WINDOWS用户) 看PHP所在目录中 ...