
吴裕雄 python 机器学习——混合高斯聚类GMM模型
import numpy as np

import matplotlib.pyplot as plt

from sklearn import mixture

from sklearn.metrics import adjusted_rand_score

from sklearn.datasets.samples_generator import make_blobs

def create_data(centers,num=100,std=0.7):

    X, labels_true = make_blobs(n_samples=num, centers=centers, cluster_std=std)

    return  X,labels_true

#混合高斯聚类GMM模型

def test_GMM(*data):

    X,labels_true=data

    clst=mixture.GaussianMixture()

    clst.fit(X)

    predicted_labels=clst.predict(X)

    print("ARI:%s"% adjusted_rand_score(labels_true,predicted_labels))

# 用于产生聚类的中心点

centers=[[1,1],[2,2],[1,2],[10,20]]

# 产生用于聚类的数据集

X,labels_true=create_data(centers,1000,0.5)

#  调用 test_GMM 函数

test_GMM(X,labels_true)

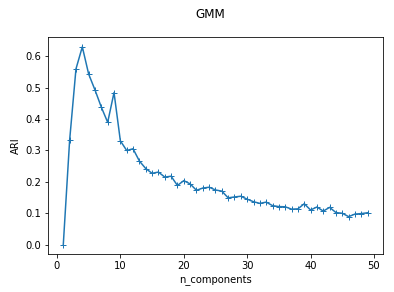
def test_GMM_n_components(*data):

    '''

    测试 GMM 的聚类结果随 n_components 参数的影响

    '''

    X,labels_true=data

    nums=range(1,50)

    ARIs=[]

    for num in nums:

        clst=mixture.GaussianMixture(n_components=num)

        clst.fit(X)

        predicted_labels=clst.predict(X)

        ARIs.append(adjusted_rand_score(labels_true,predicted_labels))

    ## 绘图

    fig=plt.figure()

    ax=fig.add_subplot(1,1,1)

    ax.plot(nums,ARIs,marker="+")

    ax.set_xlabel("n_components")

    ax.set_ylabel("ARI")

    fig.suptitle("GMM")

    plt.show()

#  调用 test_GMM_n_components 函数

test_GMM_n_components(X,labels_true)
def test_GMM_cov_type(*data):

    '''

    测试 GMM 的聚类结果随协方差类型的影响

    '''

    X,labels_true=data

    nums=range(1,50)

    cov_types=['spherical','tied','diag','full']

    markers="+o*s"

    fig=plt.figure()

    ax=fig.add_subplot(1,1,1)

    for i ,cov_type in enumerate(cov_types):

        ARIs=[]

        for num in nums:

            clst=mixture.GaussianMixture(n_components=num,covariance_type=cov_type)

            clst.fit(X)

            predicted_labels=clst.predict(X)

            ARIs.append(adjusted_rand_score(labels_true,predicted_labels))

        ax.plot(nums,ARIs,marker=markers[i],label="covariance_type:%s"%cov_type)

    ax.set_xlabel("n_components")

    ax.legend(loc="best")

    ax.set_ylabel("ARI")

    fig.suptitle("GMM")

    plt.show()

#  调用 test_GMM_cov_type 函数

test_GMM_cov_type(X,labels_true)

吴裕雄 python 机器学习——混合高斯聚类GMM模型的更多相关文章
- 吴裕雄 python 机器学习——K均值聚类KMeans模型
import numpy as np import matplotlib.pyplot as plt from sklearn import cluster from sklearn.metrics ...
- 吴裕雄 python 机器学习——超大规模数据集降维IncrementalPCA模型
# -*- coding: utf-8 -*- import numpy as np import matplotlib.pyplot as plt from sklearn import datas ...
- 吴裕雄 python 机器学习——数据预处理正则化Normalizer模型
from sklearn.preprocessing import Normalizer #数据预处理正则化Normalizer模型 def test_Normalizer(): X=[[1,2,3, ...
- 吴裕雄 python 机器学习——数据预处理标准化MaxAbsScaler模型
from sklearn.preprocessing import MaxAbsScaler #数据预处理标准化MaxAbsScaler模型 def test_MaxAbsScaler(): X=[[ ...
- 吴裕雄 python 机器学习——数据预处理标准化StandardScaler模型
from sklearn.preprocessing import StandardScaler #数据预处理标准化StandardScaler模型 def test_StandardScaler() ...
- 吴裕雄 python 机器学习——数据预处理标准化MinMaxScaler模型
from sklearn.preprocessing import MinMaxScaler #数据预处理标准化MinMaxScaler模型 def test_MinMaxScaler(): X=[[ ...
- 吴裕雄 python 机器学习——支持向量机线性分类LinearSVC模型
import numpy as np import matplotlib.pyplot as plt from sklearn import datasets, linear_model,svm fr ...
- 吴裕雄 python 机器学习——数据预处理字典学习模型
from sklearn.decomposition import DictionaryLearning #数据预处理字典学习DictionaryLearning模型 def test_Diction ...
- 吴裕雄 python 机器学习——数据预处理流水线Pipeline模型
from sklearn.svm import LinearSVC from sklearn.pipeline import Pipeline from sklearn import neighbor ...
随机推荐
- XXE攻防——XML外部实体注入
XXE攻防——XML外部实体注入 转自腾讯安全应急响应中心 一.XML基础知识 XML用于标记电子文件使其具有结构性的标记语言,可以用来标记数据.定义数据类型,是一种允许用户对自己的标记语言进行定义的 ...
- VC++读写*.ini配置文件
ini文件(即Initialization file),这种类型的文件中通常存放的是一个程序的初始化信息.ini文件由若干个节(Section)组成,每个Section由若干键(Key)组成,每个Ke ...
- java字符串类型和时间类型的转换
类型转换 //reqeust.getParameter获取字符串直接赋值 1 public static Date date(String date_str) { try { Calendar zca ...
- 100个常用的linux命令(转)
来源:JavaRanger – javaranger.com http://www.javaranger.com/archives/907 1,echo “aa” > test.txt 和 ...
- 微信小程序调用api接口
请求的第三方微信url大概有3种 1)$url = "https://api.weixin.qq.com/sns/oauth2/access_token?appid=$appid&s ...
- 在tornado中使用异步mysql操作
在使用tornado框架进行开发的过程中,发现tornado的mysql数据库操作并不是一步的,造成了所有用户行为的堵塞.tornado本身是一个异步的框架,要求所有的操作都应该是异步的,但是数据库这 ...
- Linux中Elasticsearch集群部署
1.下载安装包elasticsearch-6.3.1 安装包自己下载,网上很多 2.安装位置在cd /usr/local/elasticsearch/目录下 3.因为ES使用root权限运行会报错, ...
- WEB中需求分析应该考虑的问题
一. 针对用户群体要考虑因素 1.用户年龄 2.选择素材 3.网站布局 4.颜色搭配 5. 用户体验及动效 6.功能便捷 用户需求.用户兴趣爱好.性格.职业.教育水平高低.消费观念.PC端和移动端哪一 ...
- Apache httpd Server Notes
1. httpd启动.停止以及重启 启动: apachectl –f $PATH_TO_CONF/httpd.conf 停止及重启 apachectl –k stop/restart/graceful ...
- python爬虫学习笔记(1)
一.请求一个网页内容打印 爬取某个网页: from urllib import request # 需要爬取的网页 url = "https://mbd.baidu.com/newspage ...