
Hadoop(20)-MapReduce框架原理-OutputFormat
1.outputFormat接口实现类
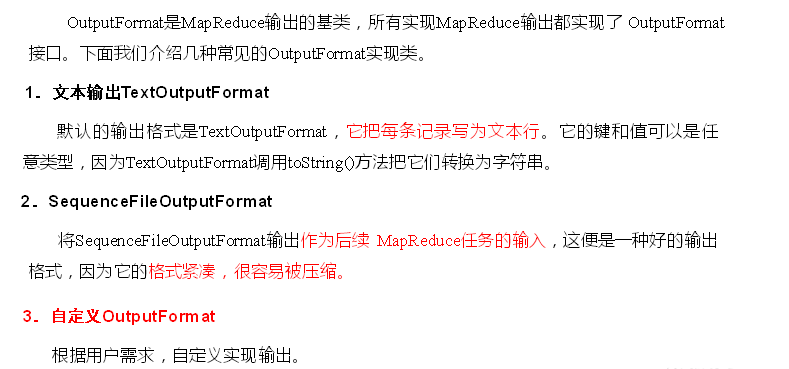
2.自定义outputFormat
步骤:
1). 定义一个类继承FileOutputFormat
2). 定义一个类继承RecordWrite,重写write方法
3. 案例
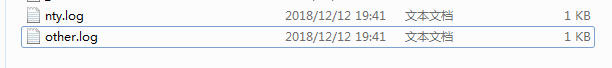
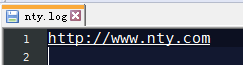
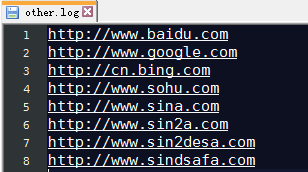
有一个log文件,将包含nty的输出到nty.log文件,其他的输出到other.log
http://www.baidu.com

http://www.google.com

http://cn.bing.com

http://www.nty.com

http://www.sohu.com

http://www.sina.com

http://www.sin2a.com

http://www.sin2desa.com

http://www.sindsafa.com
自定义类继承FileOutputFormat
package com.nty.outputFormat;

import org.apache.hadoop.io.LongWritable;

import org.apache.hadoop.io.Text;

import org.apache.hadoop.mapreduce.RecordWriter;

import org.apache.hadoop.mapreduce.TaskAttemptContext;

import org.apache.hadoop.mapreduce.lib.output.FileOutputFormat;

import java.io.IOException;

/**

 * author nty

 * date time 2018-12-12 19:28

 */

public class FilterOutputFormat extends FileOutputFormat<LongWritable, Text> {

    @Override

    public RecordWriter<LongWritable, Text> getRecordWriter(TaskAttemptContext job) throws IOException, InterruptedException {

        FilterRecordWrite frw = new FilterRecordWrite();

        frw.init(job);

        return frw;

    }

}
自定义RecordWriter,重写write
package com.nty.outputFormat;

import org.apache.hadoop.fs.FSDataOutputStream;

import org.apache.hadoop.fs.FileSystem;

import org.apache.hadoop.fs.Path;

import org.apache.hadoop.io.IOUtils;

import org.apache.hadoop.io.LongWritable;

import org.apache.hadoop.io.Text;

import org.apache.hadoop.mapreduce.RecordWriter;

import org.apache.hadoop.mapreduce.TaskAttemptContext;

import org.apache.hadoop.mapreduce.lib.output.FileOutputFormat;

import java.io.IOException;

/**

 * author nty

 * date time 2018-12-12 19:29

 */

public class FilterRecordWrite extends RecordWriter<LongWritable, Text> {

    private FSDataOutputStream nty;

    private FSDataOutputStream other;

    //将job通过参数传递过来

    public void init(TaskAttemptContext job) throws IOException {

        String outDir = job.getConfiguration().get(FileOutputFormat.OUTDIR);

        FileSystem fileSystem = FileSystem.get(job.getConfiguration());

        nty = fileSystem.create(new Path(outDir + "/nty.log"));

        other = fileSystem.create(new Path(outDir + "/other.log"));

    }

    @Override

    public void write(LongWritable key, Text value) throws IOException, InterruptedException {

        String address = value.toString() + "\r\n";

        if(address.contains("nty")) {

            nty.write(address.getBytes());

        } else {

            other.write(address.getBytes());

        }

    }

    @Override

    public void close(TaskAttemptContext context) throws IOException, InterruptedException {

        //关流

        IOUtils.closeStream(nty);

        IOUtils.closeStream(other);

    }

}
Driver类设置
package com.nty.outputFormat;

import org.apache.hadoop.conf.Configuration;

import org.apache.hadoop.fs.Path;

import org.apache.hadoop.mapreduce.Job;

import org.apache.hadoop.mapreduce.lib.input.FileInputFormat;

import org.apache.hadoop.mapreduce.lib.output.FileOutputFormat;

import java.io.IOException;

/**

 * author nty

 * date time 2018-12-12 19:29

 */

public class FilterDriver {

    public static void main(String[] args) throws IOException, ClassNotFoundException, InterruptedException {

        Configuration configuration = new Configuration();

        Job job = Job.getInstance(configuration);

        job.setJarByClass(FilterDriver.class);

        job.setOutputFormatClass(FilterOutputFormat.class);

        FileInputFormat.setInputPaths(job, new Path("d:\\Hadoop_test"));

        FileOutputFormat.setOutputPath(job, new Path("d:\\Hadoop_test_out"));

        boolean b = job.waitForCompletion(true);

        System.exit(b ? 0 : 1);

    }

}
输出结果
Hadoop(20)-MapReduce框架原理-OutputFormat的更多相关文章
- [Hadoop] - 自定义Mapreduce InputFormat&OutputFormat
在MR程序的开发过程中,经常会遇到输入数据不是HDFS或者数据输出目的地不是HDFS的,MapReduce的设计已经考虑到这种情况,它为我们提供了两个组建,只需要我们自定义适合的InputFormat ...
- Hadoop(17)-MapReduce框架原理-MapReduce流程,Shuffle机制,Partition分区
MapReduce工作流程 1.准备待处理文件 2.job提交前生成一个处理规划 3.将切片信息job.split,配置信息job.xml和我们自己写的jar包交给yarn 4.yarn根据切片规划计 ...
- Hadoop(18)-MapReduce框架原理-WritableComparable排序和GroupingComparator分组
1.排序概述 2.排序分类 3.WritableComparable案例 这个文件,是大数据-Hadoop生态(12)-Hadoop序列化和源码追踪的输出文件,可以看到,文件根据key,也就是手机号进 ...
- Hadoop(16)-MapReduce框架原理-自定义FileInputFormat
1. 需求 将多个小文件合并成一个SequenceFile文件(SequenceFile文件是Hadoop用来存储二进制形式的key-value对的文件格式),SequenceFile里面存储着多个文 ...
- Hadoop(12)-MapReduce框架原理-Hadoop序列化和源码追踪
1.什么是序列化 2.为什么要序列化 3.为什么不用Java的序列化 4.自定义bean对象实现序列化接口(Writable) 在企业开发中往往常用的基本序列化类型不能满足所有需求,比如在Hadoop ...
- Hadoop(13)-MapReduce框架原理--Job提交源码和切片源码解析
1.MapReduce的数据流 1) Input -> Mapper阶段 这一阶段的主要分工就是将文件切片和把文件转成K,V对 输入源是一个文件,经过InputFormat之后,到了Mapper ...
- MapReduce框架原理-OutputFormat工作原理
OutputFormat概述 OutputFormat主要是用来指定MR程序的最终的输出数据格式 . 默认使用的是TextOutputFormat,默认是将数据一行写一条数据,并且把数据放到指定的输出 ...
- Hadoop(19)-MapReduce框架原理-Combiner合并
1. Combiner概述 2. 自定义Combiner实现步骤 1). 定义一个Combiner继承Reducer,重写reduce方法 public class WordcountCombiner ...
- Hadoop(15)-MapReduce框架原理-FileInputFormat的实现类
1. TextInputFormat 2.KeyValueTextInputFormat 3. NLineInputFormat
随机推荐
- XUtils3 的 环境搭建与简单使用
XUtils3 的 环境搭建 环境搭建三部曲 ----------------------- 说明 : author 修雨轩陈 使用andorid Studio 已经创建了一个项目 并且自己需要使用 ...
- jQuery替换已存在于元素element上的事件event
<html><head><script type="text/javascript" src="/jquery/jquery.js" ...
- HCNA实验OSPF基础
1.拓扑图 方法: 1.配置接口IP 2.配置OSPF协议: [R2]ospf 100 [R2-ospf-100]area 0 [R2-ospf-100-area-0.0.0.0]network 12 ...
- Oracle数据库克隆后temp文件因路径变化无法找到问题
Oracle数据库克隆后temp文件因路径变化无法找到出现如下报错Errors in filexxxx.trc:ORA-01157: cannot identify/lock data file xx ...
- March 1 2017 Week 9 Wednesday
If you are serious giving up something, giving up is not serious at all. 如果你慎重地决定要放弃,那么放弃本身就没什么大不了的. ...
- makefile 编译指定目录
makefile 编译指定目录 sub1=test1 sub2=test2 subs = sub1 sub2 SUBDIRS =$(foreach i, $(subs), $($(i))) .PHON ...
- [转]查找问题的利器 - Git Bisect
转自:http://gitbook.liuhui998.com/5_4.html 假设你在项目的'2.6.18'版上面工作, 但是你当前的代码(master)崩溃(crash)了. 有时解决这种问题的 ...
- note04-计算机网络
4.WLAN无线局域网(wareless local area network) IEEE802.11无线以太网协议标准 基础服务集合BSS 基站AP 服务服务集合标识SSID 即wifi名 分配系统 ...
- BZOJ4001:[TJOI2015]概率论(卡特兰数,概率期望)
Description Input 输入一个正整数N,代表有根树的结点数 Output 输出这棵树期望的叶子节点数.要求误差小于1e-9 Sample Input 1 Sample Output 1. ...
- 2018.12.1 web项目中解决乱码问题的一个工具类
<!-- 配置一个过滤器 编码格式的过滤器 --> <filter> <filter-name>encodeFilter</filter-name> & ...