
PyQuery爬取历史天气信息
1.准备工作:
网址:https://lishi.tianqi.com/xian/index.html
爬虫类库:PyQuery,requests
2.网页分析:

红线部分可更改为需要爬取的城市名,如:beijing

红框选中部分即为我们所需要爬取的每个月份的信息. 目测应该是ui li,使用Chrome F12 查看下源代码
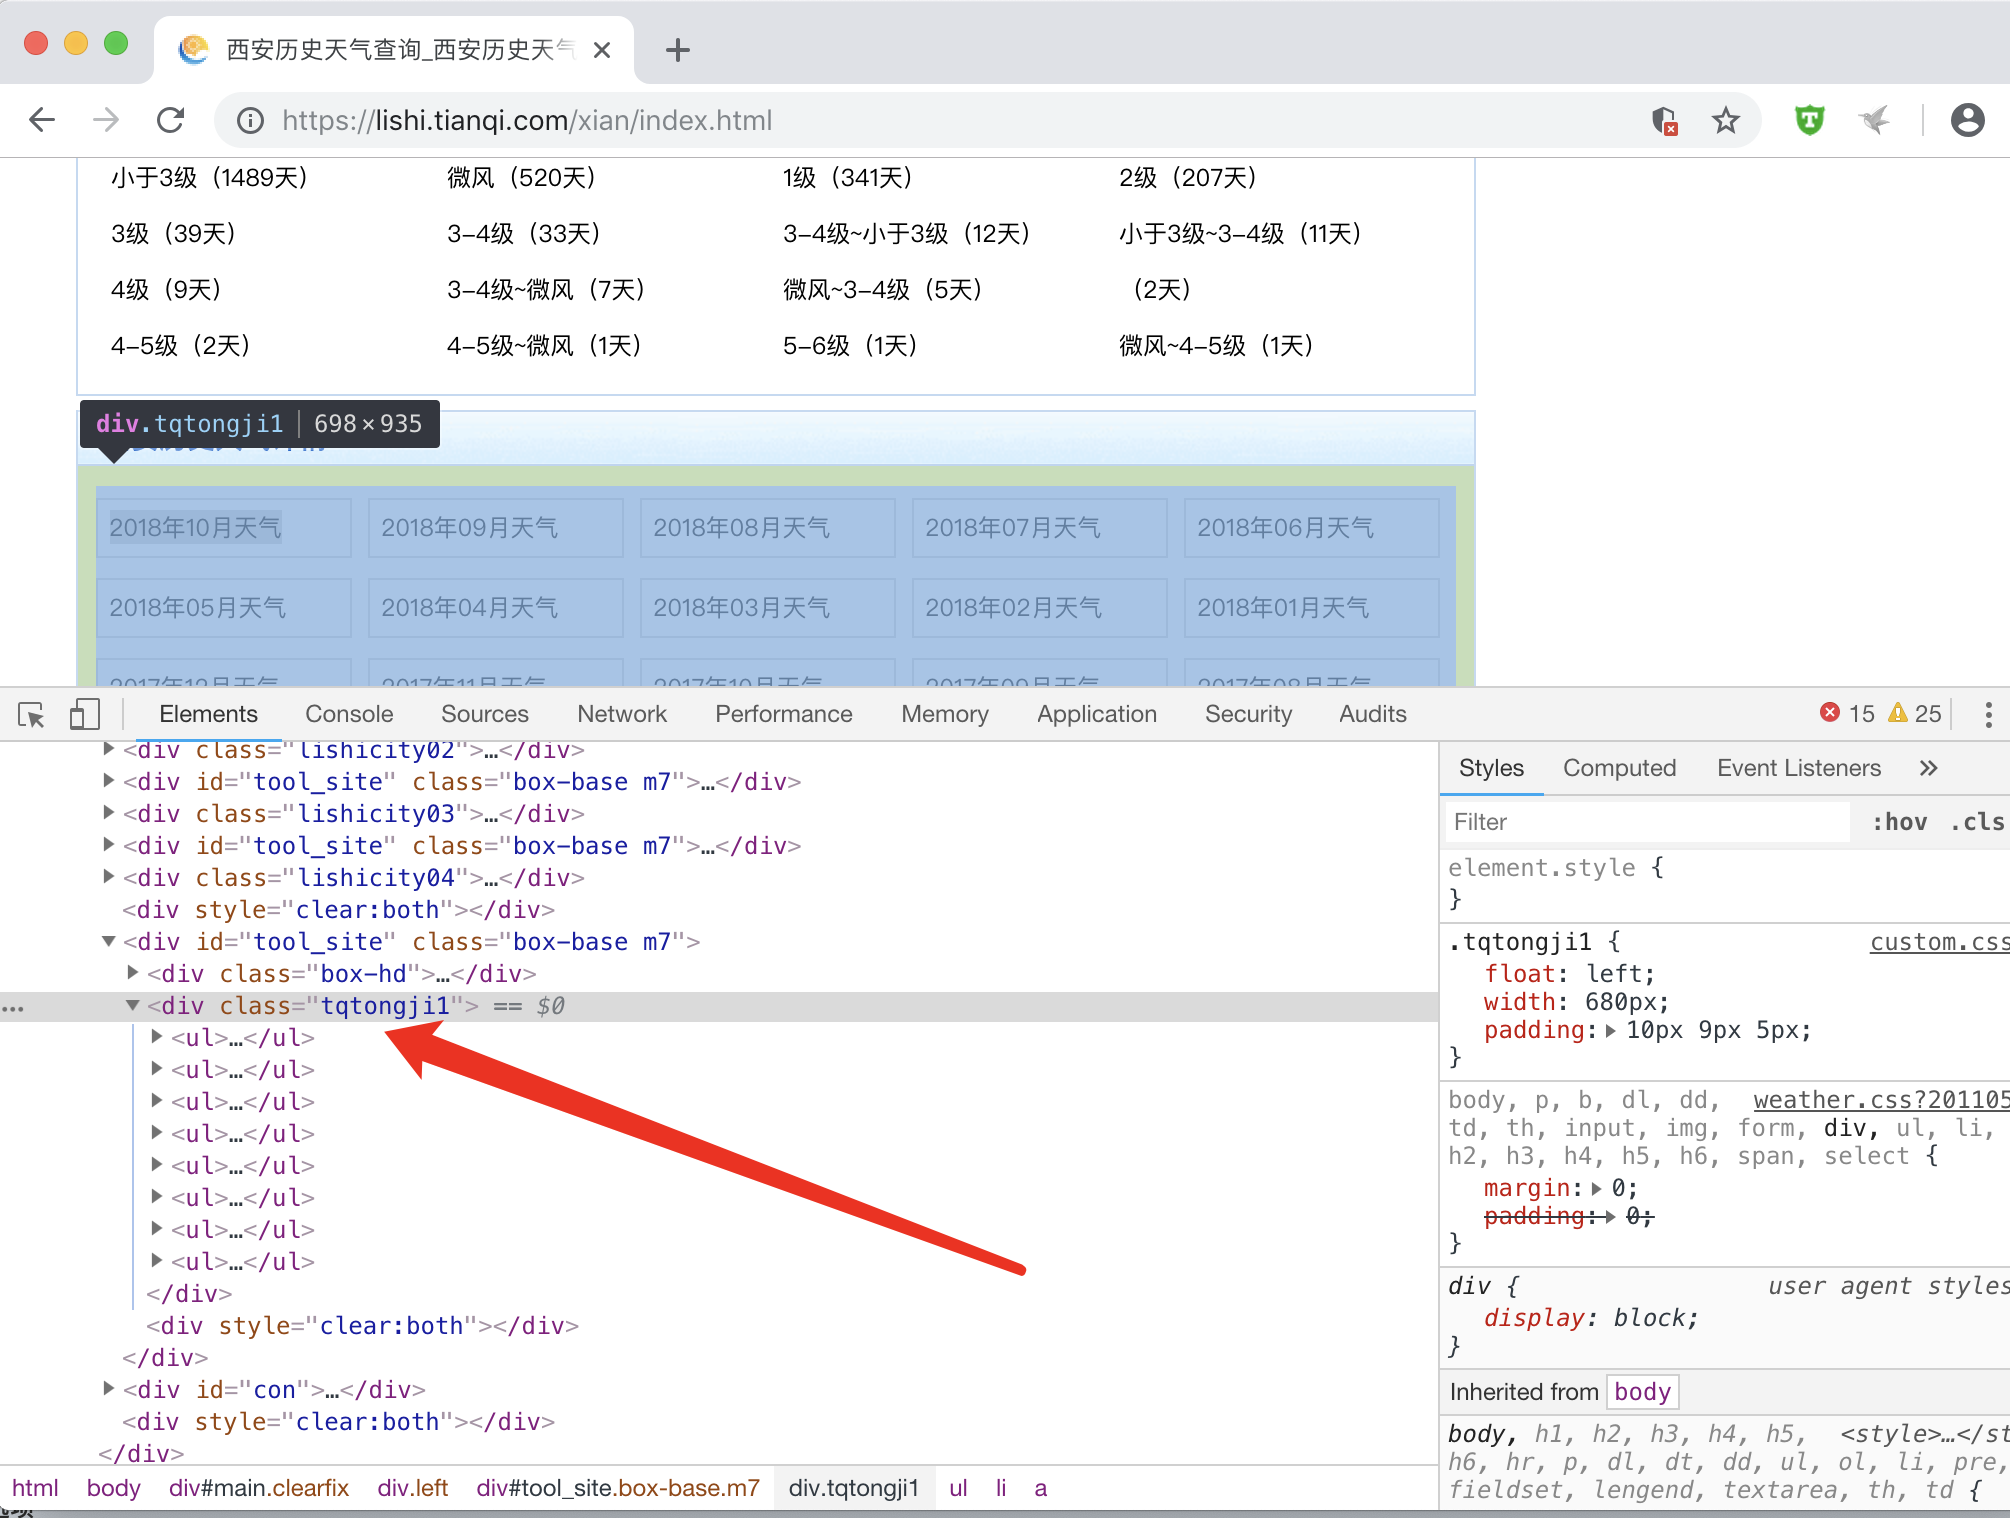
PyQuery的css 选择器可以起床了..
莫慌莫慌。在瞅瞅具体月份点击进入后的页面效果
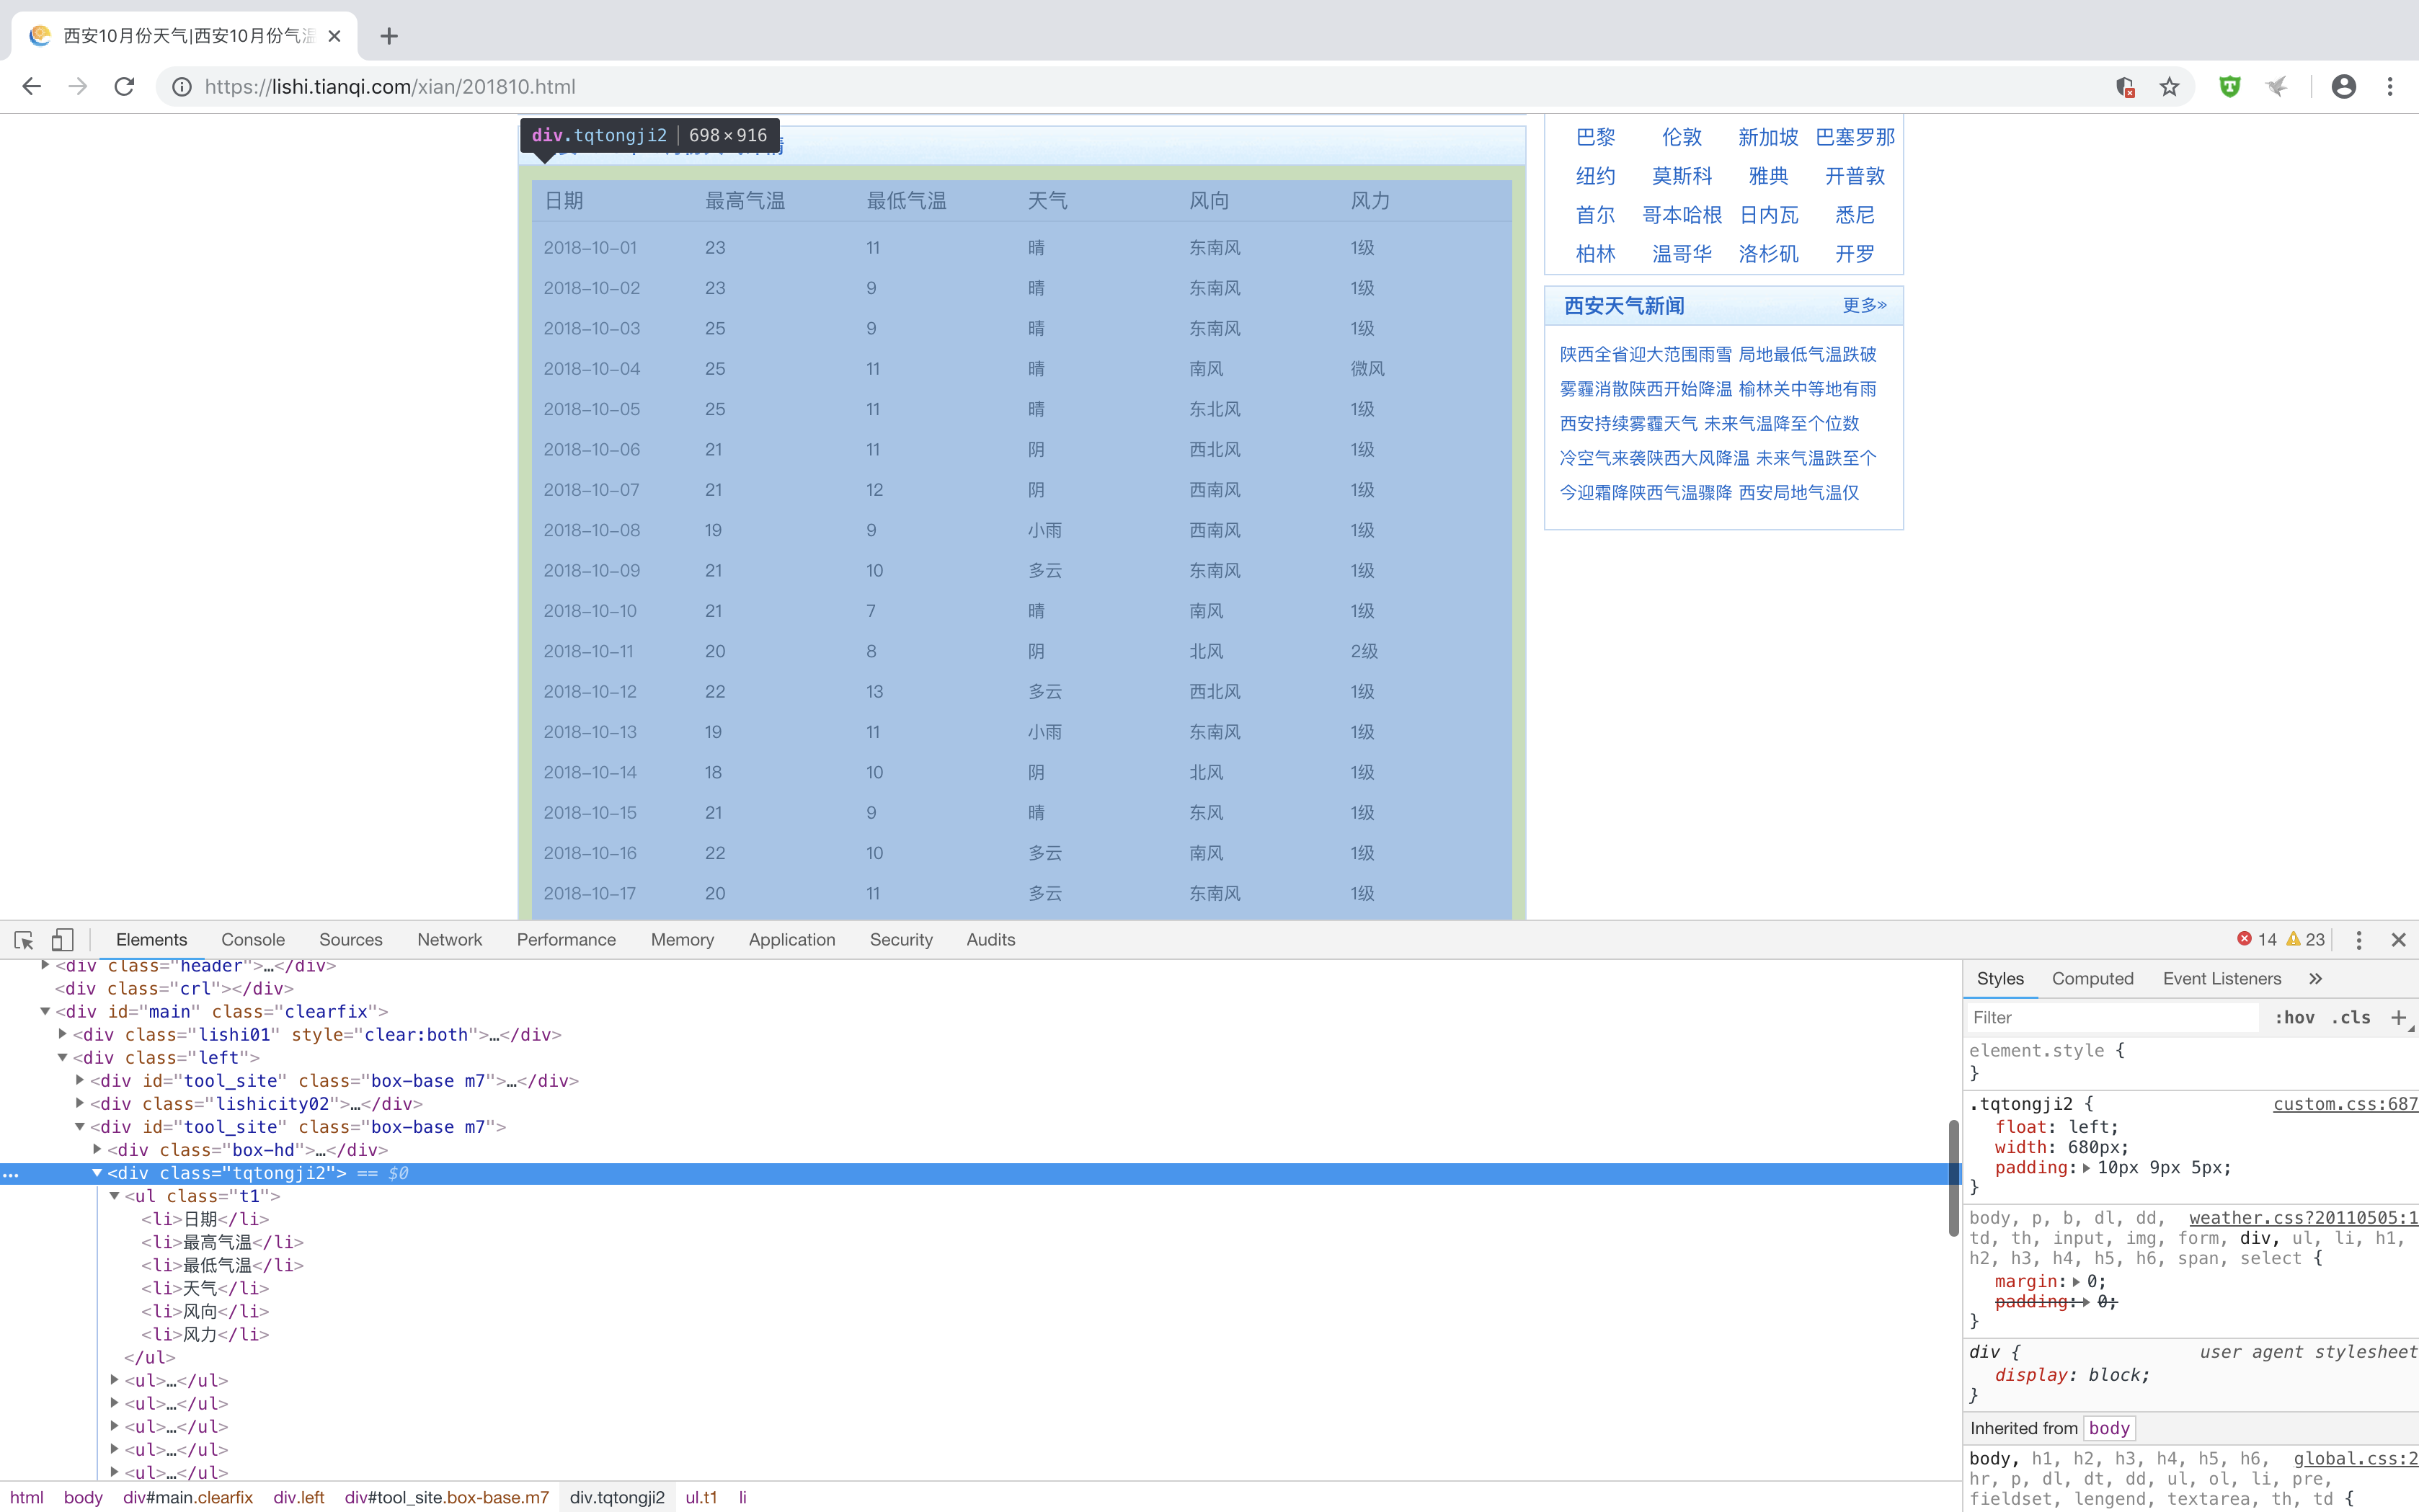
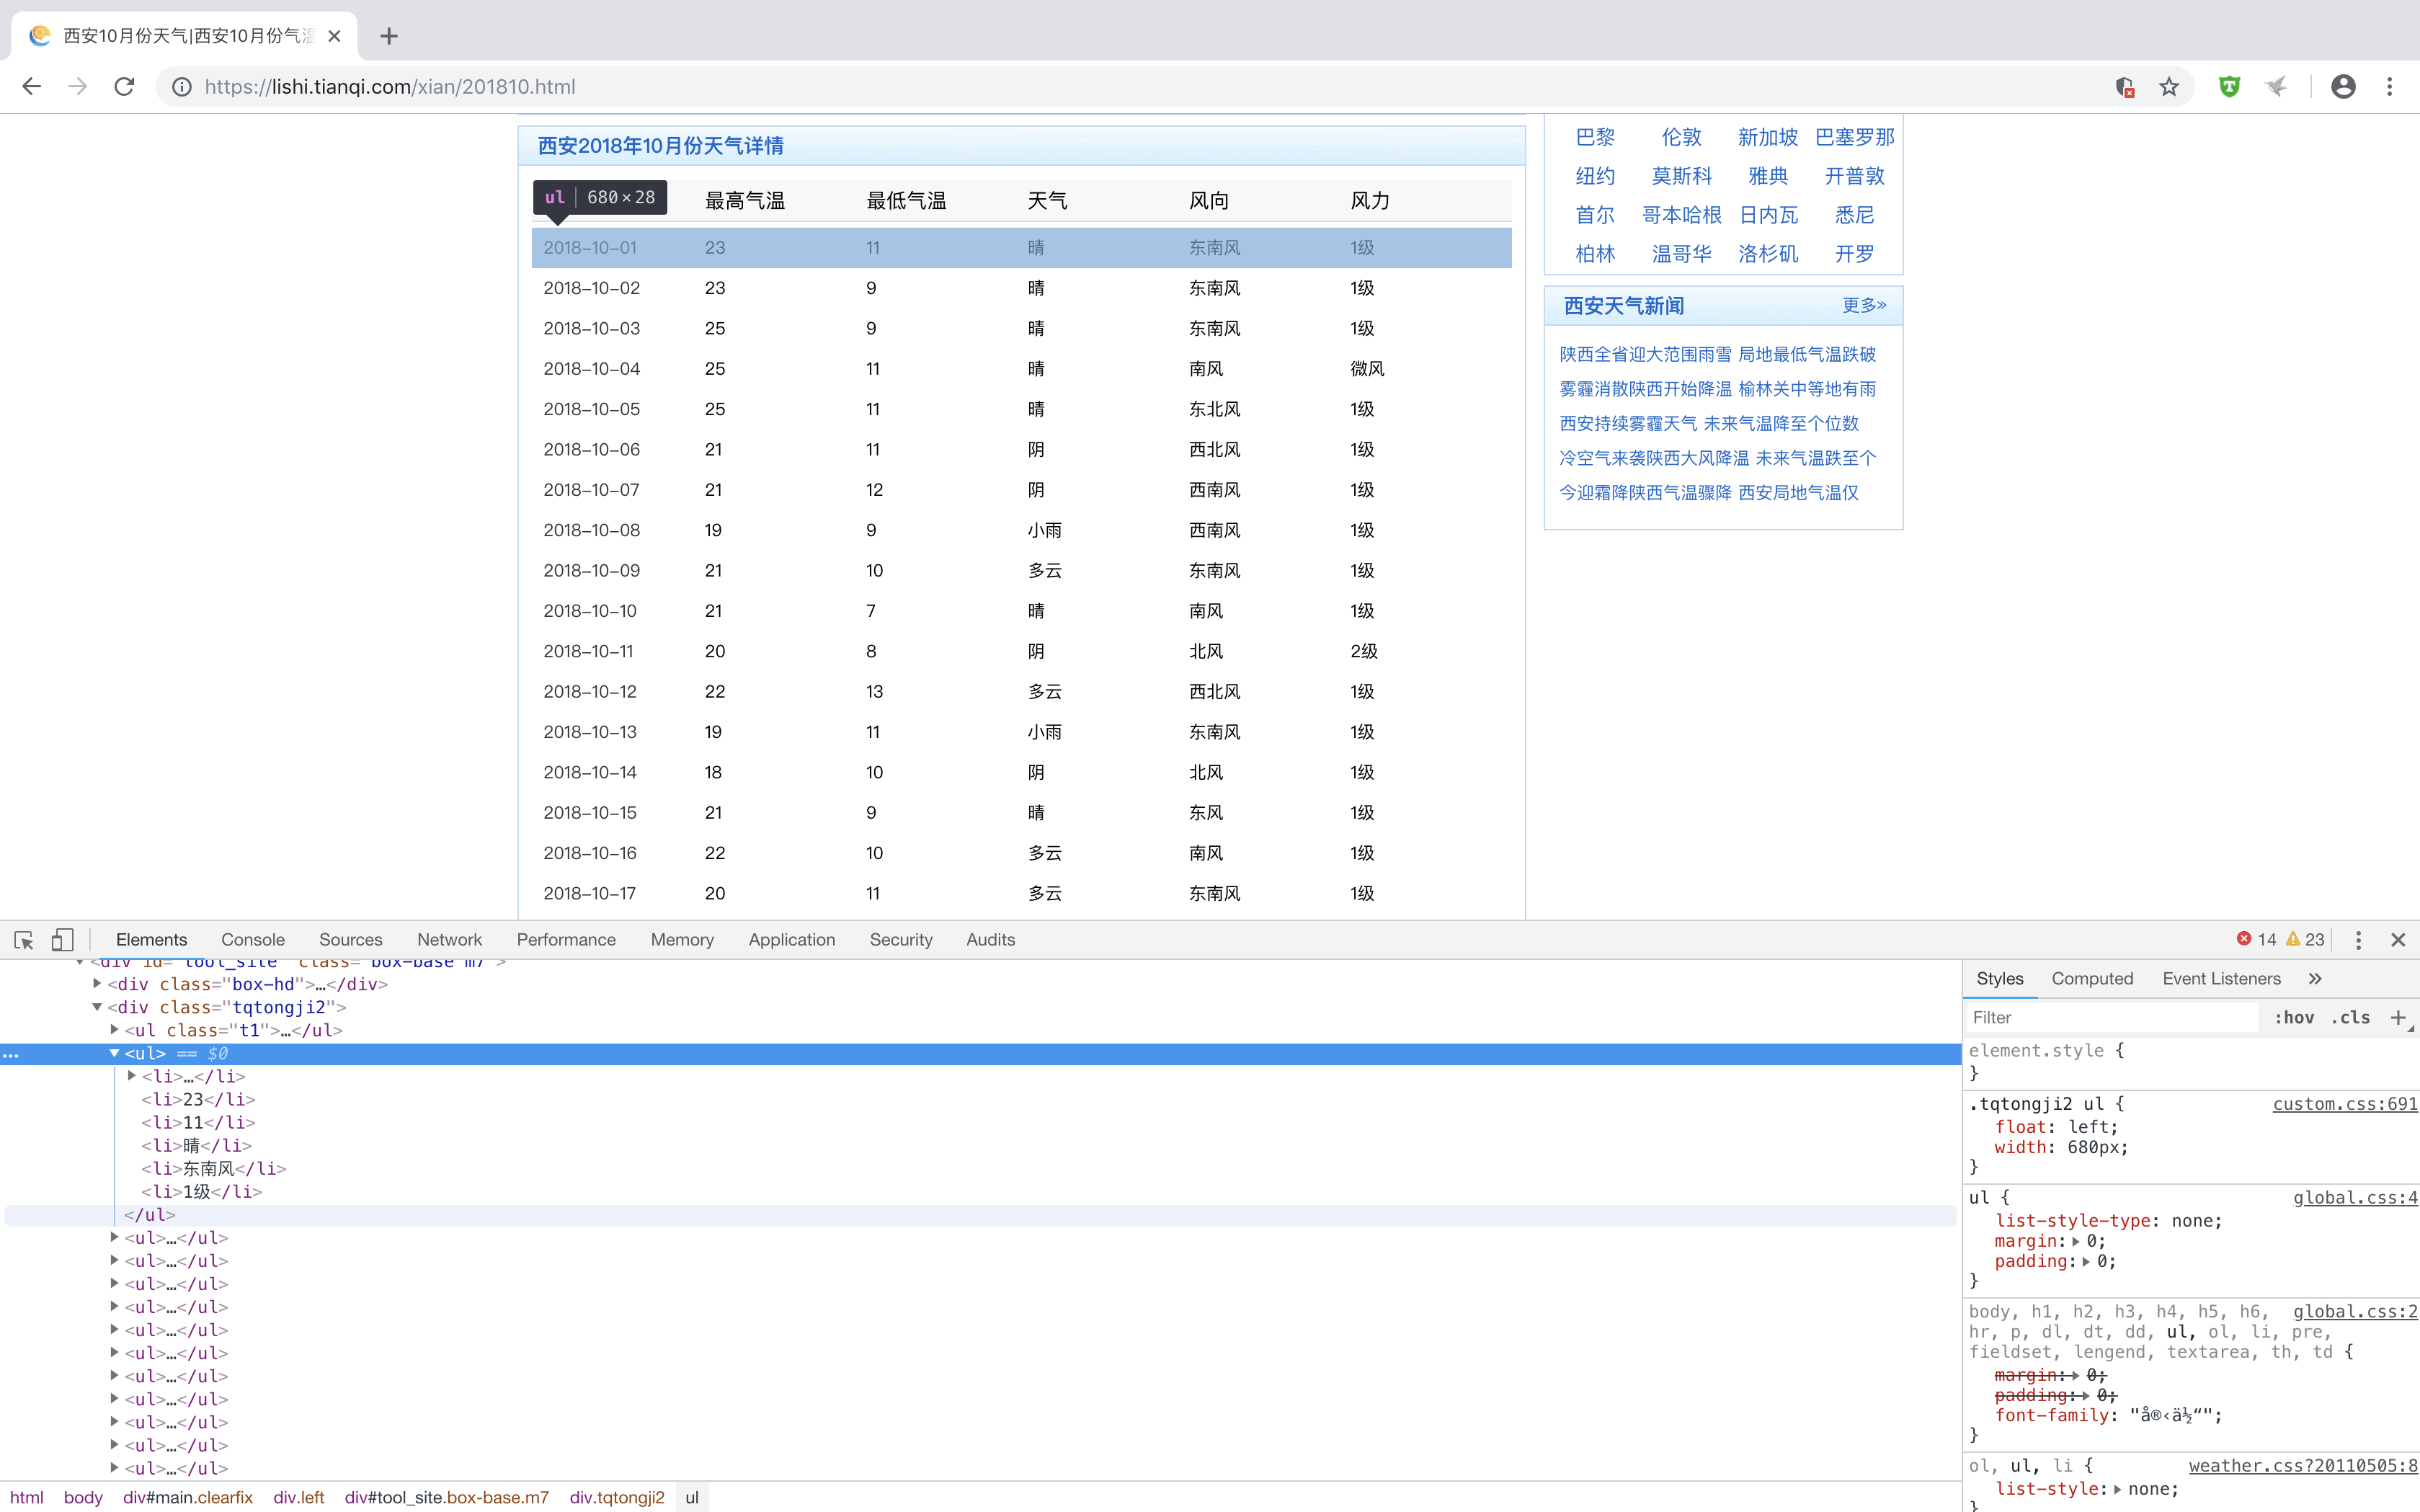
所有的具体每一天的天气信息都被包裹在ul li..
PyQuery.. 开工..
 # 获取所有的月份的a标签连接。

 def get_html():

     links = []

     url = 'https://lishi.tianqi.com/xian/index.html'

     r1 = requests.get(url,headers)

     html_doc = pq(r1.text)

     ul = html_doc('.tqtongji1 > ul:nth-child(1)')

     lis = ul('li').items()

     for li in lis:

         a = li('a')

         links.append(a.attr('href'))

     return links
# 获取详细页的具体天气信息

def get_detail(url):

    r1 = requests.get(url,headers)

    html_doc = pq(r1.text)

    uls = html_doc('.tqtongji2').find('ul')

    lis = uls.items('li')

    list = []

    l = '.'.join(li.text() for li in lis).split('.')

    # 由于标题信息只有['日期', '最高气温', '最低气温', '天气', '风向', '风力']所以需要字符串截取

    for i in range(len(l)):

        if i%6 == 0:

            temp = l[i:i+5]

            list.append(temp)

    return list
 # 保存至weather.csv

 def save_to_csv(data):

     with open('weather.csv','a') as csv_file:

         writer = csv.writer(csv_file)

         for row in data:

             writer.writerow(row)
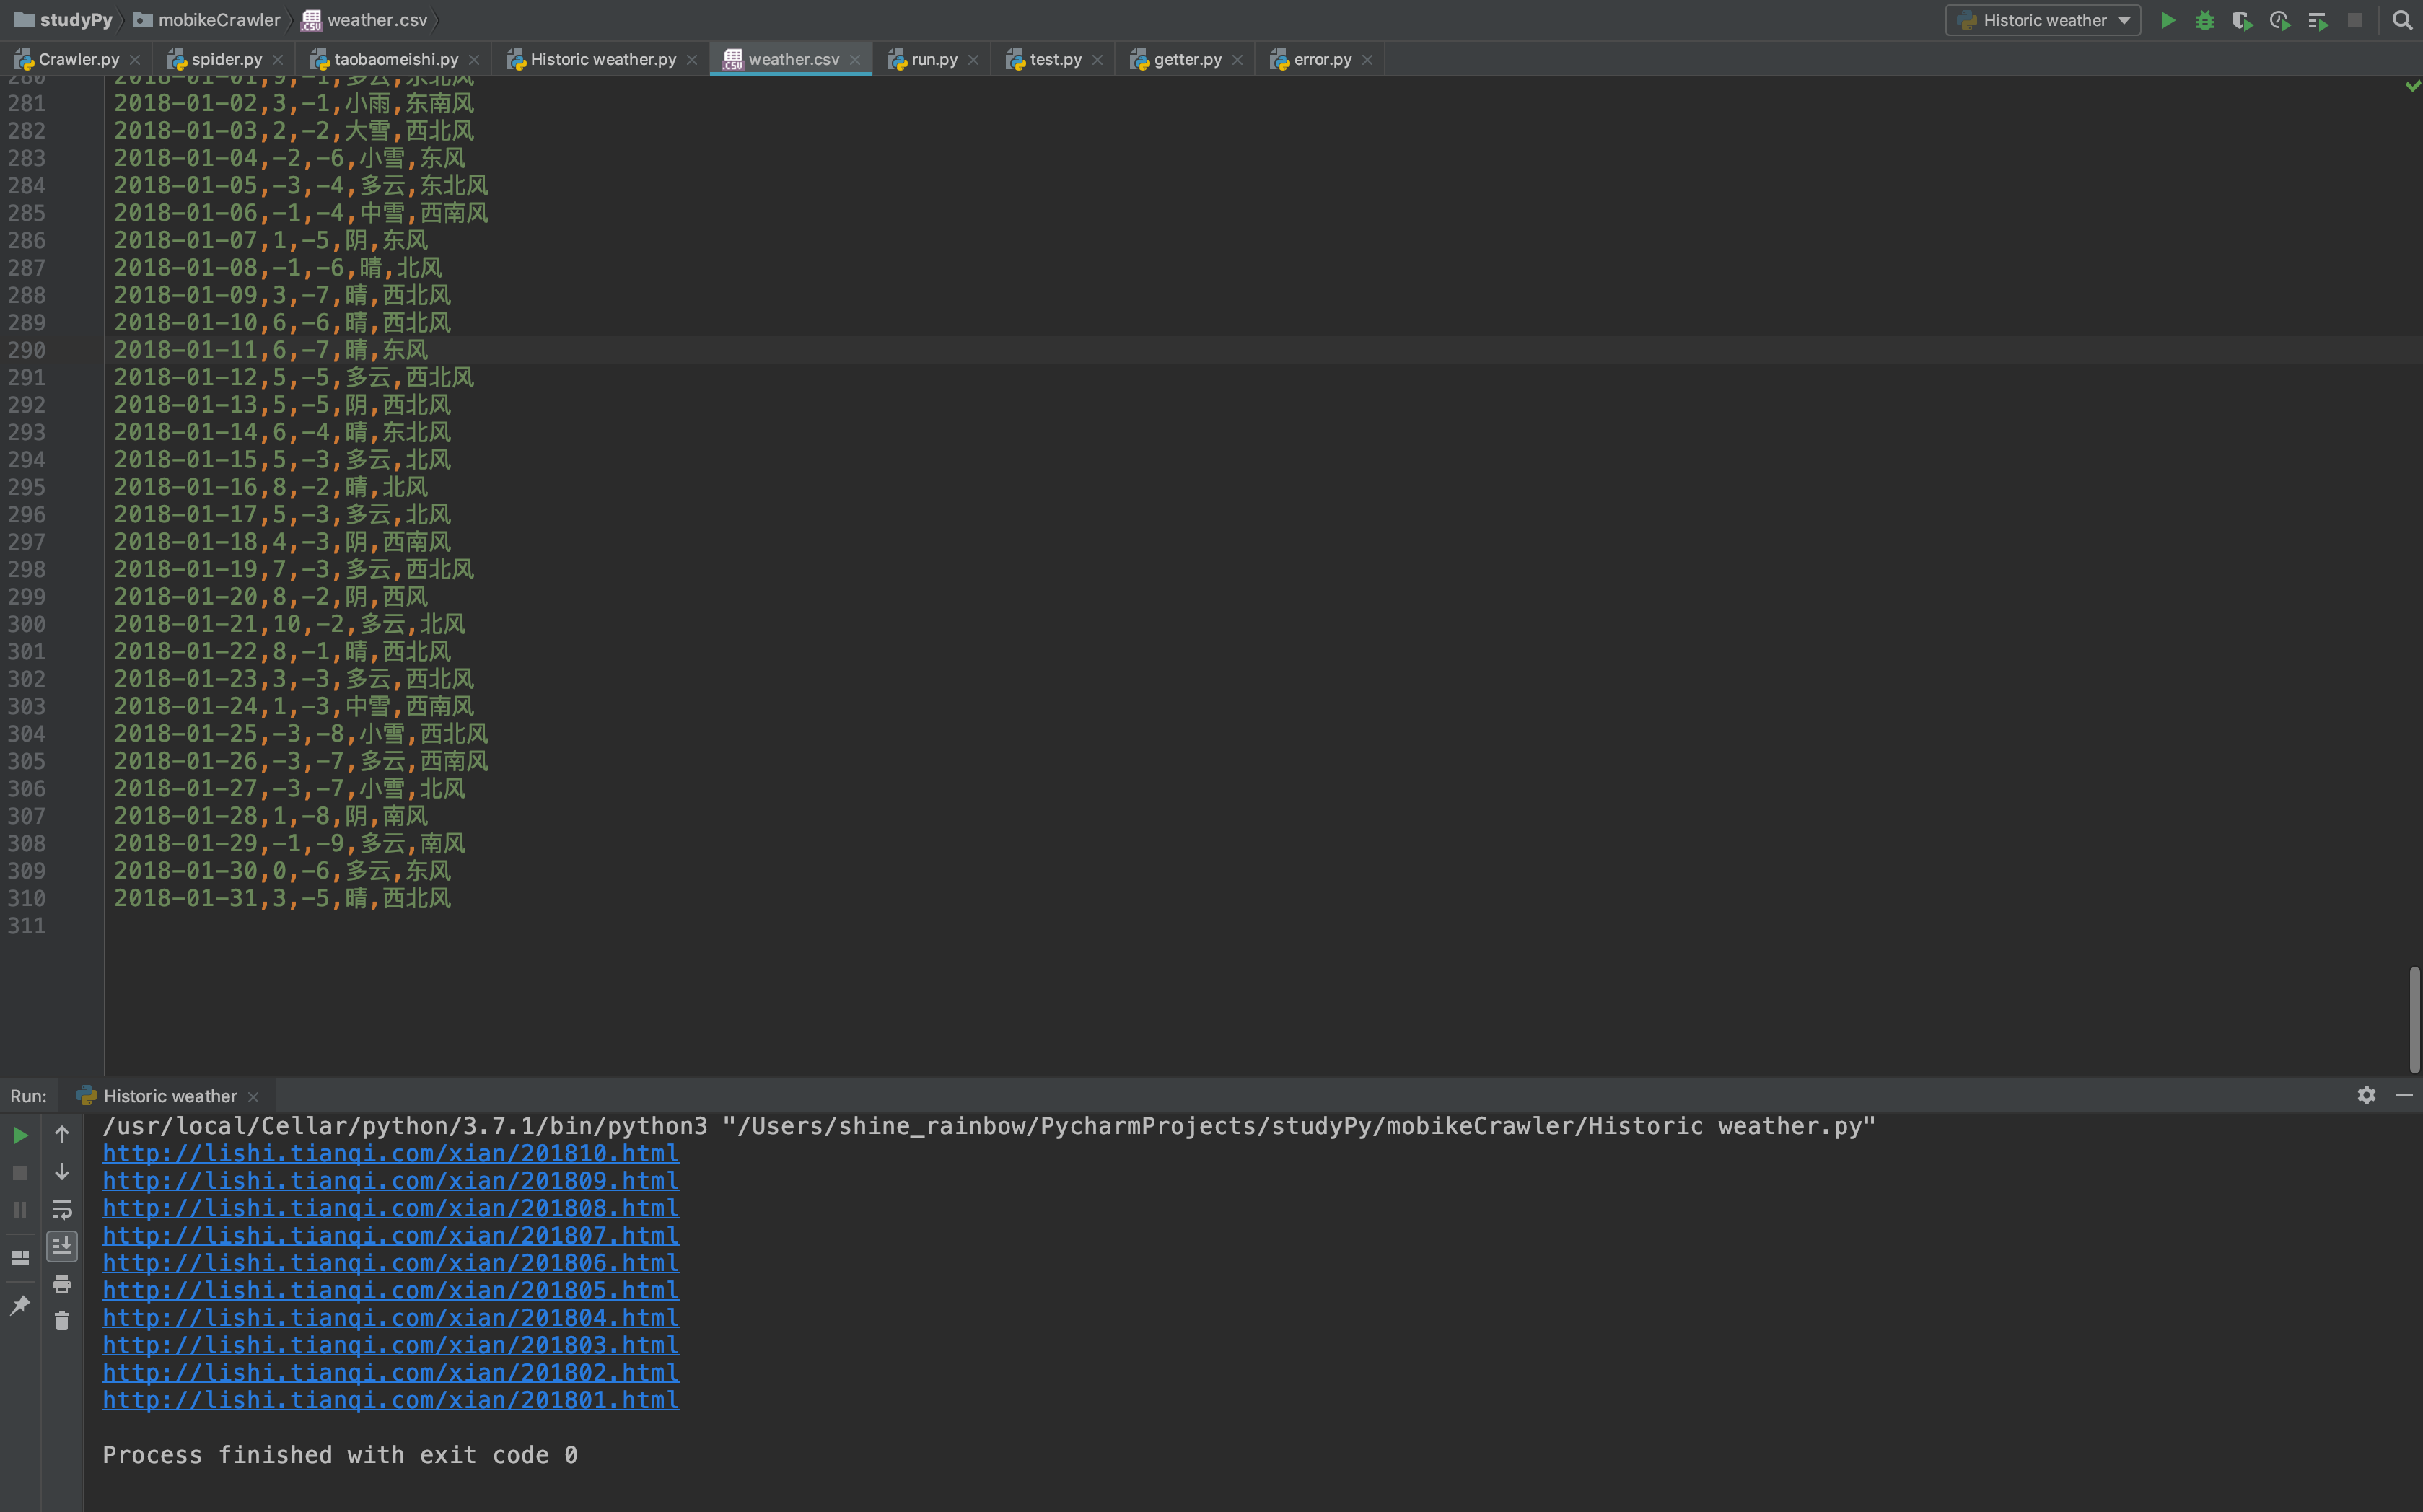
考虑到需要源代码的小伙伴, 已上传至github.. https://github.com/shinefairy/spider/
git clone https://github.com/shinefairy/spider
end~
PyQuery爬取历史天气信息的更多相关文章
- PHP爬取历史天气
PHP爬取历史天气 PHP作为宇宙第一语言,爬虫也是非常方便,这里爬取的是从天气网获得中国城市历史天气统计结果. 程序架构 main.php <?php include_once(". ...
- python 爬取历史天气
python 爬取历史天气 官网:http://lishi.tianqi.com/luozhuangqu/201802.html # encoding:utf-8 import requests fr ...
- Scrapy实战篇(五)之爬取历史天气数据
本篇文章我们以抓取历史天气数据为例,简单说明数据抓取的两种方式: 1.一般简单或者较小量的数据需求,我们以requests(selenum)+beautiful的方式抓取数据 2.当我们需要的数据量较 ...
- python爬虫抓取哈尔滨天气信息(静态爬虫)
python 爬虫 爬取哈尔滨天气信息 - http://www.weather.com.cn/weather/101050101.shtml 环境: windows7 python3.4(pip i ...
- python爬取豆瓣视频信息代码
目录 一:代码 二:结果如下(部分例子) 这里是爬取豆瓣视频信息,用pyquery库(jquery的python库). 一:代码 from urllib.request import quote ...
- 一起学爬虫——使用selenium和pyquery爬取京东商品列表
layout: article title: 一起学爬虫--使用selenium和pyquery爬取京东商品列表 mathjax: true --- 今天一起学起使用selenium和pyquery爬 ...
- python爬虫实战(六)--------新浪微博(爬取微博帐号所发内容,不爬取历史内容)
相关代码已经修改调试成功----2017-4-13 详情代码请移步我的github:https://github.com/pujinxiao/sina_spider 一.说明 1.目标网址:新浪微博 ...
- python3爬取墨迹天气并发送给微信好友,附源码
需求: 1. 爬取墨迹天气的信息,包括温湿度.风速.紫外线.限号情况,生活tips等信息 2. 输入需要查询的城市,自动爬取相应信息 3. 链接微信,发送给指定好友 思路比较清晰,主要分两块,一是爬虫 ...
- 初识python 之 爬虫:爬取中国天气网数据
用到模块: 获取网页并解析:import requests,html5lib from bs4 import BeautifulSoup 使用pyecharts的Bar可视化工具"绘制图表& ...
随机推荐
- css设计丝带
<!DOCTYPE html><html lang="zh-CN"><head><meta charset="UTF-8&quo ...
- 应用安全-Web安全-漏洞修复方案整理
通过HTTP头部字段防御措施整理 X-Frame-Options #反劫持 X-XSS-Protection #开启浏览器防XSS功能 Set X-Frame-Options CSP X-Conte ...
- Uncaught TypeError: Cannot set property onclick' of null
如果出现以上问题,只需要把<script src="xxx.js"></script> 移动到最后,</body>的前面;
- hdu1423 最长公共上升子序列
题目传送门 Greatest Common Increasing Subsequence Time Limit: 2000/1000 MS (Java/Others) Memory Limit: ...
- Codeforces 375D D. Tree and Queries
传送门 题意: 给一棵树,每个节点有一个颜色,询问x为根的子树,出现次数大于等于k的颜色个数. 输入格式: 第一行 2 个数 n,m 表示节点数和询问数. 接下来一行 n 个数,第 i 个数 ci ...
- Ajax ——数据解析
Ajax应用中数据解析是非常重要的一件事情.一般服务器返回数据有三种格式:txt , xml, json 1.解析txt 当服务器返回的数据为字符串,则这种Ajax数据 ...
- Error- spark streaming 打包将全部依赖打进去Invalid signature file digest for Manifest main attributes
spark streaming 打包将全部依赖打进去,运行jar包报错:如下 Exception in thread "main" java.lang.SecurityExcept ...
- java类使用
package java04; /* * 通常情况下,一个类不能直接使用,需要创建一个对象,才能使用 * *步骤: * 1.导包:就是指出需要使用的类在什么位置 * import 包名称.类名称: * ...
- linux firewall
一.查看防火墙状态1.首先查看防火墙是否开启,如未开启,需要先开启防火墙并作开机自启 systemctl status firewalld 开启防火墙并设置开机自启 systemctl start f ...
- [BZOJ4826] [HNOI2017] 影魔 单调栈 主席树
题面 因为是一个排列,所以不会有重复的.如果有重复就没法做了.一开始没有仔细看题目想了半天. 发现,如果是第一种情况,那么边界\(l\)和\(r\)就应该分别是整个区间的最大值和次大值. 然后,对于那 ...