
1.记我的第一次python爬虫爬取网页视频
It is my first time to public some notes on this platform, and I just want to improve myself by recording something that I learned everyday.
Partly , I don't know much about network crawler , and that makes me just understanding something that floats on the surface.
But since I was learning three days when I got a method to craw some videos on the web.
I am very excited, I just know how to craw something from the internet to computer hard disk. It is a start, surely, this is the first step, I just got to keep moving.
Step 1: Find a video on the web page, then plays the video online, press the keyboard shortcuts F12, it occurs element-checked page
as the following pictures:
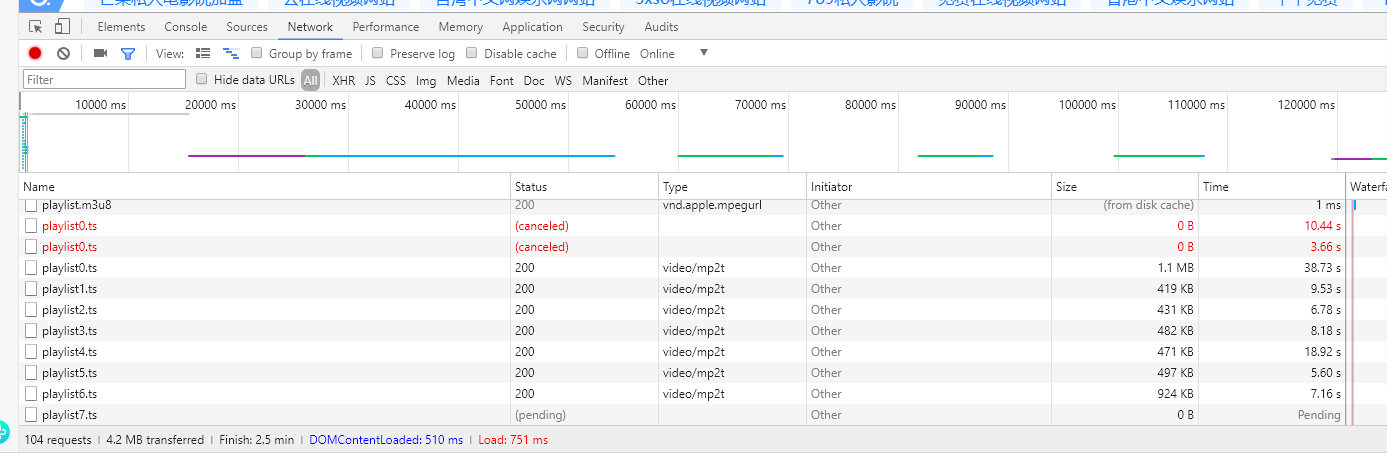
Click .ts file and then you will see the URL, that is the point.

Step 2: Writing python code, as following:
 from multiprocessing import Pool

 import requests

 def demo(i):

     try:

         url = "https://vip.holyshitdo.com/2019/5/8/c2417/playlist%0d.ts"%i

         #simulate browser

         print(url)

         headers={'User-Agent':'Mozilla/5.0 (Windows NT 10.0; Win64; x64) AppleWebKit/537.36 (KHTML, like Gecko) Chrome/63.0.3239.132 Safari/537.36Name','Referer':'http://91.com','Content-Type': 'multipart/form-data; session_language=cn_CN'}

         r = requests.get(url, headers=headers)

         #print(r.content) save the video with binary format

         with open('./mp4/{}'.format(url[-10:]),'wb')as f:

             f.write(r.content)

     except:

         return ""

 if __name__=='__main__':           # program entry

     pool = Pool(10)              # create a process pool

     for i in range(193):

         pool.apply_async(demo,(i,))    # execute

     pool.close()

     pool.join()
Step 3:Running code
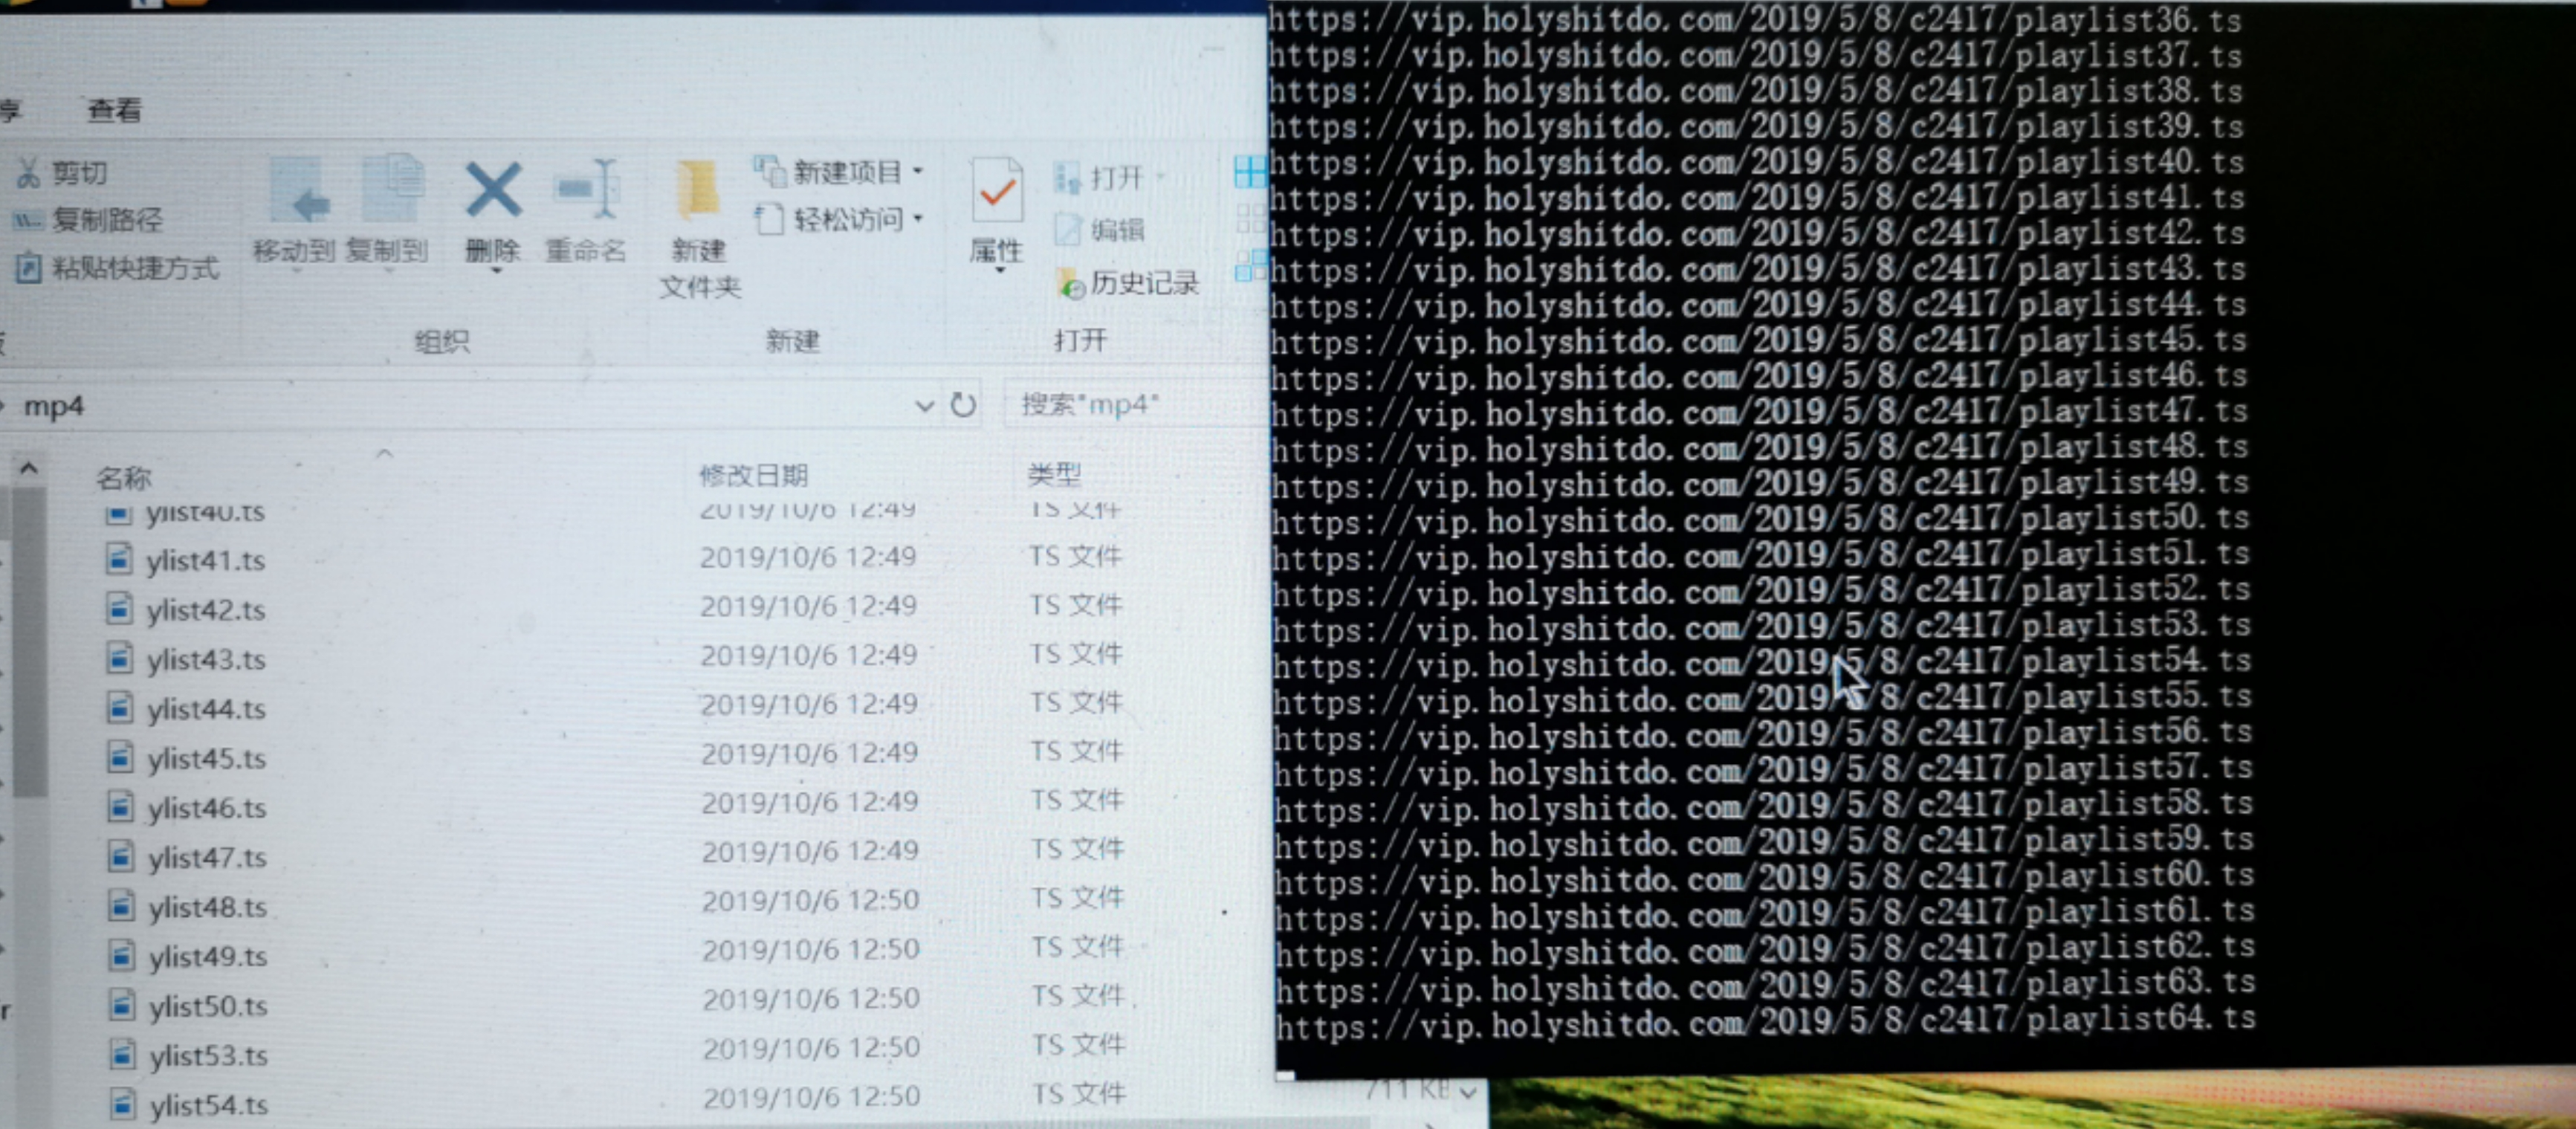
Step 4 : Last but not least, merge .ts fragments into MP4 format.
Get to the terminal interface , under the saved diretory and use command line "copy /b *.ts newfile.mp4"
-------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------
THAT IS ALL FOR NOW, TO BE CONTINUED~( ̄▽ ̄~)~
1.记我的第一次python爬虫爬取网页视频的更多相关文章
- python爬虫——爬取网页数据和解析数据
1.网络爬虫的基本概念 网络爬虫(又称网络蜘蛛,机器人),就是模拟客户端发送网络请求,接收请求响应,一种按照一定的规则,自动地抓取互联网信息的程序.只要浏览器能够做的事情,原则上,爬虫都能够做到. 2 ...
- Python爬虫爬取qq视频等动态网页全代码
环境:py3.4.4 32位 需要插件:selenium BeautifulSoup xlwt # coding = utf-8 from selenium import webdriverfrom ...
- Python爬虫爬取网页图片
没想到python是如此强大,令人着迷,以前看见图片总是一张一张复制粘贴,现在好了,学会python就可以用程序将一张张图片,保存下来. 今天逛贴吧看见好多美图,可是图片有点多,不想一张一张地复制粘贴 ...
- Python爬虫 - 爬取百度html代码前200行
Python爬虫 - 爬取百度html代码前200行 - 改进版, 增加了对字符串的.strip()处理 源代码如下: # 改进版, 增加了 .strip()方法的使用 # coding=utf-8 ...
- 用Python爬虫爬取广州大学教务系统的成绩(内网访问)
用Python爬虫爬取广州大学教务系统的成绩(内网访问) 在进行爬取前,首先要了解: 1.什么是CSS选择器? 每一条css样式定义由两部分组成,形式如下: [code] 选择器{样式} [/code ...
- 使用Python爬虫爬取网络美女图片
代码地址如下:http://www.demodashi.com/demo/13500.html 准备工作 安装python3.6 略 安装requests库(用于请求静态页面) pip install ...
- Python爬虫|爬取喜马拉雅音频
"GOOD Python爬虫|爬取喜马拉雅音频 喜马拉雅是知名的专业的音频分享平台,用户规模突破4.8亿,汇集了有声小说,有声读物,儿童睡前故事,相声小品等数亿条音频,成为国内发展最快.规模 ...
- python爬虫爬取内容中,-xa0,-u3000的含义
python爬虫爬取内容中,-xa0,-u3000的含义 - CSDN博客 https://blog.csdn.net/aiwuzhi12/article/details/54866310
- Python爬虫爬取全书网小说,程序源码+程序详细分析
Python爬虫爬取全书网小说教程 第一步:打开谷歌浏览器,搜索全书网,然后再点击你想下载的小说,进入图一页面后点击F12选择Network,如果没有内容按F5刷新一下 点击Network之后出现如下 ...
随机推荐
- Java实现 蓝桥杯 算法提高VIP Substrings(暴力)
试题 算法提高 Substrings 问题描述 You are given a number of case-sensitive strings of alphabetic characters, f ...
- Java实现 稀疏矩阵乘积
稀疏矩阵乘积 描述 给定两个N × N的稀疏矩阵A和B,其中矩阵A有P个元素非0,矩阵B有Q个元素非0.请计算两个矩阵的乘积C = A × B并且输出C中所有非0的元素. 输入 第一行包含三个整数N, ...
- Java实现 LeetCode 137 只出现一次的数字 II(二)
137. 只出现一次的数字 II 给定一个非空整数数组,除了某个元素只出现一次以外,其余每个元素均出现了三次.找出那个只出现了一次的元素. 说明: 你的算法应该具有线性时间复杂度. 你可以不使用额外空 ...
- java实现第三届蓝桥杯机器人行走
机器人行走 [编程题](满分18分) 某少年宫引进了一批机器人小车.可以接受预先输入的指令,按指令行动.小车的基本动作很简单,只有3种:左转(记为L),右转(记为R),向前走若干厘米(直接记数字). ...
- cuda基础
一:cuda编程模型 1:主机与设备 主机---CPU 设备/处理器---GPU CUDA编程模型如下: GPU多层存储空间结构如图: 2:Kernel函数的定义与调用 A:运行在GPU上,必须通过_ ...
- 容器技术之Docker私有镜像仓库docker-distribution
在前边的博客中我们说到docker的架构由docker客户端.服务端以及仓库组成:docker仓库就是用来存放镜像的地方:其实docker registry我们理解为存放docker镜像仓库的仓库比较 ...
- DevOps系列——Jenkins/Gitlab自动打包部署
前面只说了DevOps的两个基础组件Jenkins和GitLab,客官也不要着急,我们玩就玩的深入一点,Gitlab和Jenkins的各种配置和 插件很多,也够啃一阵子的,不要照着操作一通就感觉万事大 ...
- js原型链、继承、this指向等老生常谈却依然不熟的知识点——记录解析
开始记录学习过程—— 很详细的解析过程——https://juejin.im/post/5c72a1766fb9a049ea3993e6 借鉴阅读——https://github.com/KieSun ...
- 【Navicat】Navicat for MongoDBv15.0.6破解版(附破解教程)
安装包下载链接:https://download.csdn.net/download/l1028386804/12519681 Navicat for MongoDB 15是一款功能十分强大的数据库管 ...
- .net core 部署到windows服务上的方法
前言 Net core 项目部门在Windows有很多种方式,大致有以下几种, dotnet 命令, iis(windowshosts), 一些开源的应用容器(docker ) 基于一些exe 程序, ...